This is the full developer documentation for AskDB
# Open-source NL-to-SQL
for developers.
> Your LLM generates checked, schema-grounded SQL. Your app reviews, approves, logs, and runs it. BYO model, database, embedder, and vector store.
## Install AskDB
$`npx askdb init`
\# OR: npm install askdb
Copy
Next: [Quickstart](quickstart/)·[Install options](install/)·[GitHub](https://github.com/Ygilany/AskDB)
Postgres · MySQL · SQLite · SQL ServerOpen source · Apache 2.0SQL returned · Your app executesNo data leaves your stack
## Why this toolkit exists
[Section titled “Why this toolkit exists”](#why-this-toolkit-exists)
NL-to-SQL isn’t a new problem. Academic research goes back to LUNAR in 1972, and LLM-based generation has been good enough since Codex in 2021. The hard part in production isn’t the LLM call — it’s capturing the business context behind your schema, getting the right enrichment into the prompt, wiring up RAG when the schema is too big to fit, and repeating that work for every new project. AskDB is the toolkit for *that* part.
## What makes AskDB different
[Section titled “What makes AskDB different”](#what-makes-askdb-different)
### Your data never touches the model
AskDB sends the question and your schema artifact — never your rows, your credentials, or your query results. The model writes SQL blind to your data.
### Reviewed schema, your app runs the SQL
Your team authors and reviews the schema context. AskDB returns SQL — your application chooses whether to log it, approve it, or run it.
### Safety guardrails on every query
Every generated query is parsed, scoped, and rejected if it violates the rules your schema declares — read-only, tenant filters, sensitive columns.
### You own the infrastructure and the context
AskDB is a library you wire into your stack. Your model key, your database, your vector store. The schema artifact is a file you commit, not a black box.
## How it works
[Section titled “How it works”](#how-it-works)
1. 01
### Init
Run askdb init to scaffold askdb.config.ts — your provider, database, and model settings, checked in like code.
2. 02
### Introspect
AskDB reads your database (or a Prisma schema file) into a schema artifact: tables, columns, types, and relationships on disk.
3. 03
### Enrich
In Studio, add the descriptions, aliases, business concepts, and sensitive markers that make generation reliable. Test questions as you go.
4. 04
### Use
Call ask() from your app — or POST to the HTTP API. AskDB returns checked SQL; your application logs it, approves it, and runs it through your own pool.
## Embed it in your app
[Section titled “Embed it in your app”](#embed-it-in-your-app)
A few lines of TypeScript: load a schema, ask a question, run the SQL through your own connection pool.
* Config-driven (@askdb/client)
```ts
import { createAskDb } from "@askdb/client";
import { bootstrapAskDbEnv, getAskDbRuntimeConfig } from "@askdb/config";
import { Pool } from "pg";
// Resolve schema, model, and dialect from askdb.config.ts — same config the CLI and Studio use.
bootstrapAskDbEnv({ cwd: process.cwd() });
const askdb = createAskDb({
config: getAskDbRuntimeConfig(), // ai.provider picks the model (npm i @ai-sdk/openai for OpenAI)
schema: { path: "./my-app.schema" }, // or set host.schemaPath in config and omit
});
const pool = new Pool({ connectionString: process.env.DATABASE_URL });
const { sql } = await askdb.ask("Which customers signed up last week?");
// Log or approve `sql` here, then run it through your own pool.
const result = await pool.query(sql);
```
* Direct (Vercel AI SDK)
```ts
import { ask, loadSchema } from "@askdb/core";
import { openai } from "@ai-sdk/openai";
import { Pool } from "pg";
// Load schema once at startup — no config file needed.
const schema = loadSchema("./my-app.schema");
const model = openai("gpt-4o-mini"); // any Vercel AI SDK LanguageModel
const pool = new Pool({ connectionString: process.env.DATABASE_URL });
const { sql } = await ask({
question: "Which customers signed up last week?",
schema,
model,
dialect: "postgres",
});
// Log or approve `sql` here, then run it through your own pool.
const result = await pool.query(sql);
```
## Works with the database you already have
[Section titled “Works with the database you already have”](#works-with-the-database-you-already-have)
### PostgreSQL
`@askdb/postgres`
Reference dialect — new features land here first.
### MySQL
`@askdb/mysql`
First-class dialect and introspection.
### SQLite
`@askdb/sqlite`
First-class dialect — embedded and file-backed, great for dev and tests.
### SQL Server
`@askdb/sqlserver`
First-class T-SQL dialect and introspection.
## What the model sees — and what it doesn’t
[Section titled “What the model sees — and what it doesn’t”](#what-the-model-sees--and-what-it-doesnt)
The model sees
### What crosses the boundary
* The user's question
* Your schema artifact (tables, columns, descriptions you authored)
* Reasoning and SQL it generates
Stays in your stack
### What never leaves
* Your database rows
* Database credentials and connection strings
* Query results returned to your app
* User identifiers, session tokens, anything you don't put in the prompt
## Read next
[Section titled “Read next”](#read-next)
[**Quickstart**Install, introspect, and ask your first question in five minutes.](/quickstart/)[**How AskDB works**The end-to-end flow from question to checked SQL.](/concepts/how-askdb-works/)[**Embed in a Node app**The full TypeScript walkthrough with a real connection pool.](/guides/embed-in-node/)[**Package reference**Every `@askdb/*` package and what it does.](/reference/packages/)
# How AskDB works
> The end-to-end flow from a natural-language question to checked SQL that your application runs.
The pipeline
AskDB is a function that turns a question and a schema artifact into checked SQL. Everything else — execution, approval, audit — happens in your application, not in AskDB.
## The five steps
[Section titled “The five steps”](#the-five-steps)
When you call `ask()` (or the equivalent CLI / HTTP surface), AskDB runs these steps in order:
1. **Load the schema artifact.** A directory, a bundle file, or a parsed `schema.json` — whichever you supply.
2. **Retrieve relevant chunks (optional).** For large schemas, AskDB pulls only the slice of the artifact that’s relevant to the question, using `@askdb/rag`. Smaller schemas skip this step.
3. **Build the prompt.** Physical metadata, any table descriptions you authored, and the selected SQL dialect get assembled into the context the model sees.
4. **Generate.** AskDB calls the model you supplied — any provider compatible with the [Vercel AI SDK](/guides/bring-your-own-model/) — and the model returns SQL. AskDB does not host inference; your key, your billing.
5. **Check.** The returned SQL goes through AskDB’s heuristic guardrails: single statement (with a SQL Server caveat), must start with `SELECT` or `WITH`, no comments, no DDL/DML keywords, no calls to known side-effecting functions. SQL that fails these is rejected. When your artifact declares a tenant policy or `sensitive` markers, the tenant and sensitive-column checks also run. Depending on their mode, they either reject the SQL or return it with warnings. These checks catch common model mistakes but aren’t a security boundary. The exact checks, and what they miss, are in [Safety boundaries](/concepts/safety-boundaries/).
The return value is a string of checked SQL and a parameter list. What happens next is your call.
## The runtime boundary
[Section titled “The runtime boundary”](#the-runtime-boundary)
AskDB stops at checked SQL. Your application — the code that imports `@askdb/core` or calls the HTTP API — owns everything past that:
* The database driver and connection pool.
* Read-only roles and any further row-level security.
* Query timeouts, row limits, and result pagination.
* Whether to show the SQL to the user, log it, queue it for review, or run it immediately.
* Audit logging and observability.
This split is intentional. AskDB is a code-generation step, not a runtime, so it slots into existing services and your existing security model: the database role you already trust to run queries is the one that bounds what generated SQL can do.
## Where the model lives
[Section titled “Where the model lives”](#where-the-model-lives)
You bring the model. AskDB calls whatever provider you wire in — typically through the Vercel AI SDK — using your API key. Requests go straight from your environment to the provider. AskDB does not proxy, log, or cache them.
The same model never sees your database connection, your credentials, or the rows your application returns. See [Privacy model](/concepts/privacy-model/) for the precise list of what crosses the boundary.
## Read next
[Section titled “Read next”](#read-next)
[**The schema artifact**The file the model reads — what’s in it, who owns it, how it evolves.](/concepts/the-schema-artifact/)[**Safety boundaries**Every check AskDB runs before returning SQL.](/concepts/safety-boundaries/)[**Privacy model**What crosses the boundary to the model, and what doesn’t.](/concepts/privacy-model/)[**Embed in a Node app**Put the pipeline behind your own HTTP handler in twenty lines.](/guides/embed-in-node/)
# Modes and dialects
> How AskDB adapts to your SQL engine and the trust model you choose at deploy time.
Adapting to your stack
Two knobs you tune per deployment: the **dialect** (which SQL flavor AskDB generates and validates) and the **mode** (what may enter the model’s context beyond the schema artifact and the question).
## Dialects
[Section titled “Dialects”](#dialects)
A dialect is a `DialectSpec` built into `@askdb/core` — all four ship with the core package. It tells the pipeline how to:
* Construct identifiers and quoting for this engine.
* Format dialect-specific clauses (LIMIT vs TOP, dollar parameters vs question marks, JSON path syntax).
* Validate what counts as a read-only `SELECT` on this engine.
The per-engine packages add introspection for their engine and re-export its dialect constant; `ask()` itself needs only the dialect id. The CLI resolves the id automatically: `dialect` in `askdb.config.ts` → the provider recorded in the schema artifact (for Prisma artifacts, the `datasource.provider` from your `.prisma` file) → `postgres`.
| Engine | Engine package (introspection) | Status |
| ---------- | ------------------------------ | ----------------------------------------------- |
| PostgreSQL | `@askdb/postgres` | Reference dialect. |
| MySQL | `@askdb/mysql` | First-class dialect and introspection. |
| SQLite | `@askdb/sqlite` | First-class dialect; works with embedded files. |
| SQL Server | `@askdb/sqlserver` | T-SQL dialect and introspection. |
Switching engines is mostly a package swap. The full migration checklist lives in [Switch engines](/guides/switch-engines/).
## Modes
[Section titled “Modes”](#modes)
A **mode** declares the trust boundary AskDB enforces for a run: what’s allowed to enter model context beyond the schema artifact and the natural-language question. Today there are two values.
Set the mode three ways, highest precedence first:
* `--mode ` on any CLI command.
* `modes.askdbMode` in `askdb.config.ts`.
* The built-in default (`schema_only`).
### `schema_only` (default)
[Section titled “schema\_only (default)”](#schema_only-default)
AskDB grounds generation in the schema artifact and returns SQL only. The model never sees rows, credentials, or query results. This is the right mode for almost every production deployment.
```bash
askdb ask \
--question "How many orders this week?" \
--mode schema_only
```
### `bounded_results`
[Section titled “bounded\_results”](#bounded_results)
Today, `bounded_results` produces the exact same SQL as `schema_only` — the NL-to-SQL pipeline does not differ, and AskDB surfaces still return SQL only. The mode value is reserved for a forward-looking extension: a post-execute step where a host application may summarize bounded tabular results back through the model. Until that branch ships, picking `bounded_results` over `schema_only` changes nothing observable.
```bash
askdb ask \
--question "Show recent signups" \
--mode bounded_results
```
The versioned spec — including the contracts an eventual bounded-results implementation must honor — lives in [`docs/contracts/modes-v1.md` on GitHub](https://github.com/Ygilany/AskDB/blob/main/docs/contracts/modes-v1.md).
## Sensitive fields
[Section titled “Sensitive fields”](#sensitive-fields)
Columns marked `sensitive: true` in the schema artifact can be:
* Included with a sensitivity tag in the prompt (default), so the model knows to handle them carefully and your application can decide whether to display them.
* Omitted from the prompt entirely with `modes.omitSensitiveFromPrompt: true` in your config (or the `--omit-sensitive-from-prompt` flag), so the model never sees them and therefore never proposes them.
The complete behavior table is in the [sensitive fields contract on GitHub](https://github.com/Ygilany/AskDB/blob/main/docs/contracts/sensitive-fields-and-modes.md).
## Picking a mode
[Section titled “Picking a mode”](#picking-a-mode)
For most teams:
* Start with `schema_only`. It’s the safest default.
* Mark sensitive columns in your schema artifact early. Decide per deployment whether to include them tagged or omit them.
* Don’t reach for `bounded_results` until you have a concrete need — most analytics use cases don’t.
## Read next
[Section titled “Read next”](#read-next)
[**Safety boundaries**What the validator checks regardless of mode.](/concepts/safety-boundaries/)[**Privacy model**What the model sees and what stays in your stack.](/concepts/privacy-model/)[**Switch engines**Move between Postgres, MySQL, SQLite, and SQL Server.](/guides/switch-engines/)
# Privacy model
> What AskDB sends to the model, what stays in your stack, and why your data never leaves your infrastructure.
What crosses the boundary
AskDB sends the question and your schema artifact to the model. Nothing else. Your rows, your credentials, your query results, your user identifiers — none of them cross that boundary, by design.
## What the model sees
[Section titled “What the model sees”](#what-the-model-sees)
When `ask()` calls your model provider, the request contains:
* **The user’s question.** As supplied to AskDB.
* **Schema context.** Tables, columns, types, nullability, and any descriptions you authored — drawn from the schema artifact. For large schemas, only the chunks retrieval selected.
* **Dialect cues.** The SQL flavor AskDB expects back.
That’s the full payload. The model returns SQL.
## What never crosses the boundary
[Section titled “What never crosses the boundary”](#what-never-crosses-the-boundary)
The model never receives:
* **Your database rows.** AskDB does not read your data to construct prompts.
* **Database credentials.** Connection strings, passwords, and roles live in your application’s environment. AskDB doesn’t open a database connection during generation.
* **Query results.** Your application runs the SQL after AskDB returns it. Results stay between your app and your database.
* **User identifiers, session tokens, request headers.** Unless you put them in the question text, they don’t get sent.
## No middlemen
[Section titled “No middlemen”](#no-middlemen)
Requests go straight from your environment to the model provider you wired in. AskDB does not proxy, log, or cache the traffic:
In your stack
1. Your applicationcalls ask()
2. @askdb/corein your dependency tree
3. Your DB connectionyou run the SQL
External
Your model providerOpenAI, Anthropic, …
* →**Prompt out:** question + schema context
* ←**SQL in:** checked by `@askdb/core`
Two crossings only — both routed through your own process. No AskDB-hosted proxy, no relay, no cache.
The model provider sees what’s in the prompt and bills you for the tokens. AskDB is in your dependency tree, not on the wire.
## Sensitive columns
[Section titled “Sensitive columns”](#sensitive-columns)
The schema artifact lets you mark tables and columns as `sensitive: true`, either in `schema.json` or in a table’s markdown front-matter (which is what Studio’s Sensitivity tab writes). Front-matter can only **add** sensitivity. It never un-marks something `schema.json` marks sensitive. The effective flag changes how AskDB constructs the prompt:
* **Tagged in prompt (default).** The model sees the column name with a sensitivity tag. Useful when you want the model to acknowledge the column but generate carefully.
* **Omitted entirely.** With `--omit-sensitive-from-prompt`, sensitive columns are removed from the prompt. The model can’t propose them because it doesn’t know they exist.
Either way, the *values* in those columns are never in the prompt — the flag is about the schema metadata, not the data.
Both of those are **prompt-level**: they change what the model sees, not what can execute. SQL that reaches your database by another route — your own SQL cache, a stored or replayed statement, an artifact regenerated with the flags reset — is unaffected. For that, `@askdb/core` exports `validateSensitiveReferences(sql, schema)`, which reports the sensitive tables and columns a given statement references. `ask()` runs it for you and returns the result as `sensitiveGuardrail`; if you cache or replay SQL, call it on every execution path. See [Core API](/reference/core-api/#validatesensitivereferencessql-schema-options).
## Where logging lives
[Section titled “Where logging lives”](#where-logging-lives)
Audit logging is your application’s job, not AskDB’s. AskDB doesn’t log questions, generated SQL, or model responses. If you want a record of every question that was asked and every SQL string that got generated, log them in the code that wraps `ask()`. That keeps the log inside your stack — same place your user identities and session data already live.
## In one sentence
[Section titled “In one sentence”](#in-one-sentence)
AskDB lets you put a natural-language interface in front of your database without putting your data, your credentials, or your results in front of a model.
# Safety boundaries
> Every check AskDB runs on generated SQL, what those checks do not cover, and how to run generated SQL safely.
Guardrails
AskDB checks every SQL string the model returns before handing it back to your application. Those checks are heuristic guardrails that catch common model mistakes. They are defense in depth, not a security boundary. The database role your application uses to run the SQL is the boundary.
Generated SQL is untrusted input
AskDB does not parse SQL. Its checks are token- and pattern-based and can be bypassed by unusual or adversarial SQL. Before you execute anything AskDB returns, follow [Run generated SQL safely](#run-generated-sql-safely) below.
## What AskDB checks
[Section titled “What AskDB checks”](#what-askdb-checks)
Before `ask()` returns, the generated SQL goes through these checks. The first four are the read-only checks in `validateSelectSql`. They run for built-in dialect ids and `DialectSpec` objects, and they always reject (throw `SqlValidationError`). A custom `AskDialect` skips them unless it calls `validateSelectSql` itself. The SQL is first split into tokens the way your engine reads it under its default string settings (string literals, quoted identifiers, dollar-quoted strings, comments), so a keyword inside a string or a quoted identifier doesn’t count. A string, quoted identifier, or block comment that never closes is rejected rather than guessed at. If your server reads strings differently from its default, set the dialect to match, or these checks can be bypassed: see [Match your server’s string settings](#match-your-servers-string-settings).
1. **Starts with `SELECT` or `WITH`.** The first keyword, after any opening parentheses, must be `SELECT` or `WITH`. Anything else is rejected.
2. **Single statement.** A `;` that separates a second statement is rejected. A single trailing `;` is removed. On SQL Server, which doesn’t need `;` between statements, a second statement made of verbs not on the denylist (for example a second `SELECT`) isn’t detected.
3. **No comments.** `--` and `/* … */` are rejected, and so is `#` on MySQL and MariaDB.
4. **No write, DDL, or side-effecting SQL.** The SQL is rejected if any of these appear as unquoted keywords: `INSERT`, `UPDATE`, `DELETE`, `DROP`, `TRUNCATE`, `ALTER`, `CREATE`, `GRANT`, `REVOKE`, `VACUUM`, `ANALYZE`, `COPY`, `CALL`, `MERGE`, `INTO`. `INTO` covers `SELECT … INTO new_table` and MySQL `INTO OUTFILE`. MySQL and MariaDB also block `OUTFILE` and `DUMPFILE`. SQLite also blocks `ATTACH`, `DETACH`, `PRAGMA`, and `REINDEX`. SQL Server also blocks `EXEC`, `EXECUTE`, `OPENROWSET`, `OPENQUERY`, `WAITFOR`, `SHUTDOWN`, `SET`, `USE`, and other T-SQL statement verbs, because T-SQL runs a batch without semicolons. Calls to known side-effecting functions are rejected too, for example `pg_sleep`, `set_config`, `pg_read_file`, `dblink`, and `nextval` on Postgres and CockroachDB, `SLEEP` and `LOAD_FILE` on MySQL and MariaDB, and `load_extension` on SQLite.
5. **Tenant check (when your artifact has a tenant policy).** `ask()` refuses to run without a `tenantScope`. Before it binds your tenant IDs, AskDB checks the model’s SQL while the `:tenant_…_ids` placeholders are still in place: each tenant-scoped table named in the SQL, and each root table the scope covers, needs a tenant predicate: its tenant column compared with the tenant placeholder (`= :tenant_…_ids`, `IN (…)` or `= ANY(…)`), ANDed into a `WHERE`, inner-join `ON` or `HAVING` clause. A column that’s only selected, a literal tenant ID, or a predicate beside an `OR` (such as `WHERE org_id = :tenant_org_ids OR 1=1`) or under `NOT` doesn’t count. Text inside string literals and comments doesn’t count either. Tables your policy leaves unclassified are flagged too. It’s a heuristic, not a parser. Within one statement, including its CTEs, derived tables and subqueries (only `UNION`, `INTERSECT` and `EXCEPT` branches are checked on their own), it doesn’t tie a predicate to a particular table reference, so an unfiltered reference can pass beside a filtered one: `WITH t AS (SELECT id FROM orders WHERE agency_id = :tenant_agency_ids) SELECT * FROM orders` passes ([#399](https://github.com/Ygilany/AskDB/issues/399)). Your policy’s `enforcement` setting decides what happens on a miss: `strict` throws `TenantGuardrailError`, and `warn` returns the SQL with the findings in `tenantGuardrail.warnings`. AskDB does not add a missing tenant filter. See [Multi-tenancy](/guides/multi-tenancy/).
6. **Sensitive columns (when your schema marks any).** The returned SQL is checked for tables and columns marked `sensitive: true`, and the result is attached as `sensitiveGuardrail`. The default mode is `"warn"`, which returns the SQL with the findings attached. Set `sensitiveGuardrailMode: "strict"` to throw `SensitiveReferenceError` instead. The check reports sensitive columns named in the SQL, sensitive tables read in `FROM` or `JOIN`, and sensitive columns reached through `SELECT *`, `t.*`, or a whole-row reference such as `row_to_json(t)`. It can miss a table written in a `FROM` form it doesn’t recognize, such as `SELECT * FROM (users)`. Separately, `--omit-sensitive-from-prompt` keeps sensitive columns out of the prompt entirely, which only affects what the model sees. Call `validateSensitiveReferences` yourself on any SQL you cache and re-execute.
### Match your server’s string settings
[Section titled “Match your server’s string settings”](#match-your-servers-string-settings)
The checks read backslashes inside ordinary `'…'` string literals the way each engine does by default: MySQL and MariaDB treat `\'` as an escaped quote, and Postgres and CockroachDB (with `standard_conforming_strings = on`, the default) treat a backslash as an ordinary character. When the server is configured differently, AskDB and the server disagree about where a string ends, and SQL the checks accept can run code they never saw. For example, on a MySQL server whose `sql_mode` includes `NO_BACKSLASH_ESCAPES`, the built-in `mysql` dialect accepts `SELECT 'x\' UNION SELECT load_file('/etc/passwd') -- '`: AskDB reads one string, and the server reads a `load_file` call followed by a comment.
Set `backslashEscapes` on a `DialectSpec` to match the server, and pass that spec wherever you pass a dialect:
```ts
import { ask, MYSQL_DIALECT, POSTGRES_DIALECT, type DialectSpec } from "@askdb/core";
// MySQL or MariaDB with NO_BACKSLASH_ESCAPES in sql_mode (spread MARIADB_DIALECT for MariaDB).
const mysqlNoBackslashEscapes: DialectSpec = { ...MYSQL_DIALECT, backslashEscapes: false };
// Postgres with standard_conforming_strings = off.
const postgresLegacyStrings: DialectSpec = { ...POSTGRES_DIALECT, backslashEscapes: true };
const { sql } = await ask({ question, schema, model, dialect: mysqlNoBackslashEscapes });
```
`@askdb/mysql` re-exports `MYSQL_DIALECT` and `MARIADB_DIALECT` from `@askdb/core`, so you can import them from either package. The same spec also goes to `validateSelectSql(spec, sql)` and to `@askdb/client` per call (`askdb.ask(question, { dialect: mysqlNoBackslashEscapes })`). The dialect setting in `askdb.config.ts`, and so the CLI, the HTTP API, and Studio, takes only a built-in dialect id, so those surfaces always assume the default settings ([#340](https://github.com/Ygilany/AskDB/issues/340)).
The same setting decides how AskDB escapes the values it inlines: tenant IDs in the default `sql-only` mode, and the values `bindPreparedQuery` inlines into its `sql`. With a mismatched dialect, a value containing a backslash can escape its literal ([#371](https://github.com/Ygilany/AskDB/issues/371)). Values passed as driver parameters (`tenantSqlMode: "sql-params"`, or `unboundSql` with `params`) aren’t affected.
MySQL’s `ANSI_QUOTES` mode (also part of the `ANSI` mode) isn’t supported. It makes `"…"` an identifier, which the MySQL dialect reads as a string with backslash escapes, and no `DialectSpec` setting matches it. Run AskDB’s SQL on a connection without `ANSI_QUOTES`.
### What these checks don’t do
[Section titled “What these checks don’t do”](#what-these-checks-dont-do)
* **No SQL parsing.** AskDB splits SQL into tokens but doesn’t build a syntax tree, so it can’t tell whether the SQL is valid for your engine. Your database reports syntax errors when you run the query.
* **No system-schema filtering.** Queries against `pg_catalog`, `information_schema`, MySQL’s `mysql` schema, SQL Server’s `sys`, and so on are not rejected. What they return depends on your database’s privileges, and on Postgres every role can read the catalog metadata (see [System catalogs](/guides/run-safely-in-prod/#system-catalogs)).
* **No query rewriting.** AskDB never adds a tenant filter, a row limit, or a timeout to the SQL. The only change it makes to the tenant predicate is binding: it replaces the `:tenant_*_ids` placeholders the model wrote with your scope’s IDs (escaped literals or driver parameter markers), and with several IDs it turns `=` into `IN (…)` and `!=` or `<>` into `NOT IN (…)`.
* **No complete side-effect analysis.** The function denylist covers known built-in functions only. A call to one of your own functions that writes, a locking read such as `FOR SHARE`, and a very expensive join all pass.
* **No complete sensitive-column coverage.** The sensitive check can miss a table in some `FROM` forms, so a wildcard over it goes unreported: a parenthesized `FROM` item ([#306](https://github.com/Ygilany/AskDB/issues/306)), a comma-joined table after a `JOIN`’s `ON` or `USING` ([#307](https://github.com/Ygilany/AskDB/issues/307)), MySQL `STRAIGHT_JOIN` used as a join ([#308](https://github.com/Ygilany/AskDB/issues/308)), and Postgres `TABLE users` inside a derived table ([#309](https://github.com/Ygilany/AskDB/issues/309)). Use column privileges in the database for data that must not be read.
Guardrail bypasses are bugs and we fix them. Still, plan for the checks to miss things.
## Run generated SQL safely
[Section titled “Run generated SQL safely”](#run-generated-sql-safely)
AskDB returns SQL. It does not run it. If your application executes that SQL, these controls are the actual boundary:
* **Use a least-privilege, read-only database role.** Grant `SELECT` only on the tables AskDB is meant to query, leave out sensitive tables you can exclude, and make the role’s transactions read-only (on Postgres, grants alone don’t stop every write). Then a query that gets past AskDB’s checks still can’t write, and can’t read rows the role can’t see. Grants don’t hide the system catalogs everywhere: on Postgres every role can read table names, column names, and view and function definitions through `PUBLIC`. See [Run safely in production](/guides/run-safely-in-prod/#database-role) for an example and your options for the catalogs.
* **Enforce tenancy in the database.** For multi-tenant data, make the database the tenant boundary: Postgres row-level security (RLS) keyed on a per-request setting, per-tenant views, or per-tenant roles. AskDB’s tenant check catches a model that forgot the filter or widened it in the common ways (an `OR`, a literal ID). It doesn’t prove the SQL is scoped.
* **Set timeouts and row limits.** Configure `statement_timeout` (or your engine’s equivalent) on the connection, and cap the rows you fetch.
* **Treat inputs to the prompt as untrusted.** The question text and your schema enrichment (descriptions, concepts, tenant-policy prose) all go into the prompt. Someone who controls either one can try to steer the model toward a different query. The database controls above still apply when that happens.
* **Review before running when it matters.** For high-stakes questions, show the SQL to a person before running it, and log every question, generated SQL string, and outcome.
## What stays in your application
[Section titled “What stays in your application”](#what-stays-in-your-application)
AskDB returns SQL. It does not run it. The execution layer is yours, which means **your application** owns the boundaries that depend on runtime context:
* **Connection roles.** Connect with a read-only, least-privilege user. That’s what actually prevents writes. AskDB’s keyword checks are a first filter.
* **Query timeouts and row limits.** Set `statement_timeout` (or equivalent) on the connection. Wrap results in pagination.
* **Approval flows.** When the question is high-stakes, show the SQL to a human before executing.
* **Audit logging.** Log every question, every generated SQL, every execution outcome.
* **User identity and tenant isolation.** AskDB doesn’t know who’s asking. Your application decides which tenant IDs go into `tenantScope`, and your database should enforce that user A can only read tenant A’s rows. AskDB’s tenant check catches the common ways a filter fails to filter, but it doesn’t prove the SQL is scoped.
## Defense in depth
[Section titled “Defense in depth”](#defense-in-depth)
AskDB’s checks and your execution boundary are separate layers. AskDB’s checks catch the common ways a model gets it wrong: a write statement, a stacked second statement, a forgotten tenant filter, a sensitive column. The database role, RLS policies, and timeouts in your runtime hold even when a query gets past those checks.
A typical production stack looks like:
Each layer does one job, and no single layer is the only protection.
## Read next
[Section titled “Read next”](#read-next)
[**Modes and dialects**How the validator adapts to your engine and your trust model.](/concepts/modes-and-dialects/)[**Run safely in production**The full operator checklist for the execution side.](/guides/run-safely-in-prod/)[**Multi-tenancy**Declaring tenant policy in your schema artifact.](/guides/multi-tenancy/)
# The schema artifact
> AskDB's schema artifact — a versionable file your team owns, not a black-box prompt buried in code.
The contract
The schema artifact is the single file (or directory) your team authors, reviews, and checks into version control. It’s the context the model uses to generate SQL — and it’s yours to evolve like any other piece of source code.
## On disk
[Section titled “On disk”](#on-disk)
A schema artifact is a folder with one required file and a few optional companions:
```plaintext
my-app.schema/
schema.json # required — physical structure
tables/
users.md # optional — per-table descriptions, aliases, concepts
orders.md
concepts.md # optional — cross-table business concepts
schema.lock.json # optional — written by @askdb/rag indexing (embedder, store, chunk hashes)
```
Only `schema.json` is required. An artifact with no markdown is valid; you can add enrichment incrementally.
When you need one portable file (for distributing to a service, an agent, or a build artifact), bundle the directory:
```bash
npx askdb bundle my-app.schema --out my-app.schema.bundle.json
```
## The physical layer
[Section titled “The physical layer”](#the-physical-layer)
`schema.json` holds the structural facts: stable IDs, physical table and column names, types, nullability, primary keys, relationships, and sensitivity flags.
```json
{
"version": 2,
"schemaId": "my-app",
"tables": [
{
"id": "table:users",
"name": "users",
"columns": [
{
"id": "table:users#email",
"name": "email",
"type": "text",
"nullable": false,
"sensitive": true
}
]
}
]
}
```
The physical layer is regenerated by `askdb introspect` — you don’t hand-edit it.
## The enrichment layer
[Section titled “The enrichment layer”](#the-enrichment-layer)
Per-table markdown adds the meaning the model needs to generate good SQL: descriptions, aliases, common query language, example questions, and column-level notes.
```markdown
---
id: table:orders
name: orders
schemaId: my-app
aliases: [purchases, sales]
columns:
- id: table:orders#status
enum: [pending, paid, shipped, cancelled]
description: Order lifecycle state.
---
# Table: orders
Customer purchase orders. One row per submitted order.
## Common query language
- "sales" usually means paid orders
- "active customers" excludes status = cancelled
```
This layer survives re-introspection. When your database changes, `askdb introspect` updates `schema.json` and leaves your markdown intact.
Front-matter can also mark a table or column sensitive. This is what Studio’s Sensitivity tab writes: a table-level `sensitive: true`, or `sensitive: true` on a `columns` entry. Sensitivity is **escalate-only**. Front-matter can make a table or column sensitive on top of `schema.json`, but a front-matter `sensitive: false` never un-marks something `schema.json` marks sensitive. AskDB ignores it and reports a `sensitivity_downgrade_ignored` warning. A sensitive table makes all of its columns sensitive. To un-mark a column, edit `schema.json`. If a `columns` entry names a column from a different table, its `sensitive: true` still applies to that column, and AskDB reports a `misplaced_column_id` warning so you can move the entry to the right file. If a column is listed more than once, it is sensitive when any of its entries says `sensitive: true`. A repeat within one file is reported as a `duplicate_column_id` warning, and only the first entry’s description, aliases, and enum are used. Each table gets exactly one markdown file: two files with the same front-matter `id` are an error.
## What the model actually receives
[Section titled “What the model actually receives”](#what-the-model-actually-receives)
The model never sees the directory you author. At generation time AskDB merges the physical layer and the enrichment into a single compact, model-facing text — a DDL-style description where each table is rendered as a block and your enrichment is folded in as inline comments (descriptions, aliases, and “common query language” attached to the table and columns they describe). Sensitive fields are tagged or withheld here according to your mode.
So the two layers you maintain separately on disk — `schema.json` for structure, markdown for meaning — are assembled into one annotated schema description the model reads. That repackaged text, plus the question, is the entire prompt: never your rows, your credentials, or your query results. When a schema is too large to send whole, the same rendering is applied to only the relevant slice retrieved for the question (see [RAG for large schemas](/guides/rag-for-large-schemas/)).
## Stable IDs
[Section titled “Stable IDs”](#stable-ids)
Every table, column, and concept has a stable ID. Renaming a column in the database doesn’t break the enrichment that references it — the ID stays the same.
| ID | Refers to |
| ------------------- | ------------------------------ |
| `table:users` | A table |
| `table:users#email` | A column |
| `concept:customer` | A cross-table business concept |
## Why this matters
[Section titled “Why this matters”](#why-this-matters)
The schema artifact is a deliberate choice. The alternative — a prompt template buried in application code — is opaque, hard to review, and tangled with the rest of your codebase.
A versionable file means:
* Your data team can review changes in a PR like any other code.
* You can see, line by line, what context the model receives.
* Enrichment evolves at its own pace, decoupled from app deploys.
* The same artifact powers the CLI, the library, and the HTTP API — one source of truth.
# Troubleshooting
> Common errors and fixes: schema not found, SQL validation failures, missing drivers, TLS issues, tenant scope rejections, and poor SQL quality.
Guides · Troubleshooting
Errors grouped by where they surface. If you hit something not listed here, open a [Discussion](https://github.com/Ygilany/AskDB/discussions/categories/q-a).
***
## Schema and config
[Section titled “Schema and config”](#schema-and-config)
### `No askdb.config.* or .config/askdb.* found in …`
[Section titled “No askdb.config.\* or .config/askdb.\* found in …”](#no-askdbconfig-or-configaskdb-found-in-)
`askdb ask` and `askdb introspect` print this when the current directory has no config. `bootstrapAskDbEnv()` throws a similar error (`… found under `) when you embed the libraries.
AskDB looks for `askdb.config.` (then `.config/askdb.`) in the **current working directory only** — in a monorepo it won’t find a config in a parent directory. Supported extensions, in precedence order: `ts`, `mts`, `cts`, `js`, `mjs`, `cjs`.
If the project has no config yet, create one with `npx askdb init`. If it has one, run the CLI from the directory that holds the config.
```bash
cd apps/api && npx askdb ask --question "..."
```
When embedding the libraries, the equivalent knob is the `cwd` option: `bootstrapAskDbEnv({ cwd: "/path/to/project" })`.
### `Set ASKDB_DEBUG=1 to print the stack trace.`
[Section titled “Set ASKDB\_DEBUG=1 to print the stack trace.”](#set-askdb_debug1-to-print-the-stack-trace)
The CLI hit an unexpected error, most often a config file that exists but fails to load: a syntax error, a missing import, or dependencies that aren’t installed yet. The line above the hint is the error message, and it usually names the file and line.
Rerun with `ASKDB_DEBUG=1` to see the stack trace:
```bash
ASKDB_DEBUG=1 npx askdb ask --question "..."
```
`askdb studio` doesn’t stop on a config that fails to load: it prints `askdb-studio: warning: could not be loaded, so Studio is ignoring it: …` and starts without it. Fix the file and restart Studio; the setup wizard never overwrites it.
### `SchemaParseError: Cannot read schema at …`
[Section titled “SchemaParseError: Cannot read schema at …”](#schemaparseerror-cannot-read-schema-at-)
The path passed to `--schema` (CLI) or `loadSchema()` (library) doesn’t exist or isn’t a valid schema artifact. Valid inputs are:
* A schema directory (e.g. `my-app.schema/`)
* A bundled JSON file (e.g. `my-app.schema.json`)
* A `schema.json` file inside a directory
Run `ls my-app.schema/` to confirm the directory was created by `askdb introspect`. If it’s empty, the introspection step didn’t complete successfully.
### `SchemaParseError: Missing required field …`
[Section titled “SchemaParseError: Missing required field …”](#schemaparseerror-missing-required-field-)
The schema artifact is from an older format. Re-run introspection to regenerate it:
```bash
npx askdb introspect --url "$DATABASE_URL" --out my-app.schema --schema-id my-app
```
***
## SQL generation
[Section titled “SQL generation”](#sql-generation)
### `SqlValidationError: SQL_NOT_SELECT_OR_WITH`
[Section titled “SqlValidationError: SQL\_NOT\_SELECT\_OR\_WITH”](#sqlvalidationerror-sql_not_select_or_with)
AskDB only returns `SELECT` or `WITH … SELECT` statements. The model generated a non-SELECT statement (e.g. `INSERT`, `UPDATE`, `DROP`). This is a guardrail, not a bug.
If you’re seeing this on legitimate read questions, the model may be misreading the schema. Check that your table and column descriptions in the schema artifact don’t imply write operations.
### `SqlValidationError: SQL_MULTI_STATEMENT`
[Section titled “SqlValidationError: SQL\_MULTI\_STATEMENT”](#sqlvalidationerror-sql_multi_statement)
The model returned more than one SQL statement. AskDB refuses multi-statement output. Rephrase the question to ask for a single result, or break it into two separate `ask()` calls.
### `SqlValidationError: SQL_COMMENT` / `SQL_FORBIDDEN_KEYWORD` / `SQL_FORBIDDEN_FUNCTION`
[Section titled “SqlValidationError: SQL\_COMMENT / SQL\_FORBIDDEN\_KEYWORD / SQL\_FORBIDDEN\_FUNCTION”](#sqlvalidationerror-sql_comment--sql_forbidden_keyword--sql_forbidden_function)
The generated SQL contains a SQL comment (including `#` on MySQL), a forbidden keyword (`INTO`, `DELETE`, `EXEC`, `WAITFOR`, etc.), or a call to a blocked side-effecting function (`pg_sleep`, `set_config`, `LOAD_FILE`, `SLEEP`, etc.). Keywords are matched as whole, unquoted tokens, so a column like `deleted_at` or `"delete"` is fine, but an unquoted column or alias named like a keyword (say, `update`) also trips them. These are heuristic, defense-in-depth guardrails. If one fires on a legitimate query, file an issue with the question and schema excerpt.
### `SqlValidationError: SQL_UNTERMINATED`
[Section titled “SqlValidationError: SQL\_UNTERMINATED”](#sqlvalidationerror-sql_unterminated)
A string literal, quoted identifier, dollar-quoted string, or block comment in the generated SQL never closes, so the validator cannot tell where the statement ends and rejects it. On MySQL or MariaDB, check that the dialect’s `backslashEscapes` setting matches the server (`NO_BACKSLASH_ESCAPES`). A mismatch matters beyond false rejections: it also lets SQL through that the server reads differently. See [Match your server’s string settings](/concepts/safety-boundaries/#match-your-servers-string-settings).
### Generated SQL references a column or table that doesn’t exist
[Section titled “Generated SQL references a column or table that doesn’t exist”](#generated-sql-references-a-column-or-table-that-doesnt-exist)
This is the most common failure mode. The model hallucinated an identifier that isn’t in your schema. AskDB doesn’t check generated identifiers against the schema, so your database reports these when you run the query.
**Fix:** Enrich the relevant tables in your schema artifact with plain-English descriptions. The more context the model has, the less it invents:
```bash
npx askdb studio # open the enrichment UI
# or
npx askdb enrich # headless AI-assisted enrichment
```
If the column exists in the database but the model keeps getting it wrong, check that `askdb introspect` has been re-run since the column was added, and that its description in the schema artifact isn’t ambiguous.
### The SQL is syntactically valid but logically wrong
[Section titled “The SQL is syntactically valid but logically wrong”](#the-sql-is-syntactically-valid-but-logically-wrong)
SQL validation is heuristic — AskDB confirms the statement kind and blocks write keywords and side-effecting functions, but it doesn’t check identifiers and can’t verify that the query answers your question semantically. The quality of answers depends almost entirely on how well the schema artifact describes your data.
Checklist:
1. Does the relevant table have a description? (`description:` field in the table’s `.md` file)
2. Do column names match how users phrase questions? Add aliases in the schema artifact.
3. Is this a complex aggregation or join? Add an example question + expected SQL to the table file.
4. Try a more capable model — `gpt-4o` vs `gpt-4o-mini` makes a meaningful difference on complex schemas.
***
## Model and API keys
[Section titled “Model and API keys”](#model-and-api-keys)
### `Error: API key not found` / `AuthenticationError`
[Section titled “Error: API key not found / AuthenticationError”](#error-api-key-not-found--authenticationerror)
The model provider didn’t receive a key. For the CLI, set the environment variable before running:
```bash
OPENAI_API_KEY=sk-... npx askdb ask --question "..."
```
For the library, verify the key is passed when constructing the provider:
```ts
const openai = createOpenAI({ apiKey: process.env.OPENAI_API_KEY });
```
See [Bring your own model](/guides/bring-your-own-model/) for per-provider configuration.
### `Error: Model not found` / 404 from provider
[Section titled “Error: Model not found / 404 from provider”](#error-model-not-found--404-from-provider)
The model name passed to the provider doesn’t exist or isn’t available on your account tier. The default CLI model is `gpt-4o-mini` (OpenAI). Override it with `OPENAI_MODEL` in your `askdb.config.ts` or pass a different model instance to `ask()`.
***
## Studio and drivers
[Section titled “Studio and drivers”](#studio-and-drivers)
### Studio shows “driver not installed” or an Install button
[Section titled “Studio shows “driver not installed” or an Install button”](#studio-shows-driver-not-installed-or-an-install-button)
Studio’s **Execute Query** feature (running SQL against a live database) requires an optional peer driver package. Install the one matching your engine:
```bash
npm install pg # Postgres
npm install mysql2 # MySQL
npm install better-sqlite3 # SQLite
npm install mssql # SQL Server
```
After installing, refresh Studio. The driver readiness indicator near the Execute button should clear.
Note
Generating SQL in Studio does **not** require a driver. Only the Execute Query action does.
### Studio doesn’t connect to my database
[Section titled “Studio doesn’t connect to my database”](#studio-doesnt-connect-to-my-database)
Studio execute is off by default. Check that `studio.execute.enabled: true` is set in `askdb.config.ts`, that `studio.execute.databaseUrl` (or `studio.execute.file` for SQLite) is set, and that the database is reachable from your machine. Restart Studio after editing the config. Studio resolves the execute connection in this order:
1. `studio.execute.databaseUrl` / `studio.execute.file`
2. The introspection connection for the same engine, only when `studio.execute.useIntrospectionConnection: true`
The provider comes from `studio.execute.provider`, or the active `introspection.provider` when it’s a live engine.
See [Configuration — Studio execute](/reference/config/#studio-execute-configuration) for the full resolution order.
***
## SQL Server
[Section titled “SQL Server”](#sql-server)
### `self-signed certificate` / TLS error on connection
[Section titled “self-signed certificate / TLS error on connection”](#self-signed-certificate--tls-error-on-connection)
SQL Server enables TLS by default. Local and dev instances typically use a self-signed certificate, which Node.js rejects:
```plaintext
Error: self-signed certificate — try running Node.js with --use-system-ca
```
Add `trustServerCertificate=true` to the connection URL:
```plaintext
# mssql driver URL format
mssql://sa:pass@localhost:1433/MyDb?trustServerCertificate=true
# sqlserver introspection URL format
sqlserver://localhost:1433;database=MyDb;user=sa;password=pass;trustServerCertificate=true
```
Caution
Only use `trustServerCertificate=true` in development. In production, configure a valid certificate.
***
## Tenant scope
[Section titled “Tenant scope”](#tenant-scope)
### `TenantScopeError: MISSING_SCOPE`
[Section titled “TenantScopeError: MISSING\_SCOPE”](#tenantscopeerror-missing_scope)
Your schema has a `tenant-policy.md` file, which means AskDB requires a `tenantScope` on every `ask()` call. Pass one:
```ts
const { sql } = await ask({
question,
schema,
model,
dialect,
tenantScope: {
access: {
kind: "ids",
tenantRoot: "table:public.organizations",
ids: [currentUser.orgId],
},
},
});
```
See [Multi-tenancy](/guides/multi-tenancy/) for the full scope shape.
### `TenantScopeError: UNKNOWN_TENANT_ROOT`
[Section titled “TenantScopeError: UNKNOWN\_TENANT\_ROOT”](#tenantscopeerror-unknown_tenant_root)
The `tenantRoot` in the scope doesn’t match any root defined in `tenant-policy.md`. Check the `id:` field of each root in the policy file — the scope must use the same stable table ID (e.g. `table:public.organizations`).
### `TenantScopeError: SUBTREE_NOT_RESOLVABLE`
[Section titled “TenantScopeError: SUBTREE\_NOT\_RESOLVABLE”](#tenantscopeerror-subtree_not_resolvable)
The scope uses `access.kind: "subtree"`, but `ask()` couldn’t expand it. Either no `resolveTenantDescendants` callback was passed, or the callback didn’t return IDs per tenant root. The message says which: it returned an array (the flat shape from before per-root IDs), something other than a plain object, a key that isn’t a tenant root in the subtree, a value that isn’t an array of non-empty string IDs, or no IDs at all. AskDB doesn’t query your database to find descendants, and it won’t fall back to the seed IDs alone. Return an object keyed by root table ID, with the seeds and same-table descendants under the scope’s `tenantRoot` and each descendant root’s IDs under that root: `{ "table:public.agencies": ["1"], "table:public.clients": ["5"] }`. Or send a `multi_root` access with each root’s IDs already expanded. Calling `resolveTenantSql()` or `buildTenantPromptBlock()` directly with an unexpanded `subtree` scope throws the same error, because neither walks the hierarchy. See [Hierarchical scope](/guides/multi-tenancy/#hierarchical-scope-subtree).
### `SchemaParseError: Invalid tenant policy: roots … both map to the placeholder …`
[Section titled “SchemaParseError: Invalid tenant policy: roots … both map to the placeholder …”](#schemaparseerror-invalid-tenant-policy-roots--both-map-to-the-placeholder-)
Two roots in `tenant-policy.md` derive the same placeholder. A placeholder is the label lowercased, with every run of characters other than ASCII letters and digits turned into `_`, so `Agency` and `agency` both give `:tenant_agency_ids`. A label with no ASCII letter or digit (Cyrillic, CJK and so on) uses the root’s table name instead: `Клиент` on `table:public.clients` gives `:tenant_clients_ids`. That fallback can still collide, for example when both table names are non-ASCII too, or when it meets another root’s label. Each root’s IDs are bound through its own placeholder, so a shared one would bind one root’s IDs where the other root’s column is compared. AskDB rejects the policy when it loads, `ask()` and `resolveTenantSql()` reject a policy built in code the same way, and Studio refuses to save it. Rename one of the two roots named in the message, using a label with ASCII letters or digits if the fallback collides. See the `label` row in the [field reference](/guides/multi-tenancy/#field-reference).
### `TenantGuardrailError`
[Section titled “TenantGuardrailError”](#tenantguardrailerror)
Your tenant policy uses `enforcement: strict`, and the generated SQL is missing a required tenant predicate on a tenant-scoped or root table, names a table the policy leaves unclassified, or names a polymorphic table without its type discriminator. AskDB throws instead of returning that SQL. A predicate counts only as the table’s tenant column compared with its placeholder (`agency_id = :tenant_agency_ids`, or `IN (…)` / `= ANY(…)`), ANDed into a `WHERE`, inner-join `ON`, or `HAVING` clause. A literal tenant ID, a column that’s only selected, or a predicate next to an `OR` doesn’t count, and a query on the root table itself needs the predicate too; see [What the tenant check requires](/guides/multi-tenancy/#what-the-tenant-check-requires). Under a `subtree` scope, each covered root the query reads needs its own placeholder: filtering `clients` only through `clients.sub_agency_id` or a joined agency is rejected, and a covered root you returned no IDs for can’t be read at all (see [Hierarchical scope](/guides/multi-tenancy/#hierarchical-scope-subtree)). Inspect the `warnings` array on the error to see which table triggered it, then re-ask the question or narrow it. The check is heuristic: passing it doesn’t prove the query is tenant-safe, so keep tenant isolation enforced in the database. See [Run generated SQL safely](/concepts/safety-boundaries/#run-generated-sql-safely).
***
## RAG / large schemas
[Section titled “RAG / large schemas”](#rag--large-schemas)
### Retriever is supplied but AskDB uses the full DDL anyway
[Section titled “Retriever is supplied but AskDB uses the full DDL anyway”](#retriever-is-supplied-but-askdb-uses-the-full-ddl-anyway)
Two reasons this happens:
1. **Below threshold:** `totalSchemaChunkCount` is at or below `retrievalThresholdChunks` (default 30). Pass the actual chunk count from `buildSchemaIndex` result:
```ts
const index = await buildSchemaIndex({ schema, embedder });
const { sql } = await ask({
...
retriever: index.retriever,
totalSchemaChunkCount: index.stats.chunksTotal,
});
```
2. **Outdated artifact format:** The retriever is silently skipped for schema artifacts created by very old AskDB versions. Confirm `loadSchema()` returns an object with a `schemaId` field; if it doesn’t, re-run `askdb introspect` to regenerate the artifact.
### Retriever returns no chunks
[Section titled “Retriever returns no chunks”](#retriever-returns-no-chunks)
The question didn’t match any indexed chunks. This usually means the schema artifact descriptions are too sparse for meaningful embedding similarity. Enrich your schema with richer table and column descriptions, then rebuild the index.
# Author your schema
> Use Studio to enrich your introspected schema with descriptions, aliases, concepts, sensitive markers, and tenant policy.
Schema author guide
Raw introspection gives the model structure, which may be enough for simple schemas and simple queries. Enrichment is what gives it real meaning and context — descriptions, business concepts, and domain phrasing that make generation reliable. Studio is the recommended authoring surface — a local browser UI that edits your schema artifact directly.
## Before you start
[Section titled “Before you start”](#before-you-start)
Have a schema artifact on disk. If you haven’t run introspection yet, the [Quickstart](/quickstart/) gets you to one in two commands.
## Authoring in Studio
[Section titled “Authoring in Studio”](#authoring-in-studio)
Studio is the browser-based editor. Launch it from your project root:
```bash
npx askdb studio
```
The command reads `outputDir` from `askdb.config.ts`. Pass `--schema ` to override for this run. By default Studio serves on `http://127.0.0.1:5556`. It reads and writes the files in your schema folder directly — no separate database, no separate copy of your schema.
What you can edit (all fields are optional):
* **Tables.** Per-table description, aliases (the names users actually use), and a “common query language” section that captures domain phrasing.
* **Columns.** Descriptions, enums, and sensitivity markers. Mark columns like `email`, `ssn`, or `internal_notes` as `sensitive` so the prompt-construction layer can tag or omit them — and so `validateSensitiveReferences` can flag any SQL that touches them before it runs. Sensitivity overrides are escalate-only: marking a table or column sensitive always takes effect, but “Not sensitive” can’t un-mark something `schema.json` already marks sensitive.
* **Concepts.** Cross-table business concepts (`customer`, `active subscription`, `paid order`) that don’t map to one table.
* **Tenant policy.** When your app is multi-tenant, declare tenant roots and scoped tables. See [Multi-tenancy](/guides/multi-tenancy/) for the full walkthrough.
Studio also offers AI-assisted drafts: describe a table or concept in plain language and Studio proposes a draft for your review. Suggestions are always confirmed by a human before they land in the artifact. See the [Studio tour](/studio/) for a view-by-view walkthrough.
## Re-introspecting
[Section titled “Re-introspecting”](#re-introspecting)
When your database schema changes (new columns, renamed tables, added relationships), re-run introspection. The physical layer (`schema.json`) is regenerated; your enrichment markdown (`tables/*.md`, `concepts.md`, `tenant-policy.md`) is preserved.
```bash
npx askdb introspect
```
With your introspection provider and URL configured in `askdb.config.ts` (and matching env vars in `.env`), no flags are needed. See the [Configuration reference](/reference/config/) for per-engine details.
Stable IDs mean a renamed column doesn’t break the enrichment that references it — the ID stays the same and the markdown follows.
## Bundling for distribution
[Section titled “Bundling for distribution”](#bundling-for-distribution)
When another service or build artifact needs the schema as a single file:
```bash
npx askdb bundle ./my-app.schema --out my-app.schema.bundle.json
```
The bundle file is the entire artifact in one JSON. Load it with `loadSchema` the same way as a directory.
## Commit it
[Section titled “Commit it”](#commit-it)
The schema artifact is source code. Check it into the repo, review changes in PRs, deploy it alongside your app. The artifact is the single source of truth for what the model sees about your database.
## How enrichment reaches the model
[Section titled “How enrichment reaches the model”](#how-enrichment-reaches-the-model)
Your enrichment doesn’t get sent to the model as the markdown you write. When you ask a question, AskDB merges the physical schema and your enrichment into one compact, model-facing schema description — a DDL-style block where descriptions, aliases, and “common query language” become inline annotations on the tables and columns they belong to. That’s why enrichment written as plain-language descriptions and the phrases your users actually say is effective: it lands right next to the structure the model is reasoning over. See [The schema artifact](/concepts/the-schema-artifact/) for the full picture of what the model receives.
## Read next
[Section titled “Read next”](#read-next)
[**Multi-tenancy**Declaring tenant roots and scoped tables in your artifact.](/guides/multi-tenancy/)[**The schema artifact**The on-disk format in detail.](/concepts/the-schema-artifact/)[**RAG for large schemas**When your enriched artifact is too big for a single prompt.](/guides/rag-for-large-schemas/)
# Bring your own model
> Use OpenAI, Anthropic, Azure OpenAI, Google — any provider that speaks the Vercel AI SDK interface. Your key, your billing.
Model providers
AskDB doesn’t host inference. You wire a model in, AskDB calls it, and the model’s response goes back through your provider — billed to your account.
## Two ways to wire a model
[Section titled “Two ways to wire a model”](#two-ways-to-wire-a-model)
| | What you do | Best for |
| ------------------------ | ------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------- |
| **In your config** | Set `ai.provider` in `askdb.config.ts`. The CLI, Studio, and the HTTP API resolve the model for you. No model code. | CLI workflows, Studio, the bundled HTTP service |
| **In your code** | Pass any Vercel AI SDK `LanguageModel` to `ask()`. Full control. | Embedding `@askdb/core` in your own service |
| **With `@askdb/client`** | Call `createAskDb({ config })` then `askdb.ask("question")`. Schema, model, and dialect come from config. | The shortest config-driven embed — one schema, one model |
Same providers, same keys — pick per surface. You can use both in one project (for example: Studio uses your config, your embedding service constructs the model directly).
## Which should I use?
[Section titled “Which should I use?”](#which-should-i-use)
`ask()`’s actual contract is `model: LanguageModel` — a plain Vercel AI SDK model object. Every path below ends up building one of those; `@askdb/ai` and `@askdb/client` are a convenience layer on top, not a separate mechanism. Neither path is more “correct.” Pick based on who owns provider configuration:
* **Use `@askdb/client` (built on `@askdb/ai`)** when you want `askdb.config.ts` to drive provider/model selection — one config file, no provider code, and the CLI/Studio/your app all resolve the same way. This is the right default when you’re embedding AskDB as a standalone service and don’t already have a provider-config system.
* **Construct a `LanguageModel` directly with the AI SDK** when your app already owns provider/config resolution (env vars, a secrets manager, feature flags), or when you need to reuse the same model instance for calls AskDB doesn’t make — for example, a separate `generateObject()` call for chart planning that sits next to `ask()` in your service. `@askdb/ai`’s registry only resolves models for AskDB’s own config shape, so if you need the model object for other LLM calls too, building it with the AI SDK directly is usually less code, not more.
If you’re an agent implementing this integration: check whether the host app already constructs AI SDK models elsewhere before reaching for `@askdb/ai` — duplicating provider config across two systems is the failure mode to avoid.
## In your config (CLI, Studio, HTTP API)
[Section titled “In your config (CLI, Studio, HTTP API)”](#in-your-config-cli-studio-http-api)
Set `ai.provider` in `askdb.config.ts` and supply the matching env var. The CLI, Studio, and the HTTP service call `createLanguageModelFromEnv` internally.
* OpenAI
askdb.config.ts
```ts
export default {
ai: {
provider: "openai",
providerConfig: {
openai: {
apiKey: env("OPENAI_API_KEY"),
},
},
},
// ...
};
```
Default model: `gpt-4o-mini`. To use a different one, set `ai.language.model` (the scaffolded config reads it from `OPENAI_MODEL`).
* Anthropic
askdb.config.ts
```ts
export default {
ai: {
provider: "anthropic",
providerConfig: {
anthropic: {
apiKey: env("ANTHROPIC_API_KEY"),
},
},
},
// ...
};
```
Default model: `claude-sonnet-4-6`. To use a different one, set `ai.language.model` (bind it to `ANTHROPIC_MODEL` in your config). Anthropic has no embeddings API, so for RAG set `ai.embedding.provider` to another provider and give it a connection.
* Google
askdb.config.ts
```ts
export default {
ai: {
provider: "google",
providerConfig: {
google: {
apiKey: env("GOOGLE_GENERATIVE_AI_API_KEY"),
},
},
},
// ...
};
```
* Azure OpenAI
askdb.config.ts
```ts
export default {
ai: {
provider: "azure",
providerConfig: {
azure: {
apiKey: env("AZURE_OPENAI_API_KEY"),
resourceName: env("AZURE_RESOURCE_NAME"),
},
},
},
// ...
};
```
Set `ai.language.model` to your deployment name (the scaffolded config reads it from `AZURE_OPENAI_DEPLOYMENT`).
* Vercel AI Gateway
askdb.config.ts
```ts
export default {
ai: {
provider: "gateway",
providerConfig: {
gateway: {
apiKey: env("AI_GATEWAY_API_KEY"),
},
},
language: { model: "anthropic/claude-sonnet-4-6" },
},
// ...
};
```
Gateway model ids are `/`. The default is `openai/gpt-4o-mini`. The gateway provider ships with `ai`, so it needs no extra package.
`ai.providerConfig` holds only the connection (key, endpoint, resource). The model goes in `ai.language`, and the embedding model for RAG in `ai.embedding`, which can use the same provider or another one. See [The `ai` block](/reference/config/#the-ai-block) for both sections, the full env-var table, and the custom-provider escape hatch.
## In your code (embedding)
[Section titled “In your code (embedding)”](#in-your-code-embedding)
When you embed `@askdb/core` directly, pass any Vercel AI SDK `LanguageModel` to `ask()`. AskDB calls the model with the assembled prompt and parses the SQL it returns. No proxy. No middleman.
```ts
import { ask } from "@askdb/core";
const { sql } = await ask({
question,
schema,
dialect: "postgres",
model, // any LanguageModel from the Vercel AI SDK
});
```
Install the provider package and construct the model. `ai` is a peer dependency of `@askdb/core` (AI SDK 6 or 7 are both supported), so it is installed alongside the provider package and AskDB uses whichever version your app pins:
* OpenAI
* npm
```bash
npm install ai @ai-sdk/openai
```
* pnpm
```bash
pnpm add ai @ai-sdk/openai
```
* yarn
```bash
yarn add ai @ai-sdk/openai
```
```ts
import { openai } from "@ai-sdk/openai";
// Reads OPENAI_API_KEY from the environment
const model = openai("gpt-4o-mini");
```
* Anthropic
```bash
npm install ai @ai-sdk/openai
```
* Google
```bash
pnpm add ai @ai-sdk/openai
```
* Azure OpenAI
```bash
yarn add ai @ai-sdk/openai
```
* OpenAI-compatible
* npm
```bash
npm install ai @ai-sdk/anthropic
```
* pnpm
```bash
pnpm add ai @ai-sdk/anthropic
```
* yarn
```bash
yarn add ai @ai-sdk/anthropic
```
```ts
import { anthropic } from "@ai-sdk/anthropic";
const model = anthropic("claude-sonnet-4-6");
```
* Vercel AI Gateway
```bash
npm install ai @ai-sdk/anthropic
```
* npm
```bash
pnpm add ai @ai-sdk/anthropic
```
* pnpm
```bash
yarn add ai @ai-sdk/anthropic
```
* yarn
* npm
```bash
npm install ai @ai-sdk/google
```
* pnpm
```bash
pnpm add ai @ai-sdk/google
```
* yarn
```bash
yarn add ai @ai-sdk/google
```
```ts
import { google } from "@ai-sdk/google";
// Reads GOOGLE_GENERATIVE_AI_API_KEY from the environment
const model = google("gemini-2.0-flash");
```
* npm
```bash
npm install ai @ai-sdk/google
```
* pnpm
```bash
pnpm add ai @ai-sdk/google
```
* yarn
```bash
yarn add ai @ai-sdk/google
```
* npm
* npm
```bash
npm install ai @ai-sdk/azure
```
* pnpm
```bash
pnpm add ai @ai-sdk/azure
```
* yarn
```bash
yarn add ai @ai-sdk/azure
```
```ts
import { createAzure } from "@ai-sdk/azure";
const azure = createAzure({
resourceName: process.env.AZURE_RESOURCE_NAME,
apiKey: process.env.AZURE_API_KEY,
});
const model = azure("your-deployment-name");
```
* pnpm
```bash
npm install ai @ai-sdk/azure
```
* yarn
```bash
pnpm add ai @ai-sdk/azure
```
* npm
```bash
yarn add ai @ai-sdk/azure
```
* pnpm
For self-hosted or alternative providers that expose the OpenAI chat-completions shape (vLLM, llama.cpp server, OpenRouter, Together, LM Studio, Ollama, …):
* npm
```bash
npm install ai @ai-sdk/openai-compatible
```
* pnpm
```bash
pnpm add ai @ai-sdk/openai-compatible
```
* yarn
```bash
yarn add ai @ai-sdk/openai-compatible
```
```ts
import { createOpenAICompatible } from "@ai-sdk/openai-compatible";
const local = createOpenAICompatible({
name: "local",
baseURL: "http://localhost:11434/v1",
apiKey: "ignored-by-local-server",
});
const model = local("llama3.1");
```
* yarn
```bash
npm install ai @ai-sdk/openai-compatible
```
* npm
```bash
pnpm add ai @ai-sdk/openai-compatible
```
* pnpm
```bash
yarn add ai @ai-sdk/openai-compatible
```
* yarn
* npm
```bash
npm install ai
```
* pnpm
```bash
pnpm add ai
```
* yarn
```bash
yarn add ai
```
```ts
import { gateway } from "ai";
// Reads AI_GATEWAY_API_KEY from the environment
const model = gateway("openai/gpt-4o-mini");
```
* npm
```bash
npm install ai
```
* pnpm
```bash
pnpm add ai
```
* yarn
```bash
yarn add ai
```
## One config driving both
[Section titled “One config driving both”](#one-config-driving-both)
If you embed AskDB but want to reuse the same `askdb.config.ts` instead of hardcoding a provider, use `@askdb/client`. `createAskDb` resolves the schema, model, and dialect from your config — the same resolution the CLI and the bundled HTTP API use. Install the AI SDK package for the provider your config selects (`@ai-sdk/openai`, `@ai-sdk/anthropic`, `@ai-sdk/google`, or `@ai-sdk/azure`; the AI Gateway needs none):
* npm
```bash
npm install @askdb/client @askdb/core @askdb/config ai @ai-sdk/openai
```
* pnpm
```bash
pnpm add @askdb/client @askdb/core @askdb/config ai @ai-sdk/openai
```
* yarn
```bash
yarn add @askdb/client @askdb/core @askdb/config ai @ai-sdk/openai
```
```ts
import { createAskDb } from "@askdb/client";
import { bootstrapAskDbEnv, getAskDbRuntimeConfig } from "@askdb/config";
bootstrapAskDbEnv({ cwd: process.cwd() });
const askdb = createAskDb({
config: getAskDbRuntimeConfig(), // ai.provider picks one of @askdb/ai's built-in providers
schema: { path: "./my-app.schema" }, // or set host.schemaPath in config and omit this
});
// Only the question — schema, model, and dialect come from config.
const { sql } = await askdb.ask("Which customers signed up last week?");
```
Every built-in provider is registered, and each loads its `@ai-sdk/*` package only when it first builds a model. If that package isn’t installed, the call fails with `Provider '' requires the optional peer dependency @ai-sdk/. Install it: npm i @ai-sdk/`. To restrict the set, pass `providers: ["openai"]`. To add a provider that isn’t built in, pass an `AiProviderAdapter` object in `providers`.
The `@askdb/ai-openai`, `@askdb/ai-anthropic`, `@askdb/ai-google`, and `@askdb/ai-azure` packages are deprecated. They re-export the built-in adapters, so `providers: [openaiProvider]` still works, but new code needs only `@askdb/client` (or `@askdb/ai`) plus the `@ai-sdk/*` package.
Need the model object yourself (to pass to `ask()` directly, or to share with other code)? Build it from the same config with `@askdb/ai`’s registry — the one advanced case where you import `@askdb/ai` directly:
```ts
import { bootstrapAskDbEnv, getAskDbRuntimeConfig } from "@askdb/config";
import { createAiRegistry } from "@askdb/ai";
bootstrapAskDbEnv({ cwd: process.cwd() });
const rt = getAskDbRuntimeConfig();
const ai = createAiRegistry(); // every built-in provider; or createAiRegistry(["openai"])
const model = await ai.createLanguageModelFromEnv(rt.ai.aiEnv);
```
`@askdb/ai` declares `ai` as a peer dependency and the `@ai-sdk/*` provider packages as optional peers. Add `ai` and the provider package you use to your own `package.json` so you control their versions.
## Reasoning/latency effort
[Section titled “Reasoning/latency effort”](#reasoninglatency-effort)
Set `ai.language.reasoning` in `askdb.config.ts` (see the [config reference](/reference/config/#reasoning-effort)) for the config-driven path. Skip it and current behavior is unchanged — no `providerOptions` are sent, and the provider/model uses its own default.
**With `@askdb/client`**, `createAskDb` resolves `ai.language.reasoning.nlToSql`/`effort` automatically — nothing else to wire. Override per call, or set a client-level default:
```ts
const askdb = createAskDb({
config: getAskDbRuntimeConfig(),
reasoningEffort: "medium", // client-level default, overrides ai.language.reasoning from config
});
const { sql } = await askdb.ask("Which customers signed up last week?", {
reasoningEffort: "low", // per-call override, overrides the client default
});
```
**Programmatically**, resolve the portable effort to provider `providerOptions` with `@askdb/ai`’s registry, then forward it to `ask()`’s `deps.providerOptions` — `@askdb/core` forwards it verbatim to `generateText` and never interprets it:
```ts
import { createAiRegistry } from "@askdb/ai";
import { ask } from "@askdb/core";
const ai = createAiRegistry(["openai"]);
const config = ai.resolveAiConfig(rt.ai.aiEnv)!; // e.g. { provider: "openai", model: "o4-mini", ... }
const model = await ai.createLanguageModel(config);
// Provider-portable: "minimal" | "low" | "medium" | "high".
// Returns undefined (nothing sent) when the model doesn't support reasoning tuning.
const providerOptions = ai.resolveProviderOptions(config, { reasoningEffort: "low" });
const { sql } = await ask({
question,
schema,
dialect: "postgres",
model,
deps: { providerOptions },
});
```
## Key management
[Section titled “Key management”](#key-management)
Your model API key lives in your environment, not in the schema artifact and not in AskDB. The CLI loads `.env` for local work; in production, supply the key the same way you supply your database URL.
AskDB has no API of its own to authenticate — it’s a library. The only credentials it touches are the ones you pass to your model provider through the AI SDK.
## Switching models
[Section titled “Switching models”](#switching-models)
Models can be swapped without changing any other AskDB code. A common pattern: cheaper model for low-stakes analytics, stronger model for complex multi-join queries.
```ts
import { openai } from "@ai-sdk/openai";
const cheapModel = openai("gpt-4o-mini");
const strongModel = openai("gpt-4o");
const model = question.length > 200 ? strongModel : cheapModel;
const { sql } = await ask({ question, schema, dialect: "postgres", model });
```
## Cost
[Section titled “Cost”](#cost)
You’re billed by your model provider for every `ask()` call. Cost scales with:
* Schema size (larger artifacts mean more tokens in the prompt) — use [RAG for large schemas](/guides/rag-for-large-schemas/) to send only the relevant slice. AskDB handles the chunking, embedding, and retrieval; you configure the store and it takes care of the rest.
* Question length.
* Model tier.
AskDB itself is Apache 2.0-licensed and free.
## Read next
[Section titled “Read next”](#read-next)
[**Embed in a Node app**The full TypeScript walkthrough including model wiring.](/guides/embed-in-node/)[**RAG for large schemas**Cut your token bill by sending only the relevant schema slice per question.](/guides/rag-for-large-schemas/)[**Privacy model**What the model sees and what it doesn’t.](/concepts/privacy-model/)
# Deploy AskDB as an HTTP service
> Stand up @askdb/http-api so Python, browsers, agents — anything that speaks HTTP — can ask questions.
Service guide
`@askdb/http-api` wraps the same `ask()` pipeline behind a minimal HTTP server. Use it when non-Node clients need to ask questions, or when you want one AskDB service shared across multiple consumers.
## Install
[Section titled “Install”](#install)
* npm
```bash
npm install @askdb/http-api @askdb/postgres ai @ai-sdk/openai
```
* pnpm
```bash
pnpm add @askdb/http-api @askdb/postgres ai @ai-sdk/openai
```
* yarn
```bash
yarn add @askdb/http-api @askdb/postgres ai @ai-sdk/openai
```
## Start the server
[Section titled “Start the server”](#start-the-server)
The package ships an `askdb-http` binary — for most deployments you don’t write any server code:
```bash
npx askdb-http --schema-path ./my-app.schema --port 3000
```
All flags are optional; each falls back to `askdb.config.ts` (`host.schemaPath`, `httpApi.listen.port`, `httpApi.listen.host`), then to built-in defaults.
To embed the server in your own process instead, use the programmatic API:
server.ts
```ts
import { createAskDbHttpServer } from "@askdb/http-api";
const server = createAskDbHttpServer({
port: 3000,
host: "127.0.0.1",
maxBodyBytes: 1024 * 1024, // 1 MiB default
});
server.listen();
```
Either way, the server reads its schema and model settings from your `askdb.config.ts` (it bootstraps the same config file the CLI and Studio use). Set `host.schemaPath` to point at your schema artifact and configure the AI provider as usual — supply the provider key (`OPENAI_API_KEY`, etc.) in your environment the same way you do for the CLI.
## Endpoints
[Section titled “Endpoints”](#endpoints)
The server exposes two endpoints:
### `GET /health`
[Section titled “GET /health”](#get-health)
```bash
curl http://localhost:3000/health
# {"ok":true}
```
### `POST /ask`
[Section titled “POST /ask”](#post-ask)
Body:
```json
{
"question": "Which customers signed up last week?",
"mode": "schema_only",
"explain": false
}
```
Response (success):
```json
{
"ok": true,
"correlationId": "01H…",
"sql": "SELECT id, name, created_at FROM customers WHERE created_at >= …"
}
```
The response is SQL only — the server does not run it. Your client takes the SQL and decides what to do with it.
## Calling from curl
[Section titled “Calling from curl”](#calling-from-curl)
```bash
curl -X POST http://localhost:3000/ask \
-H "content-type: application/json" \
-d '{"question": "How many customers signed up last week?"}'
```
## Calling from Python
[Section titled “Calling from Python”](#calling-from-python)
```python
import os
import httpx
resp = httpx.post(
f"{os.environ['SERVER_URL']}/ask",
json={"question": "How many customers signed up last week?"},
timeout=30,
)
resp.raise_for_status()
body = resp.json()
if body["ok"]:
sql = body["sql"]
correlation_id = body["correlationId"]
# Run the SQL against your read-only role here.
else:
raise RuntimeError(body["error"]["code"])
```
## Run it behind a gateway
[Section titled “Run it behind a gateway”](#run-it-behind-a-gateway)
`@askdb/http-api` is intentionally minimal — there is no built-in auth, rate limiting, or TLS termination. **Don’t expose it directly to the public internet.** Put it behind your existing API gateway, ingress, or reverse proxy and apply the same auth you use for the rest of your services.
A typical production shape:
```plaintext
client ──► your API gateway ──► @askdb/http-api ──► model + schema
│ │
│ ▼
└────────────────► read-only DB role ◄─── (execution happens in your gateway service, not here)
```
The server does not connect to your database. It generates SQL and returns it. Execution is your gateway service’s job — that’s where your auth context lives.
## Custom schema per request
[Section titled “Custom schema per request”](#custom-schema-per-request)
The default is to load the schema from `host.schemaPath` once at boot. If you need per-request schema (for example, a multi-product deployment where different consumers send different schemas), supply the bundled JSON as `schemaJson` in the request body:
```json
{
"question": "How many users?",
"schemaJson": "{\"version\":2,\"schemaId\":\"…\",\"tables\":[…]}"
}
```
Bundle the artifact with `askdb bundle` and ship the resulting JSON as the value.
## Correlation IDs
[Section titled “Correlation IDs”](#correlation-ids)
Every response includes a `correlationId`. The server emits structured log events tagged with the same ID — so you can join HTTP requests to the generated SQL and any errors in your log pipeline.
## Read next
[Section titled “Read next”](#read-next)
[**Run safely in production**The execution-side checklist your gateway service needs.](/guides/run-safely-in-prod/)[**HTTP API reference**Every endpoint, request shape, and error code.](/reference/http-api/)[**Embed in a Node app**For when you want to skip HTTP and link the library directly.](/guides/embed-in-node/)
# Embed AskDB in a Node app
> Add natural-language SQL to a TypeScript service in twenty lines: load a schema, call ask(), run the SQL through your own pool.
Integrator guide
Drop `@askdb/client` into a TypeScript service. It reads the same `askdb.config.ts` the CLI and Studio use, generates checked SQL from a question, and hands it back. Your service runs it through its own connection pool against a read-only role.
## Install
[Section titled “Install”](#install)
* npm
```bash
npm install @askdb/client @askdb/core @askdb/config ai @ai-sdk/openai pg
```
* pnpm
```bash
pnpm add @askdb/client @askdb/core @askdb/config ai @ai-sdk/openai pg
```
* yarn
```bash
yarn add @askdb/client @askdb/core @askdb/config ai @ai-sdk/openai pg
```
| Package | Why |
| ------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `@askdb/client` | `createAskDb()` — resolves the schema, model, and dialect from config. |
| `@ai-sdk/openai` | The AI SDK package for the provider your config selects. Swap it for `@ai-sdk/anthropic`, `@ai-sdk/google`, or `@ai-sdk/azure` (the Vercel AI Gateway needs none). AskDB loads it on first use. |
| `@askdb/config` | Loads `.env` and `askdb.config.ts` at startup. |
| `@askdb/core`, `ai` | Required peer dependencies of `@askdb/client` (`ai` at AI SDK 7). npm and pnpm add them for you; Yarn doesn’t, so list them. |
| `pg` | The Postgres driver. AskDB doesn’t open the connection; your app does. |
## Wire it into a handler
[Section titled “Wire it into a handler”](#wire-it-into-a-handler)
Call `createAskDb` once at startup, then `askdb.ask(question)` per request. Schema, model, and dialect all resolve from `askdb.config.ts` — the same file `askdb init` scaffolded.
ask-handler.ts
```ts
import { createAskDb } from "@askdb/client";
import { bootstrapAskDbEnv, getAskDbRuntimeConfig } from "@askdb/config";
import { Pool } from "pg";
bootstrapAskDbEnv({ cwd: process.cwd() });
const askdb = createAskDb({
config: getAskDbRuntimeConfig(), // ai.provider picks the model
schema: { path: "./my-app.schema" }, // or set host.schemaPath in config and omit
});
const pool = new Pool({
connectionString: process.env.DATABASE_URL,
// Run under a read-only role for defense in depth.
statement_timeout: 5000,
max: 10,
});
export async function askQuestion(question: string) {
const { sql } = await askdb.ask(question);
// Audit hook — log every question and generated SQL.
console.log({ question, sql });
const { rows } = await pool.query(sql);
return { sql, rows };
}
```
`./my-app.schema` is a **directory**, not a file — `.schema/` is AskDB’s convention for the introspected-and-enriched artifact. The schema loads once at startup and stays in memory; call `askdb.reload()` if the artifact changes while the process runs.
Note
This example uses `pg` to run the SQL, but the driver is your choice — AskDB never opens a connection. If you already use an ORM or query builder (Prisma, Drizzle, Sequelize, Knex, …), skip `pg` entirely and pass the returned `sql` string to your existing client, e.g. `prisma.$queryRawUnsafe(sql)` or `db.execute(sql)`.
That’s the whole pipeline. AskDB returns checked SQL — your handler logs it, runs it, and returns the result.
Caution
AskDB’s SQL checks catch common model mistakes but aren’t a security boundary. Connect `DATABASE_URL` as a read-only, least-privilege role and keep `statement_timeout` set. See [Run generated SQL safely](/concepts/safety-boundaries/#run-generated-sql-safely).
## What the call returns
[Section titled “What the call returns”](#what-the-call-returns)
`askdb.ask()` (and the direct `ask()` below) return `AskPipelineResult`. All fields except `sql` are optional:
| Field | Type | When present |
| ----------------- | -------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `sql` | `string` | Always. The generated, checked SQL string. |
| `unboundSql` | `string \| undefined` | When `parameterize` is on (default) and the model returned consistent extras. Driver markers. |
| `params` | `QueryParamSlot[] \| undefined` | Values for `unboundSql`, in marker order (includes tenant IDs in `tenantSqlMode: "sql-params"`). |
| `parameters` | `QueryParameterBinding[] \| undefined` | Named bindings for form UIs (includes values). |
| `preparedQuery` | `PreparedQuery \| undefined` | Definitions + template for `bindPreparedQuery()` (no values). |
| `usage` | `AskUsage \| undefined` | When the model provider reports token counts: `promptTokens`, `completionTokens`, `totalTokens` (each `number \| null`). Use it for cost tracking or quota enforcement. |
| `explain` | `unknown \| undefined` | When `explain: true` is passed. Heuristic guardrail metadata — which read-only rules fired and why. |
| `tenantGuardrail` | `TenantGuardrailResult \| undefined` | When a tenant policy is active. Whether the SQL references tenant-scoped tables correctly. |
| `tenantParams` | `unknown[] \| undefined` | When `tenantSqlMode: "sql-params"` is set. Tenant IDs for the markers in `sql` — run `sql` with `tenantParams`, or `unboundSql` with `params`; never concatenate them. |
| `tenantBindings` | `TenantBinding[] \| undefined` | When tenant scope bindings were resolved. Structured binding metadata for audit logging. |
```ts
import { bindPreparedQuery } from "@askdb/core";
const result = await askdb.ask(question, { tenantScope });
await pool.query(result.sql);
await pool.query(result.unboundSql!, result.params);
const rebound = bindPreparedQuery(result.preparedQuery!, {
state_name: "Utah",
":tenant_agency_ids": authorizedAgencyIds,
});
await pool.query(rebound.sql);
if (result.usage) {
console.log(`Tokens — prompt: ${result.usage.promptTokens}, completion: ${result.usage.completionTokens}`);
}
```
Every `ask()` is still one model call. Set `{ parameterize: false }` to skip the extra output tokens. `bindPreparedQuery` does not authorize tenant IDs.
The full result and option types are in the [@askdb/core API reference](/reference/core-api/).
## Advanced: call `ask()` directly
[Section titled “Advanced: call ask() directly”](#advanced-call-ask-directly)
`createAskDb` is a convenience layer over `@askdb/core`’s pure `ask()` — not a replacement. Drop down to `ask()` when you construct the model yourself, serve multiple schemas from one process, or want zero dependency on `@askdb/config` / `@askdb/ai`.
* npm
```bash
npm install @askdb/core ai @ai-sdk/openai pg
```
* pnpm
```bash
pnpm add @askdb/core ai @ai-sdk/openai pg
```
* yarn
```bash
yarn add @askdb/core ai @ai-sdk/openai pg
```
`ai` is a required peer dependency of `@askdb/core` (AI SDK 6 or 7) — your app owns its version.
Dialects for all four engines are built into `@askdb/core` — install `@askdb/postgres` only if this service also runs `askdb introspect` programmatically.
ask-handler.ts
```ts
import { ask, loadSchema } from "@askdb/core";
import { openai } from "@ai-sdk/openai";
import { Pool } from "pg";
// loadSchema is synchronous; it autodetects the artifact directory,
// a bundled .bundle.json, or a bare schema.json. Load once at startup.
const schema = loadSchema("./my-app.schema");
const model = openai("gpt-4o-mini");
const pool = new Pool({ connectionString: process.env.DATABASE_URL });
export async function askQuestion(question: string) {
const { sql } = await ask({
question,
schema,
dialect: "postgres",
model,
});
const { rows } = await pool.query(sql);
return { sql, rows };
}
```
Every option `ask()` takes — modes, tenant scope, retrieval, sensitive-field handling — is in the [@askdb/core API reference](/reference/core-api/). The same options work as per-call overrides on `askdb.ask(question, overrides)`.
## Switching engines
[Section titled “Switching engines”](#switching-engines)
Same `ask()` call, different dialect string. Change `dialect: "postgres"` to `"mysql"`, `"sqlite"`, or `"sqlserver"`. See [Switch engines](/guides/switch-engines/) for the full migration matrix.
## Complete example: Express server
[Section titled “Complete example: Express server”](#complete-example-express-server)
The snippet below is a copy-paste-ready Express server. Schema, model, and dialect are fully config-driven — `askdb.config.ts` sets `host.schemaPath` and the AI provider; `server.ts` only handles HTTP.
The `/ask` endpoint accepts an optional `execute` flag: `false` (default) returns just the SQL; `true` also runs it through a `pg.Pool` and returns the rows. This keeps SQL generation and execution decoupled — your service controls both.
server.ts
```ts
import { createAskDb } from "@askdb/client";
import { bootstrapAskDbEnv, getAskDbRuntimeConfig } from "@askdb/config";
import express, { Request, Response } from "express";
import pg from "pg";
bootstrapAskDbEnv({ cwd: process.cwd() });
const app = express();
app.use(express.json());
const askdb = createAskDb({
config: getAskDbRuntimeConfig(),
// schema resolved from host.schemaPath in askdb.config.ts
});
const pool = process.env.DATABASE_URL
? new pg.Pool({ connectionString: process.env.DATABASE_URL })
: null;
app.post("/ask", async (req: Request, res: Response) => {
const { question, execute } = req.body as { question?: string; execute?: boolean };
if (!question || typeof question !== "string" || question.trim() === "") {
res.status(400).json({ error: "question is required and must be a non-empty string" });
return;
}
const shouldExecute = execute === true;
if (shouldExecute && !pool) {
res.status(500).json({ error: "DATABASE_URL is not configured" });
return;
}
try {
const { sql } = await askdb.ask(question.trim());
console.log({ question, sql, execute: shouldExecute });
if (!shouldExecute) {
res.json({ sql });
return;
}
const result = await pool!.query(sql);
res.json({ sql, rows: result.rows, rowCount: result.rowCount });
} catch (err) {
const message = err instanceof Error ? err.message : String(err);
res.status(500).json({ error: message });
}
});
app.get("/health", (_req: Request, res: Response) => {
res.json({ status: "ok" });
});
app.listen(3000, () => console.log("listening on http://localhost:3000"));
```
askdb.config.ts
```ts
import { defineConfig, env, type AskDbConfig } from "@askdb/config";
export default defineConfig({
ai: {
provider: "openai",
providerConfig: { openai: { apiKey: env("OPENAI_API_KEY") } },
},
introspection: {
provider: "postgres",
providerConfig: { postgres: { databaseUrl: env("DATABASE_URL") } },
},
host: {
schemaPath: env("ASKDB_SCHEMA_PATH"),
},
} satisfies AskDbConfig);
```
The full working package (with `package.json`, `tsconfig.json`, and `.env` instructions) lives in [examples/express-server](https://github.com/Ygilany/AskDB/tree/main/examples/express-server) in the repo.
## Read next
[Section titled “Read next”](#read-next)
[**Run safely in production**The operator checklist: roles, timeouts, audit, approval.](/guides/run-safely-in-prod/)[**Deploy as HTTP service**Use @askdb/http-api instead of rolling your own.](/guides/deploy-as-http-service/)[**Author your schema**Make generation better by enriching the artifact.](/guides/author-your-schema/)[**Package reference**The full API surface for every @askdb/\* package.](/reference/packages/)
# Agents and MCP
> What works today for agent integration — CLI, library, HTTP API — and the status of a first-party Model Context Protocol server.
Integration · Agents
AskDB is built to be machine-driven. Agents can ground SQL generation through the same surfaces human integrators use — the CLI, the library, and the HTTP API. A first-party Model Context Protocol (MCP) server is roadmap work; for now, wrap one of the existing surfaces.
## What works today
[Section titled “What works today”](#what-works-today)
| Surface | When to use it |
| ------------ | ------------------------------------------------------------------------------------------------------------------------------- |
| **CLI** | Stable flags and structured logs. Good for scripted pipelines and CI. |
| **Library** | Embed `ask()` directly in your agent runtime — fastest path for Node agents. See [Embed in a Node app](/guides/embed-in-node/). |
| **HTTP API** | `@askdb/http-api` for agents in any language. See [Deploy as HTTP service](/guides/deploy-as-http-service/). |
All three surfaces use the same `@askdb/core` pipeline and run the same SQL checks, whichever you wrap. Those checks are heuristic defense in depth, not a security boundary. An agent can send any question it likes, so run the SQL it gets back under a read-only, least-privilege role. See [Run generated SQL safely](/concepts/safety-boundaries/#run-generated-sql-safely).
## MCP status
[Section titled “MCP status”](#mcp-status)
A first-party Model Context Protocol server is planned. It will expose the same `ask()` contract through the MCP protocol so any MCP-aware agent (Claude Desktop, Cursor, IDE integrations) can call AskDB as a tool.
Until it ships, the recommended pattern is to write a thin MCP adapter in your own host that calls the HTTP API or the library directly. Your adapter enforces the same trust boundaries — modes, sensitive-field handling, which schema artifact is loaded — that the first-party MCP server will.
Track the roadmap on the [AskDB GitHub project](https://github.com/Ygilany/AskDB).
## Wrapping AskDB as a tool
[Section titled “Wrapping AskDB as a tool”](#wrapping-askdb-as-a-tool)
A typical agent tool definition for AskDB looks like:
```ts
import { createAskDb } from "@askdb/client";
import { bootstrapAskDbEnv, getAskDbRuntimeConfig } from "@askdb/config";
// Initialize once at startup — schema, model, and dialect resolve from config
// (install the @ai-sdk/* package for your ai.provider, e.g. @ai-sdk/openai).
bootstrapAskDbEnv({ cwd: process.cwd() });
const askdb = createAskDb({
config: getAskDbRuntimeConfig(),
schema: { path: "./my-app.schema" },
});
{
name: "ask_database",
description: "Translate a natural-language question into SQL " +
"against the application database. Returns SQL — execution is " +
"the caller's responsibility.",
parameters: {
type: "object",
properties: {
question: { type: "string" },
},
required: ["question"],
},
async invoke({ question }) {
const { sql } = await askdb.ask(question);
return { sql };
},
}
```
This works in Vercel AI SDK tools, OpenAI function calls, Anthropic tool use, and any other agent framework that takes a function and a schema.
## Trust in an agent loop
[Section titled “Trust in an agent loop”](#trust-in-an-agent-loop)
Two things matter when AskDB sits inside an agent:
1. **The agent never executes SQL directly.** It calls `ask()` and gets back checked SQL — your host code decides whether and how to run it.
2. **The agent operates under a tenant scope you supply.** When the schema has tenant policy, pass `tenantScope` from your host’s auth context — not from anything the agent (or the user) sent.
## Read next
[Section titled “Read next”](#read-next)
[**Embed in a Node app**The library surface you’ll most likely wrap in an agent tool.](/guides/embed-in-node/)[**Deploy as HTTP service**The HTTP surface for non-Node agents.](/guides/deploy-as-http-service/)[**Safety boundaries**What the SQL checks cover, what they don’t, and how to run generated SQL safely.](/concepts/safety-boundaries/)
# Prisma
> Use @askdb/prisma to read your schema directly from a .prisma file — no live database required.
Integration · Prisma
If you already maintain a Prisma schema file, `@askdb/prisma` reads it directly and produces an AskDB schema artifact. No live database connection during introspection.
## When to use it
[Section titled “When to use it”](#when-to-use-it)
* You have a `schema.prisma` and want to skip the live-database introspection step.
* You’re working in CI, on a laptop without DB access, or in an air-gapped environment.
* You pair it with `@askdb/postgres` (or another engine) for the actual SQL dialect at generation time.
## Install
[Section titled “Install”](#install)
* npm
```bash
npm install @askdb/prisma @askdb/introspect ai
```
* pnpm
```bash
pnpm add @askdb/prisma @askdb/introspect ai
```
* yarn
```bash
yarn add @askdb/prisma @askdb/introspect ai
```
Plus the engine you want at runtime — for example, Postgres:
* npm
```bash
npm install @askdb/core @askdb/postgres ai @ai-sdk/openai
```
* pnpm
```bash
pnpm add @askdb/core @askdb/postgres ai @ai-sdk/openai
```
* yarn
```bash
yarn add @askdb/core @askdb/postgres ai @ai-sdk/openai
```
`@askdb/prisma` doesn’t bundle a SQL dialect — pair it with whichever engine package matches your runtime database.
## CLI workflow
[Section titled “CLI workflow”](#cli-workflow)
```bash
# Introspect a Prisma schema file (or directory of .prisma files)
npx askdb introspect \
--engine prisma \
--prisma-schema ./prisma/schema.prisma \
--out my-app.schema \
--schema-id my-app
# Print the introspection result without writing
npx askdb introspect --engine prisma --prisma-schema ./prisma --print
# Diff against an existing schema artifact
npx askdb introspect --engine prisma --prisma-schema ./prisma --diff my-app.schema
```
To make `--prisma-schema` optional on repeat runs, set `introspection.providerConfig.prisma.schemaPath` in `askdb.config.ts` — or rely on auto-discovery: with `provider: "prisma"` and no path configured, AskDB finds `prisma/schema.prisma` (or `schema.prisma`) in your project root automatically.
## Programmatic API
[Section titled “Programmatic API”](#programmatic-api)
```ts
import { introspect } from "@askdb/introspect";
import { createPrismaConnector } from "@askdb/prisma";
await introspect(
{ schemaPath: "./prisma", schemaId: "my-app" },
{ outDir: "my-app.schema", schemaId: "my-app" },
{ connector: createPrismaConnector() },
);
```
## Supported providers
[Section titled “Supported providers”](#supported-providers)
`@askdb/prisma` supports any Prisma relational provider — at generation time, pair it with the matching AskDB engine adapter:
| Prisma provider | Runtime engine adapter |
| ---------------------------- | ---------------------- |
| `postgresql` / `cockroachdb` | `@askdb/postgres` |
| `mysql` | `@askdb/mysql` |
| `sqlite` | `@askdb/sqlite` |
| `sqlserver` | `@askdb/sqlserver` |
MongoDB is not supported — AskDB targets relational engines.
## What it doesn’t do
[Section titled “What it doesn’t do”](#what-it-doesnt-do)
`@askdb/prisma` is a file-only connector. It does not connect to a database, it does not execute generated SQL, and it does not include a SQL dialect. For SQL generation, supply a dialect from one of the engine packages above.
## Read next
[Section titled “Read next”](#read-next)
[**Quickstart**The full introspect → enrich → ask flow.](/quickstart/)[**Switch engines**How to pair @askdb/prisma with each runtime engine.](/guides/switch-engines/)
# Multi-tenancy
> Declare tenant policy in your schema artifact so AskDB prompts for tenant filters, binds your tenant IDs, and flags generated queries that look unscoped.
Tenant-scoped generation
Tell AskDB how your schema represents tenancy. From then on, the model is instructed to filter every scoped table by tenant, AskDB binds your tenant IDs into the SQL, and a heuristic check flags queries that look unscoped. Your app supplies the tenant scope per request.
## How it works
[Section titled “How it works”](#how-it-works)
Tenant policy is a file (`tenant-policy.md`) in your schema artifact. It declares the tables that belong to a tenant, which column carries the tenant ID, and which tables are global.
AskDB doesn’t execute queries, and it doesn’t rewrite them to add a tenant filter. It works in three steps:
1. **Prompt.** The policy and the caller’s scope go into the prompt. The model is told to filter every scoped table with a named placeholder such as `:tenant_organization_ids`.
2. **Check.** AskDB checks the model’s SQL while the placeholders are still in place: each tenant-scoped table named in the statement, and each root table the scope covers, needs a tenant predicate that filters. See [What the tenant check requires](#what-the-tenant-check-requires). Text inside string literals and comments doesn’t count.
3. **Bind.** AskDB replaces the placeholders with the IDs from your `tenantScope`, as escaped inline literals or as your driver’s parameter markers. A placeholder it can’t bind throws instead of being returned raw.
Your application supplies the tenant scope per call and is responsible for authorizing it.
Enforce tenancy in your database
The tenant check is heuristic and does not parse SQL. It rejects the common ways a filter fails to filter, such as `WHERE organization_id = :tenant_organization_ids OR 1=1`, a literal tenant ID, or `SELECT organization_id FROM documents` with no filter. But within one query it doesn’t tie a predicate to a particular table reference, so an unfiltered reference next to a filtered one can still pass. In production, enforce tenant isolation in the database, for example with Postgres row-level security or per-tenant views, and treat AskDB’s check as an early warning. See [Run generated SQL safely](/concepts/safety-boundaries/#run-generated-sql-safely).
## Tenant policy concepts
[Section titled “Tenant policy concepts”](#tenant-policy-concepts)
| Concept | What it means |
| ---------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Tenant roots** | The primary tenant-identifying table (e.g. `organizations`) and its `tenantIdColumn`. |
| **Hierarchy** | Parent→child foreign-key relationships between tenant roots (agency → sub-agency → client). |
| **Scoped tables** | Tables that belong to a tenant via foreign key. The model is told to include the join or predicate, and the tenant check flags SQL without a tenant predicate that filters. |
| **Polymorphic tables** | Tables that reference multiple entity types via a discriminator column (`owner_type` / `owner_id`). |
| **Global tables** | Tenant-agnostic lookup tables (currencies, countries). Never tenant-filtered. |
## Authoring the policy
[Section titled “Authoring the policy”](#authoring-the-policy)
The recommended path is Studio’s **Tenancy** view, which guides you through declaring tenant roots, scoped tables, and global tables in a form. Studio can also AI-draft a policy from a plain-language description of your tenancy model, for your review.
You can also write `tenant-policy.md` by hand. The front-matter is YAML, validated strictly when the schema artifact loads — unknown keys are rejected, and every table or column reference uses the **stable IDs** from `schema.json` (`table:public.projects`, `table:public.projects#organization_id`), never bare names. Example for a simple SaaS schema:
```yaml
---
schemaId: my-app
enforcement: strict
roots:
- id: table:public.organizations
tenantIdColumn: table:public.organizations#id
label: Organization
scopedTables:
- id: table:public.projects
scopeThrough:
- root: table:public.organizations
column: table:public.projects#organization_id
- id: table:public.documents
scopeThrough:
- root: table:public.organizations
column: table:public.documents#organization_id
globalTables:
- table:public.plan_tiers
- table:public.countries
---
# Tenant Policy
Organizations are the only tenant level. Projects and documents carry a
direct `organization_id`; plan tiers and countries are shared lookups.
```
The markdown body below the front-matter is free-form business context; the `Hierarchy`, `Scope rules`, and `Sensitive interactions` H2 sections are recognized and fed into prompt assembly.
## Field reference
[Section titled “Field reference”](#field-reference)
Top-level front-matter fields:
| Field | Required | Meaning |
| ------------------- | -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `schemaId` | yes | Must match the `schemaId` in the artifact’s `schema.json`. Ties the policy to one schema. |
| `enforcement` | yes | What happens when the tenant check finds a problem (see [What the tenant check requires](#what-the-tenant-check-requires)). `strict` throws `TenantGuardrailError`; `warn` returns the SQL with the findings in `tenantGuardrail.warnings`. Start with `strict`. Neither mode proves the query is correctly scoped. |
| `roots` | yes | The tables that *are* tenants (at least one). Everything else is scoped relative to a root. |
| `hierarchy` | no | Parent→child edges between roots (agency → sub-agency → client). Must form a cycle-free graph. |
| `scopedTables` | no | Tables whose rows belong to a tenant, and how to reach the root from them. |
| `polymorphicTables` | no | Tables that reference different tenant types via a discriminator column pair. |
| `globalTables` | no | Stable table IDs intentionally exempt from tenant filtering (shared lookups). |
Tables that appear in none of `scopedTables`, `polymorphicTables`, or `globalTables` are classified **unknown** — a query that names one triggers a warning, and in `strict` mode an error. Classify everything.
`roots[]` — each entry is one tenant-identifying table:
| Field | Required | Meaning |
| ---------------------------------- | -------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `id` | yes | Stable table ID (e.g. `table:public.organizations`). |
| `tenantIdColumn` | yes | Stable column ID of the root’s identifier — the value your app passes at runtime. |
| `label` | yes | Human-readable name used in prompts and named placeholders (`Organization` → `:tenant_organization_ids`). The placeholder keeps only ASCII letters and digits from the label; a label with none (for example Cyrillic or CJK) uses the root’s table name instead (`Клиент` on `table:public.clients` → `:tenant_clients_ids`). Each root needs a different placeholder: `Agency` and `agency`, or `Sub-Agency` and `Sub Agency`, fail to load. To get a root’s placeholder in code, call `placeholderForTenantRoot(root)` from `@askdb/core`; the older `placeholderForRoot(label)` is deprecated and returns `:tenant___ids` for a label with no ASCII letters or digits. |
| `parent.root`, `parent.foreignKey` | no | When this root is a child of another root: the parent’s table ID and the FK column linking to it. |
`scopedTables[]` — operational tables constrained by a tenant:
| Field | Required | Meaning |
| ----------------------- | -------- | ------------------------------------------------------------------------------------------------------------------------------------- |
| `id` | yes | Stable table ID. |
| `scopeThrough` | yes | One or more paths from this table to a root. Each path has `root` plus **exactly one of** `column` or `join`. |
| `scopeThrough[].column` | one of | Stable column ID of a direct tenant FK on this table (`table:public.projects#organization_id`). |
| `scopeThrough[].join` | one of | A list of `{ from, to }` stable-column-ID steps when the table reaches its root through other tables (e.g. `appointments → clients`). |
A table may declare several `scopeThrough` paths (e.g. scoped directly by `agency_id` *and* through `client_id` → clients); the check passes when any one path has its tenant predicate. For a `column` path, that’s the column compared with its root’s placeholder. For a `join` path, every step’s `from` and `to` columns must appear, plus a tenant predicate on a column that carries the IDs of the path’s root or one of its ancestors (the root’s `tenantIdColumn`, or a child root’s foreign key to it).
`polymorphicTables[]` — type + id discriminator pairs:
| Field | Required | Meaning |
| ------------ | -------- | --------------------------------------------------------------------------------------------------- |
| `id` | yes | Stable table ID. |
| `typeColumn` | yes | Stable column ID of the discriminator (e.g. `table:public.notes#owner_type`). |
| `idColumn` | yes | Stable column ID of the polymorphic FK (e.g. `table:public.notes#owner_id`). |
| `mapping` | yes | Maps each literal `typeColumn` value to a tenant root’s table ID (`agency: table:public.agencies`). |
The full contract — including hierarchy validation rules and the five scoping patterns these fields express — lives in [`docs/contracts/tenant-policy.md` on GitHub](https://github.com/Ygilany/AskDB/blob/main/docs/contracts/tenant-policy.md).
## Asking with a tenant scope
[Section titled “Asking with a tenant scope”](#asking-with-a-tenant-scope)
When the policy exists, every `ask()` call must include a `tenantScope`; without one, `ask()` throws `TenantScopeError` before calling the model. AskDB validates the scope’s shape against the policy and binds its IDs into the placeholders the model wrote. When the tenant check finds a problem, `enforcement: strict` throws `TenantGuardrailError`, and `enforcement: warn` returns the SQL with the findings in `result.tenantGuardrail.warnings` for your application to act on.
### What the tenant check requires
[Section titled “What the tenant check requires”](#what-the-tenant-check-requires)
AskDB checks the model’s SQL before it binds the tenant IDs, while the `:tenant__ids` placeholders are still in place. The check covers every tenant-scoped table the query mentions:
* **A real predicate.** The table’s tenant column is compared with its root’s placeholder: `agency_id = :tenant_agency_ids`, `agency_id IN (:tenant_agency_ids)` or `agency_id = ANY(:tenant_agency_ids)`.
* **ANDed into the filter.** The predicate sits in a `WHERE` clause, an inner join’s `ON` clause, or a `HAVING` clause; an outer join’s `ON` doesn’t filter the preserved side, so it doesn’t count. It can’t be next to an `OR` at its own level, under `NOT`, or in the select list. `agency_id = :tenant_agency_ids AND (status = 'a' OR status = 'b')` is fine; `agency_id = :tenant_agency_ids OR 1 = 1` is rejected.
* **No literal IDs.** `agency_id = 2` doesn’t satisfy the rule, even when 2 is in the caller’s scope: AskDB binds the IDs. Each `UNION` branch that reads a scoped table needs its own predicate.
* **Root tables too.** A query on the root table itself (`agencies`) needs the predicate on its tenant ID column.
It’s a heuristic over the SQL’s tokens, not a parser. Within one query it doesn’t tie each predicate to a specific table reference, so an unfiltered reference next to a filtered one can still pass. Use it as defense in depth, together with database-side row-level security and a read-only role: see [Run safely in production](/guides/run-safely-in-prod/). The full rules are in [`docs/contracts/tenant-policy.md`](https://github.com/Ygilany/AskDB/blob/main/docs/contracts/tenant-policy.md#guardrail-validation).
```ts
// askdb initialized at startup with createAskDb() — see Embed in a Node app.
import { bindPreparedQuery } from "@askdb/core";
const result = await askdb.ask(
"How many documents did we create this month?",
{
tenantScope: {
access: {
kind: "ids",
tenantRoot: "table:public.organizations",
ids: ["org_abc123"],
},
},
tenantSqlMode: "sql-params",
}
);
// Two executable pairs — pick one, never concatenate the arrays.
if (result.unboundSql && result.params) {
// Every value bound; params already includes the tenant IDs.
await pool.query(result.unboundSql, result.params);
} else {
// Business values inlined; tenant markers start at $1.
await pool.query(result.sql, result.tenantParams);
}
// Local rebind — no model call. Authorization of tenant IDs remains yours.
if (result.preparedQuery) {
const rebound = bindPreparedQuery(result.preparedQuery, {
":tenant_organization_ids": ["org_abc123"],
});
await pool.query(rebound.sql);
}
```
`access.kind` selects the scope shape: `ids` (exact tenant IDs on one root — the common case), `subtree` (a root’s IDs plus all descendants: `{ kind: "subtree", tenantRoot, rootIds, includeDescendants: true }`; needs a `resolveTenantDescendants` callback that returns IDs per root, see [below](#hierarchical-scope-subtree)), `multi_root` (IDs across several roots), or `global` (deliberately unscoped, with a `reason` string for the audit trail; the tenant check is skipped). The optional `context` field carries advisory metadata (role, department) into the prompt. It isn’t enforced.
Polymorphic tables are declared in the policy and surfaced to the model through the prompt; there’s no scope field for pre-resolving them at runtime.
## Hierarchical scope (`subtree`)
[Section titled “Hierarchical scope (subtree)”](#hierarchical-scope-subtree)
A `subtree` scope says “these IDs and everything beneath them”. An agency administrator, for example, sees their agency, its sub-agencies, and those sub-agencies’ clients. AskDB never opens a database connection, so it can’t walk your hierarchy itself. You pass a `resolveTenantDescendants` callback that returns the subtree’s IDs **grouped by tenant root**, and `ask()` binds each root’s IDs to that root’s own placeholder.
Grouping matters because each root table has its own ID space. If agency `1` owns sub-agency `5` and client `5`, those are not agency `5`, which may be another tenant. A single list would put `5` into `:tenant_agency_ids` and return the other tenant’s rows, so `ask()` rejects a flat array.
With the policy’s `agencies` → `sub_agencies` → `clients` hierarchy (declared through `roots[].parent` or `hierarchy`), return one entry per level, keyed by the root’s table ID:
```ts
import { ask } from "@askdb/core";
const result = await ask({
question: "how many appointments did my clients have this month?",
schema,
model,
dialect: "postgres",
tenantScope: {
access: {
kind: "subtree",
tenantRoot: "table:public.agencies",
rootIds: [currentUser.agencyId],
includeDescendants: true,
},
},
// Called once per ask() with the tenant root and the seed IDs.
resolveTenantDescendants: async (tenantRoot, seedIds) => {
if (tenantRoot !== "table:public.agencies") {
throw new Error(`no hierarchy resolver for ${tenantRoot}`);
}
const subAgencies = await pool.query(
"SELECT id::text AS id FROM sub_agencies WHERE agency_id = ANY($1)",
[seedIds],
);
const subAgencyIds = subAgencies.rows.map((r) => r.id);
const clients = await pool.query(
"SELECT id::text AS id FROM clients WHERE sub_agency_id = ANY($1)",
[subAgencyIds],
);
return {
"table:public.agencies": seedIds,
"table:public.sub_agencies": subAgencyIds,
"table:public.clients": clients.rows.map((r) => r.id),
};
},
});
// e.g. { agencies: ["1"], sub_agencies: ["5"], clients: ["5"] } becomes a multi_root scope:
// :tenant_agency_ids → '1', :tenant_sub_agency_ids → '5', :tenant_client_ids → '5'
// result.sql → ... JOIN clients c ON a.client_id = c.id WHERE c.id IN ('5')
```
If your agencies form a tree inside one table (`agencies.parent_agency_id`), the descendants are agencies too, so they go under the root’s own key. The policy can’t declare a same-table parent yet, so the root has no child roots and this is the only key:
```ts
resolveTenantDescendants: async (tenantRoot, seedIds) => {
const { rows } = await pool.query(
`WITH RECURSIVE tree AS (
SELECT id FROM agencies WHERE id = ANY($1)
UNION
SELECT a.id FROM agencies a JOIN tree t ON a.parent_agency_id = t.id
)
SELECT id::text AS id FROM tree`,
[seedIds],
);
return { [tenantRoot]: rows.map((r) => r.id) };
},
// result.sql → ... WHERE agency_id IN ('state-1', 'county-a', 'county-b')
```
The callback’s contract:
* **Return IDs per tenant root.** Allowed keys are the scope’s `tenantRoot` and every root the policy’s hierarchy reaches from it. Each value holds IDs of that root’s own `tenantIdColumn`: seeds and same-table descendants under `tenantRoot`, each child root’s IDs under that root.
* **`ask()` scopes the query per root.** The result becomes a `multi_root` scope (an `ids` scope when the subtree is `tenantRoot` alone), with one entry per covered root, including a root you return no IDs for. When your policy has more than one root, the prompt lists, under each placeholder (in both cases), the columns that hold that root’s IDs, and tells the model never to compare one root’s placeholder with another root’s column.
* **Seeds are always kept.** `ask()` unions `rootIds` into the `tenantRoot` entry, so returning only descendants doesn’t drop the ancestor’s own rows.
* **An empty level fails closed under `strict`.** A covered root you return no IDs for (missing key or `[]`) stays in the scope with no IDs. Under `enforcement: strict`, a query that reads that table must filter it with its own placeholder, so it can’t be reached through a parent’s key or a joined ancestor, and binding that placeholder throws `TenantScopeError` with reason `UNRESOLVED_TENANT_PLACEHOLDER`. So leaving a level out hides its rows. Under `warn`, a read through a parent’s key or an ancestor is returned with a warning in `result.tenantGuardrail`; only a read that uses the empty level’s own placeholder still fails at binding.
* **It fails closed.** If `resolveTenantDescendants` is missing, returns an array (the flat shape), returns something other than an object, uses a key that isn’t a root in the subtree, returns a value that isn’t an array of non-empty strings, or returns no IDs at all, `ask()` throws `TenantScopeError` with reason `SUBTREE_NOT_RESOLVABLE` before calling the model. It never falls back to the seed IDs alone.
* **Authorization and caching are yours.** AskDB checks which root each ID is filed under, not that it really is a descendant, so cache the closure or apply extra rules inside the callback.
In `strict` mode the tenant guardrail enforces the pairing. Each tenant column must be compared with its own root’s placeholder, so a model that filters a client column with `:tenant_agency_ids`, or the agency column with `:tenant_client_ids`, is rejected with `TenantGuardrailError`. Every root the expanded scope covers is also checked as a root table: a query that reads `clients` must filter it with `:tenant_client_ids`, not only through `clients.sub_agency_id` or a joined, filtered agency. The limits in [What the tenant check requires](#what-the-tenant-check-requires) still apply. Within one query block a predicate isn’t tied to a particular table reference, so a mispaired second reference next to a correctly filtered one can still pass: for example, a scalar subquery on `clients` compared with `:tenant_agency_ids` beside a read of `clients` filtered with `:tenant_client_ids`. A predicate inside a CTE or derived table can also satisfy the check for an unfiltered outer read of the same table ([#399](https://github.com/Ygilany/AskDB/issues/399)), and a join-path table can pass with a join on the wrong ID column ([#400](https://github.com/Ygilany/AskDB/issues/400)). Treat the check as defense in depth.
If one root’s hierarchy is already in memory (for example, a cached parent map of a same-table tree), `expandClosure(seedIds, childrenOf)` from `@askdb/core` does the walk for you. It is breadth-first and cycle-safe:
```ts
import { expandClosure } from "@askdb/core";
resolveTenantDescendants: (tenantRoot, seedIds) => ({
[tenantRoot]: expandClosure(seedIds, (id) => childrenByAgencyId.get(id) ?? []),
}),
```
`@askdb/client` forwards `resolveTenantDescendants` like any other per-call override: `askdb.ask(question, { tenantScope, resolveTenantDescendants })`.
## SQL output modes
[Section titled “SQL output modes”](#sql-output-modes)
| Mode | When to use |
| ------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `sql-only` | Tenant values inlined as escaped literals. Useful for development inspection or ad-hoc queries you read directly. |
| `sql-params` | Tenant values bound through your dialect’s driver markers — `$1` (Postgres, CockroachDB), `?` (MySQL, MariaDB, SQLite), `@p0` (SQL Server). Use this in production with parameterized execution. |
In `sql-params` mode `ask()` returns two executable pairs:
| Run | With | Notes |
| ------------------- | --------------------- | ------------------------------------------------------------------------------------------------------------------------------- |
| `result.sql` | `result.tenantParams` | Business values inlined as literals; tenant markers start at the first slot. |
| `result.unboundSql` | `result.params` | Present when `parameterize` is on (default). Every value is bound and `params` already includes the tenant IDs in marker order. |
Don’t concatenate `params` and `tenantParams`. `parameters[].indices` point into `params`.
AskDB only substitutes placeholders that sit in SQL code — placeholder text inside a string literal is left alone. If the generated SQL references a tenant root your scope has no IDs for, `ask()` throws (`UNRESOLVED_TENANT_PLACEHOLDER`) instead of returning SQL with a raw `:tenant_…` token. Placeholders are case-sensitive: `:TENANT_ORGANIZATION_IDS` isn’t substituted, so it throws the same error. With several IDs, `= :p` becomes `IN (…)` and `!= :p` becomes `NOT IN (…)`; a comparison like `<= :p` has no list form and throws `UNSUPPORTED_TENANT_PREDICATE`.
## What changes in the SQL
[Section titled “What changes in the SQL”](#what-changes-in-the-sql)
Without policy, a question like “how many documents this month?” might generate:
```sql
SELECT COUNT(*) FROM documents WHERE created_at >= NOW() - INTERVAL '1 month';
```
With the policy above and an access scope of `{ kind: "ids", tenantRoot: "table:public.organizations", ids: ["org_abc123"] }`, the model is prompted to write the tenant predicate with a placeholder, and AskDB binds your IDs into it. In `sql-params` mode the result looks like:
```sql
SELECT COUNT(*) FROM documents
WHERE organization_id = $1 AND created_at >= NOW() - INTERVAL '1 month';
```
The tenant predicate comes from the model, not from AskDB. AskDB checks the predicate’s shape and binds the values, but the check is heuristic, and a model steered by an unusual question can still write SQL that gets past it. That’s why the database should be the tenant boundary.
## Without a policy
[Section titled “Without a policy”](#without-a-policy)
If `tenant-policy.md` is absent from the schema artifact, AskDB generates SQL without any tenant-scoping predicates. That’s the right default for single-tenant deployments. Add the policy when (and only when) you go multi-tenant.
## Testing in Studio
[Section titled “Testing in Studio”](#testing-in-studio)
Studio’s **Ask** panel includes tenant scope controls — provide a scope as JSON before generating SQL to see how tenant placeholders are bound:
```json
{
"access": {
"kind": "ids",
"tenantRoot": "table:public.organizations",
"ids": ["org_abc123"]
}
}
```
Switch between `sql-only` and `sql-params` to compare the two output forms.
## Read next
[Section titled “Read next”](#read-next)
[**Run safely in production**How tenant scoping fits with read-only roles, timeouts, and audit logging.](/guides/run-safely-in-prod/)[**Safety boundaries**Everything AskDB validates in addition to tenant filters.](/concepts/safety-boundaries/)[**Author your schema**Use Studio’s Tenancy view to draft the policy.](/guides/author-your-schema/)
# RAG for large schemas
> When your schema is too big to fit in a prompt, index it with @askdb/rag and retrieve only the relevant chunks per question.
Scale-up guide
Big databases need retrieval. `@askdb/rag` chunks the same schema artifact and indexes it in a vector store. Per question, AskDB retrieves the relevant slice instead of stuffing the whole thing into every prompt.
## When you need it
[Section titled “When you need it”](#when-you-need-it)
A rule of thumb: if your schema artifact has more than \~30 tables, or if rendered DDL routinely exceeds 8K tokens, you’ll save money and improve generation quality by retrieving instead of stuffing.
The retrieval trigger is configurable. By default `ask()` uses retrieval when a retriever is supplied *and* the schema’s chunk count exceeds 30.
## Install
[Section titled “Install”](#install)
* npm
```bash
npm install @askdb/rag ai
```
* pnpm
```bash
pnpm add @askdb/rag ai
```
* yarn
```bash
yarn add @askdb/rag ai
```
For the pgvector store (recommended), add the Postgres driver:
* npm
```bash
npm install pg
```
* pnpm
```bash
pnpm add pg
```
* yarn
```bash
yarn add pg
```
You’ll also need an embedder. The Vercel AI SDK providers from [Bring your own model](/guides/bring-your-own-model/) work as embedders too — most teams use OpenAI’s embeddings.
## Set up pgvector
[Section titled “Set up pgvector”](#set-up-pgvector)
pgvector is the recommended store: it lives in Postgres alongside your other data, you already know how to back it up, and AskDB ships ready-made DDL.
There are three provisioning paths — pick the one that matches your deploy story.
### Path 1: Studio (local development)
[Section titled “Path 1: Studio (local development)”](#path-1-studio-local-development)
Studio creates the pgvector table the first time it builds the index. Configure the embedding model and the store in `askdb.config.ts`:
```ts
import { defineConfig, env } from "@askdb/config";
export default defineConfig({
ai: {
provider: "openai",
providerConfig: { openai: { apiKey: env("OPENAI_API_KEY") } },
embedding: { model: "text-embedding-3-small" },
},
rag: {
embedder: "ai",
store: "pgvector",
storeConfig: {
pgvector: {
databaseUrl: env("PGVECTOR_URL"),
},
},
},
// ...
});
```
`rag.embedder: "ai"` embeds with the [`ai.embedding`](/reference/config/#aiembedding) model, and `ai.embedding.model` is required: AskDB has no default embedding model. Its provider defaults to `ai.provider`; to keep a language model from a provider without embeddings (such as Anthropic), set `ai.embedding.provider` and give that provider a connection. You don’t set the vector width: AskDB learns it from the model when it first builds the index, and creates the pgvector table at that width. Set `ai.embedding.dimensions` only to request a smaller size from a model that lets you choose one.
Launch Studio (`npx askdb studio --schema ./my-app.schema`) and build the index from the **RAG Index** page; the first build creates the table.
### Path 2: `askdb-rag setup-store` (CI / staging)
[Section titled “Path 2: askdb-rag setup-store (CI / staging)”](#path-2-askdb-rag-setup-store-ci--staging)
One idempotent command. All DDL uses `IF NOT EXISTS` so it’s safe to re-run on every deploy. `setup-store` has no embedding model to ask, so pass the width yours returns (1536 for `text-embedding-3-small`; `detectEmbeddingDimensions(embedder)` tells you for any model).
```bash
askdb-rag setup-store \
--pg-url "$PGVECTOR_URL" \
--dimensions 1536
```
Pass `--dimensions` (or `--embedder openai`) to match your embedding model. Without either, the command uses the default `mock` embedder’s 64 dimensions. If the table already exists with different dimensions, the command fails instead of silently keeping the old size.
Drop it into a deploy step:
```yaml
- name: Provision pgvector schema
run: askdb-rag setup-store --pg-url "${{ secrets.PGVECTOR_URL }}" --dimensions 1536
```
### Path 3: Explicit migration (production)
[Section titled “Path 3: Explicit migration (production)”](#path-3-explicit-migration-production)
For production teams that want all DDL in a versioned migration file:
```ts
import { createPgvectorStore } from "@askdb/rag/stores/pgvector";
const store = createPgvectorStore({
connectionString: process.env.DATABASE_URL!,
dimensions: 1536, // your embedding model's width; detectEmbeddingDimensions(embedder) tells you
});
console.log(store.setupSql());
```
Paste the output (CREATE EXTENSION, CREATE TABLE, CREATE INDEX) into Flyway, Liquibase, Drizzle, or whatever migration runner your team uses.
## Index the schema artifact
[Section titled “Index the schema artifact”](#index-the-schema-artifact)
Index your schema’s chunks. If none of the paths above created the table yet, `ensureSchema()` creates it at the width the embedding model returns:
```ts
import {
buildSchemaIndex,
createAiSdkEmbedder,
createPgvectorStore,
detectEmbeddingDimensions,
loadChunkerSourcesFromDir,
} from "@askdb/rag";
import { openai } from "@ai-sdk/openai";
const embedder = createAiSdkEmbedder({
model: openai.textEmbeddingModel("text-embedding-3-small"),
});
const store = createPgvectorStore({
connectionString: process.env.PGVECTOR_URL!,
dimensions: await detectEmbeddingDimensions(embedder), // the width the model returns
});
await store.ensureSchema(); // creates the table if needed; refuses an existing table of another width
const { retriever, stats } = await buildSchemaIndex({
schema: loadChunkerSourcesFromDir("./my-app.schema"),
store,
embedder,
embedderId: "openai:text-embedding-3-small", // changes force a full re-embed
lockFilePath: "./my-app.schema/schema.lock.json", // records embedder, store, dimensions
});
```
`buildSchemaIndex` chunks the artifact and embeds only the chunks the store doesn’t already hold with the same content hash. It returns a ready-to-use `retriever` plus indexing stats. The lock file records the embedder id, store, and dimensions. If the embedder id changed, or the lock is missing, every chunk is re-embedded; a different store gets the chunks it doesn’t already hold. Pass `force: true` to re-embed unconditionally.
## Wire retrieval into `ask()`
[Section titled “Wire retrieval into ask()”](#wire-retrieval-into-ask)
Pass the retriever to `ask()`. AskDB calls it with the question and substitutes the retrieved chunks for the full DDL in the prompt.
If you just ran `buildSchemaIndex` in the same process, pass its returned `retriever` directly. To retrieve in a separate process (the common production shape), rebuild one from the store:
```ts
import { createAskDb } from "@askdb/client";
import { createRetriever } from "@askdb/rag";
// askdb initialized at startup — see Embed in a Node app.
const retriever = createRetriever({ store, embedder });
const { sql } = await askdb.ask(question, {
retriever,
retrievalThresholdChunks: 30, // default
});
```
## Sensitive fields and embeddings
[Section titled “Sensitive fields and embeddings”](#sensitive-fields-and-embeddings)
Sensitive content stays out of the index by default. The chunker drops the describable layer (descriptions, aliases, primary entity, enum values, notes, common query language, example questions, business context) for sensitive tables and columns. It also drops any describable text that mentions a sensitive column by name (whole word, case-insensitive), wherever the text would appear, including the aliases and primary entity repeated in common query language and example question headings. Text that belongs to a table is checked against the sensitive columns of that same table. Concepts and tenant policy sections are checked against every sensitive column in the schema, so a concept that says “filter by SSN” is not embedded when any table’s `ssn` column is sensitive. Column identifiers and types stay available to the model through `ask()`’s prompt.
Set `chunkOptions: { includeSensitiveDescribable: true }` only if your trust model allows embedding that content. Chunks kept this way carry `sensitive: true`. See the [schema-v2 contract on GitHub](https://github.com/Ygilany/AskDB/blob/main/docs/contracts/schema-v2.md#sensitive-propagation) for the full rules.
## Custom table or dimensions
[Section titled “Custom table or dimensions”](#custom-table-or-dimensions)
Several schemas can share one table: chunk ids are scoped by schema id (`chunk::…`, with `%` and `:` in the schema id percent-encoded), and reindexing one schema never removes another schema’s chunks. Use a separate table when deployments use different embedding models or dimensions. To isolate multiple AskDB deployments in the same Postgres database, pass a custom table name and a matching embedding dimension:
```bash
askdb-rag setup-store \
--pg-url "$DATABASE_URL" \
--pg-table myapp_rag_chunks \
--dimensions 1536
```
Match the same `table` value in `askdb.config.ts` under `rag.storeConfig.pgvector.table`.
## Read next
[Section titled “Read next”](#read-next)
[**Author your schema**Enrichment dramatically improves retrieval quality.](/guides/author-your-schema/)[**Bring your own model**Embedder options and key management.](/guides/bring-your-own-model/)[**Package reference**The full @askdb/rag API surface.](/reference/packages/)
# Run safely in production
> The operator checklist for AskDB: read-only roles, statement timeouts, row limits, audit logging, and approval flows.
Production checklist
AskDB runs heuristic checks on SQL before it’s returned. Those checks catch common model mistakes, but they aren’t a security boundary. Your application and database own everything that depends on runtime context. This page is the checklist for that side of the boundary. For what AskDB does and doesn’t check, see [Safety boundaries](/concepts/safety-boundaries/).
## Database role
[Section titled “Database role”](#database-role)
Connect under a role that *can’t* write — even if AskDB’s validator slips. This is the single most important defense.
```sql
CREATE ROLE askdb_reader LOGIN PASSWORD '…';
GRANT CONNECT ON DATABASE myapp TO askdb_reader;
GRANT USAGE ON SCHEMA public TO askdb_reader;
-- Grant only the tables AskDB is meant to query. Leave sensitive tables out.
GRANT SELECT ON public.orders, public.customers TO askdb_reader;
-- Start every transaction this role opens as read-only.
ALTER ROLE askdb_reader SET default_transaction_read_only = on;
```
Table grants alone don’t make a Postgres role read-only. Every role can still call some built-in functions that write, for example `lo_from_bytea`, which creates a large object. AskDB’s function denylist blocks the known ones, but this role exists for SQL that gets past those checks. With `default_transaction_read_only` on, such a call fails with `cannot execute lo_from_bytea() in a read-only transaction`. The setting applies to new sessions of that role, and a session can change its own default, so also run each generated query inside a read-only transaction (`BEGIN READ ONLY` … `ROLLBACK` on Postgres, `START TRANSACTION READ ONLY` on MySQL).
Use that role’s credentials in the connection string AskDB’s consumers use. Don’t reuse your application’s admin user.
### System catalogs
[Section titled “System catalogs”](#system-catalogs)
On Postgres you can’t take catalog read access away from a single role. `pg_catalog` and `information_schema` are readable through `PUBLIC`, which every role belongs to, so a `REVOKE … FROM askdb_reader` on them has no effect. Through the catalogs, `askdb_reader` can see the names and columns of every table in the database, view definitions, and function source code. It still can’t read rows from a table it has no `SELECT` on.
If that metadata matters, pick one of these:
* **Accept catalog visibility.** Most deployments do. Keep the data itself out of reach with the table and column grants above, which the catalogs don’t bypass.
* **Use a dedicated database.** Catalogs such as `pg_class` describe only the objects in the current database, so a database (for example a reporting copy) that holds only the tables AskDB may query shows only those tables. Cluster-wide catalogs such as `pg_roles` and `pg_database` still list every role and database.
* **Revoke from `PUBLIC`.** `REVOKE SELECT ON pg_catalog.pg_class, pg_catalog.pg_proc FROM PUBLIC;` blocks direct reads of those catalogs, but for every role in that database: your application, `psql`’s `\d`, and the role AskDB’s introspection runs as lose them too, so grant them back to the roles that need them. It also doesn’t hide everything: views such as `pg_tables`, casts such as `'public.secrets'::regclass`, and functions such as `pg_get_functiondef` still return catalog data. Test it against your own tooling before you rely on it.
## Connection limits
[Section titled “Connection limits”](#connection-limits)
Set a statement timeout and a small pool. Generated SQL should be fast — a slow query is usually a sign of a malformed question or a missing index, not a real long-running report.
```ts
import { Pool } from "pg";
const pool = new Pool({
connectionString: process.env.DATABASE_URL,
max: 10,
statement_timeout: 5000, // 5s — adjust to your workload
idle_in_transaction_session_timeout: 5000,
});
```
## Row limits
[Section titled “Row limits”](#row-limits)
Wrap generated SQL with a hard row cap before execution. This protects against questions like “show me every row in this 100M-row table” that are valid SQL but useless to render.
```ts
// askdb initialized at startup with createAskDb() — see Embed in a Node app.
const { sql } = await askdb.ask(question);
const cappedSql = `SELECT * FROM (${sql}) AS askdb_q LIMIT 1000`;
```
## Audit logging
[Section titled “Audit logging”](#audit-logging)
Log every question, every generated SQL string, the user who asked, and the outcome. Keep it in your existing logging system — AskDB doesn’t log on your behalf.
```ts
import { logger } from "./logger.js";
// askdb initialized at startup with createAskDb() — see Embed in a Node app.
const correlationId = crypto.randomUUID();
logger.info({ correlationId, userId, question }, "askdb.question");
try {
const { sql } = await askdb.ask(question);
logger.info({ correlationId, sql }, "askdb.generated");
const rows = await pool.query(sql);
logger.info({ correlationId, rowCount: rows.rowCount }, "askdb.executed");
return rows;
} catch (error) {
logger.error({ correlationId, error }, "askdb.error");
throw error;
}
```
The optional structured logger in `@askdb/core` (`createAskDbLogger`) emits standard events you can wire into Pino.
## Approval flows
[Section titled “Approval flows”](#approval-flows)
For high-stakes questions — anything that touches sensitive data, or that runs against production reporting databases — show the SQL to a human before executing.
A common pattern:
1. Call `ask()` and return `{ sql }` (no execution).
2. Render the SQL in the UI with the question for context.
3. On user confirmation, POST the SQL back to a separate execution endpoint that runs it under the read-only role.
This works because AskDB returns checked SQL as a value — your application controls when, if, and how it runs.
## Sensitive columns
[Section titled “Sensitive columns”](#sensitive-columns)
Mark sensitive columns in the schema artifact, either in Studio’s Sensitivity tab or directly in the table’s markdown front-matter:
```yaml
columns:
- id: table:public.users#email
sensitive: true
```
Front-matter sensitivity is escalate-only. It can mark a column sensitive (or a whole table, with a table-level `sensitive: true`) on top of `schema.json`, but `sensitive: false` never un-marks something `schema.json` marks sensitive.
Then choose the prompt-construction behavior per deployment:
* **Default** — sensitive columns appear in the prompt with a sensitivity tag. The model knows to be cautious.
* **Strict** — set `modes.omitSensitiveFromPrompt: true` in `askdb.config.ts` (or pass `--omit-sensitive-from-prompt`) to omit sensitive columns from the prompt entirely. The model can’t propose them because it doesn’t know they exist.
See [Privacy model](/concepts/privacy-model/) for what crosses the boundary in each mode.
## Multi-tenancy
[Section titled “Multi-tenancy”](#multi-tenancy)
If your app is multi-tenant, declare tenant policy in the schema artifact and pass a `tenantScope` to every `ask()` call. AskDB prompts the model to filter by tenant, binds your tenant IDs, and runs a heuristic check that each scoped table has a tenant predicate that filters. That check doesn’t prove the query is scoped correctly, so enforce tenant isolation in the database too, for example with Postgres row-level security keyed on a per-request setting. See [Multi-tenancy](/guides/multi-tenancy/).
## Read next
[Section titled “Read next”](#read-next)
[**Safety boundaries**What AskDB checks before SQL is returned, and what it doesn’t.](/concepts/safety-boundaries/)[**Privacy model**What crosses the boundary to the model.](/concepts/privacy-model/)[**Multi-tenancy**Scoping every query to a tenant.](/guides/multi-tenancy/)
# Switch engines
> All four engines — Postgres, MySQL, SQLite, SQL Server — are first-class. Here's what changes when you move between them and what doesn't.
Engine migration
Most of AskDB is engine-agnostic. The dialect adapter is the part that knows your SQL flavor — swap it, and the same schema-author workflow and the same `ask()` call work against a different engine.
## What stays the same
[Section titled “What stays the same”](#what-stays-the-same)
* The schema artifact format. Same `schema.json`, same `tables/*.md`, same enrichment workflow.
* The `ask()` API. Same options, same return shape.
* The SQL checks: must start with `SELECT` or `WITH`, single statement (with a SQL Server caveat), no comments, no write or DDL keywords, no calls to known side-effecting functions, and the heuristic tenant and sensitive-column checks. Per engine, only the detail changes: SQL is split into tokens the way that engine reads strings, quoted identifiers, and comments, and each engine adds its own entries to the keyword denylist, the function denylist, or both. See [Safety boundaries](/concepts/safety-boundaries/).
* The privacy model. The model sees schema, not rows, regardless of engine.
## What changes
[Section titled “What changes”](#what-changes)
* The engine package you install.
* The `dialect` value you pass to `ask()`.
* Engine-specific SQL features the validator allows (LIMIT vs TOP, parameter syntax, JSON path syntax).
* The driver your app uses to execute (`pg`, `mysql2`, `better-sqlite3`, `mssql`).
* How the CLI introspects the database (connection-string format and catalog queries differ per engine).
## The matrix
[Section titled “The matrix”](#the-matrix)
| Engine | Adapter package | `dialect` value | Suggested driver |
| ---------- | ------------------ | --------------- | ---------------- |
| PostgreSQL | `@askdb/postgres` | `"postgres"` | `pg` |
| MySQL | `@askdb/mysql` | `"mysql"` | `mysql2` |
| SQLite | `@askdb/sqlite` | `"sqlite"` | `better-sqlite3` |
| SQL Server | `@askdb/sqlserver` | `"sqlserver"` | `mssql` |
## Step by step
[Section titled “Step by step”](#step-by-step)
### 1. Install the new adapter
[Section titled “1. Install the new adapter”](#1-install-the-new-adapter)
* PostgreSQL
* npm
```bash
npm install @askdb/postgres ai
```
* pnpm
```bash
pnpm add @askdb/postgres ai
```
* yarn
```bash
yarn add @askdb/postgres ai
```
If you plan to run live introspection, also add the driver:
* npm
```bash
npm install pg
```
* pnpm
```bash
pnpm add pg
```
* yarn
```bash
yarn add pg
```
* MySQL
```bash
npm install @askdb/postgres ai
```
* SQLite
```bash
pnpm add @askdb/postgres ai
```
* SQL Server
```bash
yarn add @askdb/postgres ai
```
* npm
```bash
npm install pg
```
* pnpm
```bash
pnpm add pg
```
* yarn
```bash
yarn add pg
```
* npm
* npm
```bash
npm install @askdb/mysql ai
```
* pnpm
```bash
pnpm add @askdb/mysql ai
```
* yarn
```bash
yarn add @askdb/mysql ai
```
If you plan to run live introspection, also add the driver:
* npm
```bash
npm install mysql2
```
* pnpm
```bash
pnpm add mysql2
```
* yarn
```bash
yarn add mysql2
```
* pnpm
```bash
npm install @askdb/mysql ai
```
* yarn
```bash
pnpm add @askdb/mysql ai
```
* npm
```bash
yarn add @askdb/mysql ai
```
* pnpm
```bash
npm install mysql2
```
* yarn
```bash
pnpm add mysql2
```
* npm
```bash
yarn add mysql2
```
* pnpm
* npm
```bash
npm install @askdb/sqlite ai
```
* pnpm
```bash
pnpm add @askdb/sqlite ai
```
* yarn
```bash
yarn add @askdb/sqlite ai
```
If you plan to run live introspection, also add the driver:
* npm
```bash
npm install better-sqlite3
```
* pnpm
```bash
pnpm add better-sqlite3
```
* yarn
```bash
yarn add better-sqlite3
```
* yarn
```bash
npm install @askdb/sqlite ai
```
* npm
```bash
pnpm add @askdb/sqlite ai
```
* pnpm
```bash
yarn add @askdb/sqlite ai
```
* yarn
```bash
npm install better-sqlite3
```
* npm
```bash
pnpm add better-sqlite3
```
* pnpm
```bash
yarn add better-sqlite3
```
* yarn
* npm
```bash
npm install @askdb/sqlserver ai
```
* pnpm
```bash
pnpm add @askdb/sqlserver ai
```
* yarn
```bash
yarn add @askdb/sqlserver ai
```
If you plan to run live introspection, also add the driver:
* npm
```bash
npm install mssql
```
* pnpm
```bash
pnpm add mssql
```
* yarn
```bash
yarn add mssql
```
* npm
```bash
npm install @askdb/sqlserver ai
```
* pnpm
```bash
pnpm add @askdb/sqlserver ai
```
* yarn
```bash
yarn add @askdb/sqlserver ai
```
* npm
```bash
npm install mssql
```
* pnpm
```bash
pnpm add mssql
```
* yarn
```bash
yarn add mssql
```
You can keep the old adapter installed during a transition. Each adapter is self-contained. Database drivers are optional peers used only by live introspection or by your own execution layer.
### 2. Introspect the new database (if the schema differs)
[Section titled “2. Introspect the new database (if the schema differs)”](#2-introspect-the-new-database-if-the-schema-differs)
If you are pointing at a different database instance — one that may have a different set of tables or columns — run introspection against it to regenerate the physical layer of the schema artifact:
* PostgreSQL
```bash
npx askdb introspect \
--engine postgres \
--url "postgresql://user:pass@host/dbname" \
--out my-app.schema \
--schema-id my-app
```
* MySQL
```bash
npx askdb introspect \
--engine mysql \
--url "mysql://user:pass@host/dbname" \
--out my-app.schema \
--schema-id my-app
```
For MySQL and MariaDB, the URL’s database is the one introspected, and its tables appear under the `public` namespace. `public` is AskDB’s label, not a database, so the prompt `ask()` sends lists those tables unqualified (`orders`). To introspect several databases at once (MySQL’s “schemas”), list them. Each database becomes its own namespace (`sales.orders`), listed qualified in the prompt, and foreign keys between databases are kept:
askdb.config.ts
```ts
export default {
introspection: {
provider: "mysql",
providerConfig: {
mysql: { databaseUrl: env("DATABASE_URL") },
},
schemas: ["app", "sales", "analytics"],
},
// ...
};
```
* SQLite
For SQLite, set the file path via `introspection.providerConfig.sqlite.file` in `askdb.config.ts`:
askdb.config.ts
```ts
export default {
introspection: {
provider: "sqlite",
providerConfig: {
sqlite: { file: "./my-database.db" },
},
},
// ...
};
```
Then run:
```bash
npx askdb introspect --out my-app.schema --schema-id my-app
```
SQLite has no schemas, so its tables appear under the `public` namespace (table ids like `table:public.orders`), and the prompt `ask()` sends lists them unqualified (`orders`).
* SQL Server
```bash
npx askdb introspect \
--engine sqlserver \
--url "mssql://user:pass@host:1433/dbname" \
--out my-app.schema \
--schema-id my-app
```
SQL Server accepts three URL formats — see [SQL Server connection strings](#sql-server-connection-strings) below.
`introspection.schemas` works the same way on every engine: on Postgres and SQL Server it lists schemas (the default is every non-system schema). `askdb introspect --schemas app,sales` does the same for one run and overrides the configured list.
The connection string format follows each engine’s convention. The engine itself comes from `--engine` (or `introspection.provider` in `askdb.config.ts`) — the CLI does not infer it from the URL. The artifact records which engine produced it, and `askdb ask` infers the dialect from the artifact.
For one-off live introspection without installing `askdb` in the project, include the driver in the same ephemeral command:
```bash
pnpm dlx -p askdb -p mysql2 askdb introspect --engine mysql --url "$MYSQL_URL"
npx -p askdb -p mssql askdb introspect --engine sqlserver --url "$SQLSERVER_URL"
```
If the logical schema is identical and you are only swapping the adapter package, the existing artifact is already valid — skip this step and go straight to step 3.
### 3. Update the `dialect` value in `ask()` calls
[Section titled “3. Update the dialect value in ask() calls”](#3-update-the-dialect-value-in-ask-calls)
The schema artifact records which engine it was introspected from. The CLI (`askdb ask`) and `askdb.config.ts` use that information to infer the dialect automatically — no manual update needed for those entry points.
This holds for Prisma-introspected artifacts too: the connector reads the `datasource.provider` from your `.prisma` file (`postgresql` → `postgres`, `mysql`, `sqlite`, `sqlserver`) and records it, so `askdb ask` still knows the dialect without a live database.
When using `@askdb/client`, the dialect resolves from the schema artifact’s recorded provider automatically — the same inference the CLI uses. No code change needed after a dialect switch if the new artifact declares the correct provider.
To force a specific dialect (for example, if the artifact’s provider doesn’t match your target engine), pass it as a per-call override:
```ts
// askdb initialized at startup with createAskDb() — see Embed in a Node app.
const { sql } = await askdb.ask(question, {
dialect: "mysql", // overrides auto-resolution
});
```
All four dialect specs ship inside `@askdb/core`. The engine packages (`@askdb/mysql`, `@askdb/postgres`, …) supply the *introspection* connector for that engine (and re-export its dialect constant for convenience); you need them to introspect, not to generate.
### 4. Update your driver
[Section titled “4. Update your driver”](#4-update-your-driver)
Swap the driver library for the one that matches the new engine. The execution layer is yours — AskDB doesn’t open the connection — so this is a straight library swap.
* PostgreSQL
```ts
import { Pool } from "pg";
const pool = new Pool({
connectionString: process.env.DATABASE_URL,
statement_timeout: 5000,
max: 10,
});
const { rows } = await pool.query(sql);
```
* MySQL
```ts
import mysql from "mysql2/promise";
const pool = mysql.createPool({
uri: process.env.MYSQL_URL,
connectionLimit: 10,
});
const [rows] = await pool.execute(sql);
```
* SQLite
```ts
import Database from "better-sqlite3";
const db = new Database(process.env.SQLITE_FILE ?? "./my-database.db");
const rows = db.prepare(sql).all();
```
* SQL Server
```ts
import mssql from "mssql";
const pool = await mssql.connect(process.env.SQLSERVER_URL);
const result = await pool.request().query(sql);
const rows = result.recordset;
```
## SQL Server connection strings
[Section titled “SQL Server connection strings”](#sql-server-connection-strings)
`databaseUrl` in `askdb.config.ts` and `--url` on the CLI accept three formats:
| Format | Example |
| ---------------------- | ---------------------------------------------------------------- |
| `mssql://` URL | `mssql://sa:pass@localhost:1433/MyDb` |
| Prisma `sqlserver://` | `sqlserver://localhost:1433;database=MyDb;user=sa;password=pass` |
| ADO.NET (`Key=Value;`) | `Server=localhost,1433;Database=MyDb;User Id=sa;Password=pass;` |
### TLS / self-signed certificates
[Section titled “TLS / self-signed certificates”](#tls--self-signed-certificates)
SQL Server enables TLS by default. Local or dev instances typically use a self-signed certificate, which causes this error:
```plaintext
self-signed certificate — try running Node.js with --use-system-ca
```
**Fix for development:** add the trust option for your format:
```bash
# mssql:// URL
mssql://sa:pass@localhost:1433/MyDb?trustServerCertificate=true
# Prisma URL
sqlserver://localhost:1433;database=MyDb;user=sa;password=pass;trustServerCertificate=true
# ADO.NET — use the camelCase key without spaces
Server=localhost,1433;Database=MyDb;User Id=sa;Password=pass;Encrypt=True;TrustServerCertificate=True;
```
> **Note:** If you copy a connection string from VS Code’s mssql extension it will contain `Trust Server Certificate=True` (with spaces). AskDB normalises this automatically so it works, but you can also write it without spaces (`TrustServerCertificate=True`) to match what mssql v12 expects natively.
**Fix for production:** install a properly signed certificate or install the server’s CA certificate in the Node.js trust store:
```bash
NODE_EXTRA_CA_CERTS=/path/to/ca.pem npx askdb introspect
# or (Node ≥ 24.3)
node --use-system-ca $(which askdb) introspect
```
## On dialect parity
[Section titled “On dialect parity”](#on-dialect-parity)
Postgres is the reference dialect — features ship there first and the other engines follow. For most analytical questions, the four dialects generate equivalent SQL; for engine-specific features (JSON operators, window function syntax, regex variations), behavior follows what each engine supports natively.
If you hit a dialect difference that surprises you, that’s a bug — file it on [the project issues](https://github.com/Ygilany/AskDB/issues).
## Running multiple engines side by side
[Section titled “Running multiple engines side by side”](#running-multiple-engines-side-by-side)
Nothing stops you from querying two schema artifacts against different dialects in the same process. With `@askdb/client`, pass the schema and dialect as per-call overrides:
```ts
// askdb initialized at startup with createAskDb() — see Embed in a Node app.
const fromOrders = await askdb.ask(question, {
schema: { path: "./orders.schema" },
dialect: "postgres",
});
const fromAnalytics = await askdb.ask(question, {
schema: { path: "./analytics.schema" },
dialect: "mysql",
});
```
## Read next
[Section titled “Read next”](#read-next)
[**Modes and dialects**The conceptual model behind dialect adapters.](/concepts/modes-and-dialects/)[**Embed in a Node app**The base integration that the engine swap modifies.](/guides/embed-in-node/)[**Package reference**The full per-engine package surface.](/reference/packages/)
# Install
> Choose the AskDB packages for your use case.
Start · Install
AskDB is a set of focused packages — install only what your use case needs. Pick your path below; each guide starts with the exact install commands, and the [package reference](/reference/packages/) covers every package individually.
## What to install — by use case
[Section titled “What to install — by use case”](#what-to-install--by-use-case)
[**Just trying it out**`askdb` alone is enough to introspect, enrich, and ask from the CLI.](/quickstart/)[**Embedding in a Node service**`@askdb/client` + `@askdb/core` + `@askdb/config` + `ai` + an AI SDK provider package such as `@ai-sdk/openai`.](/guides/embed-in-node/)[**Standing up an HTTP service**Add `@askdb/http-api` on top of the embedding install.](/guides/deploy-as-http-service/)[**Working with a large schema**Add `@askdb/rag` and a vector store (pgvector recommended).](/guides/rag-for-large-schemas/)
# Quickstart
> Scaffold config, introspect a database, enrich the schema, and ask your first question — in under five minutes.
From zero to first query
Scaffold your config, point AskDB at your database, enrich the schema artifact, and ask your first question. The same packages drop straight into a Node service when you’re ready to embed.
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
* Node 22.14 or newer.
* npm, pnpm, or yarn — tabbed examples adapt to your choice; standalone snippets use `npx` (substitute `pnpm dlx` or `yarn dlx`).
* An API key from a model provider — OpenAI, Anthropic, Google, Azure, or any OpenAI-compatible endpoint (OpenRouter, vLLM, Ollama, …). See [Bring your own model](/guides/bring-your-own-model/).
* A database AskDB can read — Postgres, MySQL, SQLite, or SQL Server — or even a Prisma schema file (no live database required).
## The whole flow, in four commands
[Section titled “The whole flow, in four commands”](#the-whole-flow-in-four-commands)
* npm
```bash
npx askdb@latest init # scaffold askdb.config.ts
npx askdb introspect # read your database into a schema artifact
npx askdb studio # enrich the schema and test questions in your browser
npx askdb ask --question "Which customers signed up last week?"
```
* pnpm
```bash
pnpm dlx askdb@latest init # scaffold askdb.config.ts
pnpm dlx askdb introspect # read your database into a schema artifact
pnpm dlx askdb studio # enrich the schema and test questions in your browser
pnpm dlx askdb ask --question "Which customers signed up last week?"
```
* yarn
```bash
yarn dlx askdb@latest init # scaffold askdb.config.ts
yarn dlx askdb introspect # read your database into a schema artifact
yarn dlx askdb studio # enrich the schema and test questions in your browser
yarn dlx askdb ask --question "Which customers signed up last week?"
```
Each step is explained below. The loop that makes answers good: **introspect once, then enrich and re-ask in Studio until the SQL matches how your team thinks about the data.**
## 1. Scaffold your config
[Section titled “1. Scaffold your config”](#1-scaffold-your-config)
```bash
npx askdb@latest init
```
`npx` (like `pnpm dlx` and `yarn dlx`) downloads and runs `askdb` on the fly — no separate install step needed. In a terminal, `askdb init` opens a short wizard that asks which database you use, which AI provider you have a key for, and whether you want the Studio query playground. It then writes only the relevant config branches and installs only the packages your setup needs.
In CI or scripts, skip the wizard:
```bash
npx askdb@latest init --yes # Postgres + OpenAI defaults
npx askdb@latest init --yes --database sqlserver # SQL Server instead
npx askdb@latest init --yes --database sqlite --sqlite-file SQLITE_FILE
```
Tip
`askdb.config.ts` is checked in; `.env` (your real keys) is not.
Note
Prefer the browser? Skip `init` and run `npx askdb studio` directly — with no config present, Studio opens a [guided setup wizard](/studio/#guided-setup) that writes the config and runs introspection for you.
The generated config is tailored to what you chose — for example, a SQL Server setup:
```ts
import { defineConfig, env, type AskDbConfig } from "@askdb/config";
export default defineConfig({
ai: {
provider: "openai",
providerConfig: { openai: { apiKey: env("OPENAI_API_KEY") } },
language: { model: env("OPENAI_MODEL") },
},
introspection: {
provider: "sqlserver",
providerConfig: { sqlserver: { databaseUrl: env("SQLSERVER_URL") } },
outputDir: "./askdb",
},
rag: { embedder: "mock", store: "file", storeConfig: { file: {} } },
} satisfies AskDbConfig);
```
See the [Configuration reference](/reference/config/) for every option. See [CLI reference — askdb init](/reference/cli/#askdb-init) for all flags.
Once this is configured, most CLI flags below are optional.
## 2. Introspect your database
[Section titled “2. Introspect your database”](#2-introspect-your-database)
Introspection produces an **AskDB schema artifact** — a directory on disk that captures your tables, columns, types, and relationships. That artifact is the only thing the model ever sees about your database.
* Live database
With your database connection configured in `askdb.config.ts` under `introspection.provider` and `introspection.providerConfig`, one command is enough:
```bash
npx askdb introspect
```
For example, for Postgres:
```ts
introspection: {
provider: "postgres",
providerConfig: {
postgres: { databaseUrl: env("DATABASE_URL") }, // env name is yours to pick
},
},
```
The database is only used here — for introspection. To target a different database for one run, pass `--url`:
```bash
npx askdb introspect --url "$OTHER_DATABASE_URL"
```
The engine comes from `introspection.provider` in your config (or the `--engine` flag); the introspected artifact records it, and `askdb ask` later infers the SQL dialect from the artifact. The complete config surface is documented in the [Configuration reference](/reference/config/). For engine-specific install steps see [Switch engines](/guides/switch-engines/).
* Prisma schema file
With your Prisma schema configured in `askdb.config.ts` under `introspection.provider` and `introspection.providerConfig`, one command is enough — no live database required:
```bash
npx askdb introspect
```
For example:
```ts
introspection: {
provider: "prisma",
providerConfig: {
prisma: { schemaPath: "./prisma/schema.prisma" },
},
},
```
To introspect a different schema file for one run, pass the flags instead:
```bash
npx askdb introspect --engine prisma --prisma-schema ./other/schema.prisma
```
## 3. Enrich and test in Studio
[Section titled “3. Enrich and test in Studio”](#3-enrich-and-test-in-studio)
Raw introspection captures structure. Enrichment adds descriptions, aliases, business concepts, sensitive markers, and example questions — the layer that makes generation good.
Launch **Studio** — the recommended authoring surface — in a browser:
```bash
npx askdb studio
```
Studio is also the best place to **test your questions**: ask a question in the same session, review the generated SQL, and keep enriching if the answer isn’t what you expected — all without switching tools. See the [Studio tour](/studio/) for what each view does.
Studio reads `outputDir` from `askdb.config.ts`, so no flags are needed. The full walkthrough lives in [Author your schema](/guides/author-your-schema/).
## 4. Ask your question
[Section titled “4. Ask your question”](#4-ask-your-question)
You have two ways to test that your schema is generating good SQL — pick whichever fits the moment.
### In Studio (recommended)
[Section titled “In Studio (recommended)”](#in-studio-recommended)
If Studio is already open from step 3, ask your question there. You’ll see the generated SQL alongside the schema; if the answer isn’t right, keep enriching descriptions, aliases, or concepts and re-ask in the same session.
Asking in Studio isn’t the destination — it’s how you dial in the enrichment until the SQL satisfies what your users actually need. Once you’re happy with the answers, you embed the **same** schema artifact into your own app or service (see step 5) — Studio was just the place you tuned it.
### From the CLI
[Section titled “From the CLI”](#from-the-cli)
For one-off checks and CI smoke tests, ask directly from the terminal:
```bash
npx askdb ask --question "Which customers signed up last week?"
```
You get checked SQL on stdout — for example:
```sql
SELECT c.id, c.name, c.signed_up_at
FROM customers AS c
WHERE c.signed_up_at >= NOW() - INTERVAL '7 days'
ORDER BY c.signed_up_at DESC;
```
In both cases AskDB returns checked SQL. It does **not** run it against your database — your application owns execution.
Caution
AskDB’s SQL checks are heuristic guardrails, not a security boundary. Before your application runs generated SQL, read [Run generated SQL safely](/concepts/safety-boundaries/#run-generated-sql-safely): use a read-only, least-privilege database role, set timeouts, and enforce tenant isolation in the database.
## 5. From here
[Section titled “5. From here”](#5-from-here)
Now that the CLI works, pick the path that matches what you’re building:
[**Embed in a Node app**Drop `@askdb/client` into a TypeScript service and run the SQL through your own pool.](/guides/embed-in-node/)[**Deploy as HTTP service**Stand up `@askdb/http-api` so Python, browsers, or agents can ask questions.](/guides/deploy-as-http-service/)[**Author your schema**Get the most out of Studio: descriptions, concepts, sensitive markers, tenant policy.](/guides/author-your-schema/)[**How AskDB works**The end-to-end flow, with all the moving parts.](/concepts/how-askdb-works/)
Want to skip the steps above and explore a runnable script? The [examples/ask-question](https://github.com/Ygilany/AskDB/tree/main/examples/ask-question) package in the repo shows the same `createAskDb` and direct `ask()` patterns against a live schema.
# ask() options
> Moved — the full ask() options and result reference lives in the @askdb/core API reference.
Reference · Core API
This page has a new home: the complete `ask()` options, result fields, dialects, modes, and tenant types are documented in the [@askdb/core API reference](/reference/core-api/).
## Where to look
[Section titled “Where to look”](#where-to-look)
[**@askdb/core API**Every `ask()` option and the full `AskPipelineResult`.](/reference/core-api/)[**@askdb/client API**`createAskDb()` and per-call overrides — the config-driven path.](/reference/client-api/)[**Embed in a Node app**The end-to-end walkthrough using these APIs.](/guides/embed-in-node/)
# CLI reference
> Every askdb command and flag — init, introspect, enrich, studio, bundle, ask.
Reference · CLI
The `askdb` binary covers the full local workflow: scaffolding a project, introspecting a database, authoring schema artifacts, and asking questions. All commands use the same `@askdb/core` pipeline as the library.
## Install
[Section titled “Install”](#install)
* npm
```bash
npm install askdb
npx askdb --help
```
* pnpm
```bash
pnpm add askdb
pnpm exec askdb --help
```
* yarn
```bash
yarn add askdb
yarn askdb --help
```
For global install:
* npm
```bash
npm install -g askdb
askdb --help
```
* pnpm
```bash
pnpm add -g askdb
askdb --help
```
* yarn
```bash
yarn global add askdb
askdb --help
```
## Help, version, and first run
[Section titled “Help, version, and first run”](#help-version-and-first-run)
| Flag | Description |
| --------------- | ------------------------------------------------------------------------------------------------------------------------------- |
| `-h, --help` | Print usage. `init`, `ask`, `introspect`, and `studio` also take `--help` for their own flags (for example `askdb ask --help`). |
| `-V, --version` | Print the installed `askdb` version. |
Commands that don’t read the config work in any directory, including one with no `askdb.config.*`: `--help`, `--version`, `help`, `init`, `bundle`, `introspect --help`, `introspect templates`, and [`studio`](#askdb-studio).
`ask` and `introspect` need `askdb.config.*` (or `.config/askdb.*`) in the current directory. Without one they print ``No askdb.config.* or .config/askdb.* found in . Run `npx askdb init` to create one.`` and exit `1`.
## Commands
[Section titled “Commands”](#commands)
### `askdb init`
[Section titled “askdb init”](#askdb-init)
Scaffolds a tailored `askdb.config.ts` and installs only the packages your setup needs. In a TTY it opens a short wizard; in CI or with `--yes` it runs silently.
```bash
npx askdb@latest init # wizard in a terminal
npx askdb@latest init --yes # non-interactive, Postgres + OpenAI defaults
```
**General flags**
| Flag | Description |
| ------------------ | ------------------------------------------------------- |
| `-y, --yes` | Accept defaults without prompts. |
| `--interactive` | Force wizard mode; errors if stdin/stdout are not TTYs. |
| `--no-interactive` | Never prompt; use defaults or flags. |
| `--path ` | Write the config to a custom path. |
| `--force` | Overwrite an existing file. |
| `--skip-install` | Only write the file; don’t install packages. |
**Database flags**
| Flag | Description |
| ----------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--database ` | `postgres` \| `mysql` \| `sqlite` \| `sqlserver` \| `prisma` |
| `--connection-env ` | Env var name for the connection URL. |
| `--sqlite-file ` | SQLite file path, or an env var name (`UPPER_SNAKE_CASE`, e.g. `SQLITE_FILE`) to read the path from. Anything else, such as `data.db` or `../db/app.db`, is written as a literal path. |
| `--prisma-schema ` | Path to `schema.prisma`. |
| `--schema-out ` | Schema output directory (default `./askdb`). |
**AI flags**
| Flag | Description |
| ----------------------- | -------------------------------------------------------------------------------------------- |
| `--ai-provider ` | `openai` \| `anthropic` \| `google` \| `azure` \| `foundry` \| `gateway` |
| `--ai-key-env ` | Env var name for the API key. |
| `--ai-model-env ` | Env var name for the model override. The generated config reads it into `ai.language.model`. |
**RAG flags**
| Flag | Description |
| ----------------------- | ------------------------------------------------- |
| `--rag-store ` | `file` \| `memory` \| `pgvector` (default `file`) |
| `--pgvector-env ` | Env var name for the pgvector connection URL. |
**Studio flags**
| Flag | Description |
| --------------------- | --------------------------------------------------------------------------------------------------------------- |
| `--studio-execute` | Enable Studio execute (query playground): writes a `studio.execute` block with `enabled: true`. Off by default. |
| `--no-studio-execute` | Disable Studio execute (default). |
`init` generates only the config branches you selected — SQL Server users won’t see a `pg` import, SQLite users get a `file:` field instead of `DATABASE_URL`, and Prisma users don’t get a live DB driver unless they explicitly enable Studio execute. It does not create a `.env`; it writes an `.env.example` (unless one exists) listing every variable the config reads. For `azure` and `foundry` that includes `AZURE_RESOURCE_NAME`, the subdomain of your `https://.openai.azure.com` endpoint.
### `askdb introspect`
[Section titled “askdb introspect”](#askdb-introspect)
Reads your database (or a Prisma schema file) and writes an AskDB schema artifact to disk.
```bash
askdb introspect \
--url "$DATABASE_URL" \
--out ./my-app.schema \
--schema-id my-app
```
| Flag | Description |
| ---------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--url ` | Live database connection string. |
| `--engine ` | Engine override: `postgres`, `mysql`, `sqlite`, `sqlserver`, `prisma`. |
| `--prisma-schema ` | `.prisma` file or directory. With `--engine prisma`. |
| `--from-export ` | Introspect from a previously exported bundle directory instead of a live connection. Postgres only. Mutually exclusive with `--url`. |
| `--out ` | Output directory for the schema artifact. Falls back to `introspection.outputDir` in `askdb.config.ts`. |
| `--schema-id ` | Identifier embedded in `schema.json`. |
| `--schemas ` | Comma-separated database schemas to include (e.g. `public,sales`). For MySQL/MariaDB these are databases; each becomes its own namespace. Overrides `introspection.schemas` in `askdb.config.ts`. |
| `--exclude-schemas ` | Comma-separated database schemas to skip. |
| `--tables ` | Comma-separated tables to include. Repeatable — values accumulate. |
| `--print` | Print the introspection result without writing. |
| `--diff ` | Diff against an existing schema artifact. |
`askdb introspect` also accepts the [shared logging flags](#shared-logging-flags).
Live introspection requires the matching engine driver (`pg`, `mysql2`, `better-sqlite3`, or `mssql`) in the project running `askdb`, or supplied in the same one-off command:
```bash
pnpm dlx -p askdb -p pg askdb introspect --engine postgres --url "$DATABASE_URL"
npx -p askdb -p mssql askdb introspect --engine sqlserver --url "$SQLSERVER_URL"
```
### `askdb enrich`
[Section titled “askdb enrich”](#askdb-enrich)
Alias of [`askdb studio`](#askdb-studio): opens Studio for authoring per-table descriptions, aliases, concepts, and sensitive markers.
```bash
askdb enrich --schema ./my-app.schema
```
| Flag | Description |
| --------------------- | ---------------------------- |
| `-s, --schema ` | Path to the schema artifact. |
### `askdb studio`
[Section titled “askdb studio”](#askdb-studio)
Launches Studio — the browser-based authoring UI — pointed at your schema artifact.
```bash
askdb studio --schema ./my-app.schema
```
| Flag | Description |
| --------------------- | ------------------------------------------------------------------------------------ |
| `-s, --schema ` | Path to the schema artifact. |
| `--port ` | Override the listen port (default `5556`; or set `studio.listen.port` in config). |
| `--host ` | Override the bind host (default `127.0.0.1`; or set `studio.listen.host` in config). |
Requires `@askdb/studio` to be installed (lazy-imported on first use). Studio schema browsing, enrichment, and SQL generation do not require a database driver; the optional Playground execute path requires the matching driver (`pg`, `mysql2`, `better-sqlite3`, or `mssql`). `askdb init --studio-execute` installs the correct driver automatically.
`askdb studio` is the one command that *completes* setup: run it with no config (or no schema artifact) and Studio opens a [guided setup wizard](/studio/#guided-setup) in the browser that scaffolds both. An explicit `--schema` pointing at a missing directory is an error, since you asked for a specific artifact.
If `askdb.config.*` exists but fails to load (a syntax error, or its dependencies aren’t installed yet), Studio prints a warning with the load error and starts without the config. The setup wizard never overwrites an existing config file; fix it and restart Studio.
### `askdb bundle`
[Section titled “askdb bundle”](#askdb-bundle)
Writes the entire schema artifact (physical layer + enrichment + tenant policy) as a single JSON file for distribution.
```bash
askdb bundle ./my-app.schema --out ./my-app.schema.bundle.json
```
### `askdb ask`
[Section titled “askdb ask”](#askdb-ask)
Generates SQL from a natural-language question against a loaded schema artifact.
```bash
askdb ask \
--schema ./my-app.schema \
--question "Top 5 customers by lifetime value"
```
| Flag | Description |
| ------------------------------ | ------------------------------------------------------------------------------------------------------------ |
| `-s, --schema ` | Path to the schema artifact. Optional — defaults to the configured `introspection.outputDir`, or `./askdb/`. |
| `-q, --question ` | The natural-language question (required). |
| `--mode ` | Operating mode: `schema_only` (default) or `bounded_results`. |
| `--explain` | After the SQL, print a JSON block describing the heuristic guardrails satisfied. |
| `--omit-sensitive-from-prompt` | Exclude sensitive columns from the prompt entirely. |
| `--mock-sql ` | Deterministic output for tests — bypasses the live model call. |
`askdb ask` also accepts the [shared logging flags](#shared-logging-flags).
If the generated SQL references identifiers your schema marks `sensitive`, `askdb ask` prints a `Warning:` line to stderr listing them and still prints the SQL. The check is [`validateSensitiveReferences`](/reference/core-api/#validatesensitivereferencessql-schema-options) from `@askdb/core`, run by `ask()` in warn mode; embedding hosts can switch it to `strict` or call it directly on cached SQL.
You never pass a SQL dialect — it resolves automatically: `dialect` in `askdb.config.ts` when set, otherwise the engine recorded in the schema artifact at introspection time, otherwise `postgres`.
`askdb ask` returns the checked SQL on stdout. Execution is not part of the CLI.
## Shared logging flags
[Section titled “Shared logging flags”](#shared-logging-flags)
`askdb ask`, `askdb introspect`, and the `askdb-rag` binary all accept the same structured-logging flags:
| Flag | Description |
| ----------------------- | ---------------------------------------------------------------------------------------------------------------------- |
| `-v, --verbose` | Emit structured JSON log events (level `info`) to stderr. |
| `--log-level ` | `trace`, `debug`, `info`, `warn`, `error`, `fatal`, or `silent`. Default reads `logging.level` from `askdb.config.ts`. |
| `--log-file ` | Append structured JSON logs to a file. |
| `--log-stdout` | Mirror structured JSON logs to stdout. |
| `--correlation-id ` | Tag every log event with a correlation ID of your choosing. |
## The `askdb-rag` binary
[Section titled “The askdb-rag binary”](#the-askdb-rag-binary)
`@askdb/rag` ships its own small binary with three commands.
### `askdb-rag setup-store`
[Section titled “askdb-rag setup-store”](#askdb-rag-setup-store)
Provisions the pgvector schema for `@askdb/rag` idempotently. Safe to run in CI / deploy steps.
```bash
askdb-rag setup-store --pg-url "$DATABASE_URL" --embedder openai
```
| Flag | Description |
| ------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--pg-url ` | Postgres connection string (required). |
| `--pg-table ` | Custom table name. Default `askdb_rag_chunks`. |
| `--embedder ` / `--embedder-model ` | Used to pick the default dimensions, the same way `index` does. `--embedder` must be `mock` or `openai`. |
| `--dimensions ` | Embedding dimensions. Defaults to the embedder’s: `64` for the default `mock` embedder, `1536` for `--embedder openai` (`text-embedding-3-small`), `3072` for `text-embedding-3-large`. `setup-store` creates an HNSW index, which pgvector supports only up to 2000 dimensions, so for `text-embedding-3-large` pass `--dimensions` of 2000 or less (OpenAI’s `text-embedding-3` models can shorten their vectors) or create the table yourself with `createPgvectorStore({ indexStrategy: "none" })`. |
If the table already exists with a different `vector(n)` dimension, the command fails with an error rather than keeping the old dimension silently.
### `askdb-rag index`
[Section titled “askdb-rag index”](#askdb-rag-index)
Chunks and embeds a schema artifact into the configured store — the CLI equivalent of `buildSchemaIndex`.
```bash
askdb-rag index ./my-app.schema --store pgvector --embedder openai
```
| Flag | Description |
| ------------------------- | -------------------------------------------------------------------------------------------------------------------------------- |
| `--store ` | `memory`, `file` (default — persists next to the artifact), or `pgvector`. |
| `--embedder ` | `mock` (default, deterministic, CI-safe) or `openai` (reads `OPENAI_API_KEY`, or pass `--api-key`). |
| `--embedder-model ` | Embedding model. Default `text-embedding-3-small`. |
| `--dimensions ` | Embedding dimensions. Also sets the `mock` embedder’s vector size (default `64`). |
| `--pg-url` / `--pg-table` | pgvector connection when `--store pgvector`. The table is provisioned (idempotently) and its dimensions checked before indexing. |
| `--force` | Re-embed every chunk, even ones the store already holds. |
Only chunks the store doesn’t already hold (same id and content hash) are embedded. `schema.lock.json` records the embedder id, store, and dimensions; a different embedder id (which includes `--dimensions`) re-embeds everything, and a different store gets whatever it doesn’t hold. A different width needs a store with no vectors of the old width: a new or recreated pgvector table, or deleted file-store embeddings files.
### `askdb-rag query`
[Section titled “askdb-rag query”](#askdb-rag-query)
Runs a similarity query against an indexed store — useful for checking what retrieval would hand the model.
```bash
askdb-rag query ./my-app.schema --question "customer signups" -k 8
```
| Flag | Description |
| ---------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--question ` | The query text (required). |
| `-k ` | Top-k chunks to return. Default `8`. |
| `--types ` | Restrict chunk types, e.g. `table,column,cql`. |
| `--store`, `--embedder`, `--embedder-model`, `--dimensions`, `--pg-url`, `--pg-table`, `--file-path` | Must match the `index` run. `query` fails if the embedder id or dimensions differ from `schema.lock.json`, or if the lock records no embedder id. `--store memory` isn’t supported: a memory store only lives inside one process. |
All three commands accept the [shared logging flags](#shared-logging-flags).
## Exit codes
[Section titled “Exit codes”](#exit-codes)
| Code | Meaning |
| ---- | --------------------------------------------------- |
| `0` | Success. |
| `1` | Generic error (config, IO, generation, validation). |
| `2` | Invalid CLI arguments. |
`askdb-rag` exits `1` for every error, including invalid arguments.
Errors print to stderr in human form; structured log events (with `-v`) follow the contract in [`@askdb/core` logging](/reference/packages/).
An unexpected error, such as a config file that fails to load, prints its message and the hint `Set ASKDB_DEBUG=1 to print the stack trace.` Set `ASKDB_DEBUG` to `1` or `true` to add the stack trace. Any other value, including `0`, leaves it off, and the `DEBUG` variable used by the `debug` package has no effect.
## Read next
[Section titled “Read next”](#read-next)
[**Configuration**defineConfig, env vars, and how the CLI resolves settings.](/reference/config/)[**Package reference**What each @askdb/\* package adds to the CLI.](/reference/packages/)
# @askdb/client API reference
> Full API reference for @askdb/client: createAskDb(), AskDbClient, and per-call overrides.
Reference · @askdb/client
`@askdb/client` is a config-driven facade over `@askdb/core`. `createAskDb()` resolves the schema, model, and dialect from `askdb.config.*` once; call sites pass only a question. Use it when you want the shortest path from config to SQL. Use `@askdb/core` directly when you construct the model yourself, serve multiple schemas, or want zero dependency on `@askdb/config`.
## `createAskDb(options)`
[Section titled “createAskDb(options)”](#createaskdboptions)
Builds a client bound to a config snapshot and AI provider registry. The schema, model, and dialect are resolved lazily on the first `ask()` call and cached for the process lifetime. Call `reload()` to clear the cache.
```ts
import { createAskDb } from "@askdb/client";
import { bootstrapAskDbEnv, getAskDbRuntimeConfig } from "@askdb/config";
bootstrapAskDbEnv({ cwd: process.cwd() });
const askdb = createAskDb({
config: getAskDbRuntimeConfig(), // ai.provider picks one of @askdb/ai's built-in providers
schema: { path: "./my-app.schema" },
});
```
Install the AI SDK package for the provider your config selects, for example `@ai-sdk/openai`. It’s an optional peer of `@askdb/ai` and is loaded the first time the client builds a model.
### Options — `CreateAskDbOptions`
[Section titled “Options — CreateAskDbOptions”](#options--createaskdboptions)
| Field | Type | Required | Description |
| ---------------- | -------------------------------- | -------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `config` | `AskDbRuntimeConfig` | yes | Runtime config snapshot from `getAskDbRuntimeConfig()`. Call `bootstrapAskDbEnv()` at startup first. |
| `providers` | `AiProviderAdapters` | no | Which providers the client can build models for. Default: every provider built into `@askdb/ai` (`openai`, `anthropic`, `google`, `azure`/`foundry`, `gateway`). Pass built-in names to restrict the set (`["openai"]`) or `AiProviderAdapter` objects to add custom providers; both can be mixed. |
| `registry` | `AiRegistry` | no | Prebuilt registry from `createAiRegistry(...)` — advanced alternative to `providers` (e.g. to share one registry across clients). Pass at most one of `providers` or `registry`. |
| `schema` | `SchemaSource` | no | Default schema source. Falls back to `host.schemaJson`, then `host.schemaPath`, from `askdb.config.ts`. |
| `dialect` | `BuiltInDialectId` | no | Default dialect override. Falls back to `config.nlToSql.dialect` → `schema.provider` → `"postgres"`. |
| `unknownDialect` | `"throw" \| "fallback-postgres"` | no | What to do when `schema.provider` is not a recognized built-in dialect id. Default `"throw"`. |
| `onResolve` | `(info: ResolveInfo) => void` | no | Hook fired on every `ask()` call once resolution completes. Useful for logging which dialect and model were chosen. `ResolveInfo` has `dialect` and `modelSource`. |
### `SchemaSource`
[Section titled “SchemaSource”](#schemasource)
Accepted forms for the `schema` option and per-call overrides:
```ts
{ path: string } // directory, bundle file, or schema.json path
{ json: string } // raw JSON string
{ schema: AnyNormalizedSchema} // pre-loaded schema object
```
***
## `client.ask(question, overrides?)`
[Section titled “client.ask(question, overrides?)”](#clientaskquestion-overrides)
```ts
const { sql, usage, unboundSql, params, preparedQuery } = await askdb.ask(
"How many orders shipped last month?",
);
```
Runs the same pipeline as `@askdb/core`’s `ask()`. Returns `AskPipelineResult` — see [@askdb/core API → Result](/reference/core-api/#result--askpipelineresult). The facade forwards options and returns the core result verbatim, including optional `unboundSql` / `params` / `parameters` / `preparedQuery` when `parameterize` is on (default). Rebind locally with `bindPreparedQuery` from `@askdb/core` — it does not authorize tenant IDs.
### Overrides — `AskOverrides`
[Section titled “Overrides — AskOverrides”](#overrides--askoverrides)
All `AskPipelineOptions` fields can be overridden per call. In addition, `schema`, `model`, and `dialect` can be swapped for a single request:
| Field | Type | Description |
| ------------------------------------------- | ------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `schema` | `SchemaSource \| AnyNormalizedSchema` | Override the default schema for this call only. |
| `model` | `AskDbLanguageModel` | Override the default model for this call only. |
| `dialect` | `AskDialectInput` | Override the dialect for this call only. |
| `explain` | `boolean` | Include guardrail metadata in the result. |
| `omitSensitiveIdentifiersFromNlToSqlPrompt` | `boolean` | Strip sensitive identifiers from the DDL prompt. |
| `mode` | `AskDbModeV1` | Trust boundary override. |
| `tenantScope` | `TenantScope` | Required when the schema has a tenant policy. |
| `tenantSqlMode` | `TenantSqlOutputMode` | `"sql-only"` or `"sql-params"`. |
| `resolveTenantDescendants` | `ResolveTenantDescendants` | Expands a `subtree` tenant scope: returns the subtree’s IDs grouped by tenant root (`TenantIdsByRoot`), which `ask()` binds to each root’s own placeholder. Required for `subtree` scopes. See [`ask()` options](/reference/core-api/#options). |
| `parameterize` | `boolean` | Default `true`. Set `false` to skip unbound SQL / parameter manifest output tokens. |
| `retriever` | `Retriever` | RAG retriever. |
| `retrievalK` | `number` | Top-k for the retriever. |
| `retrievalThresholdChunks` | `number` | Chunk count threshold for triggering retrieval. |
| `totalSchemaChunkCount` | `number` | Total indexed chunk count; from `buildSchemaIndex` result stats. |
| `logger` | `AskDbLogger` | Per-call structured logger. |
| `deps` | `AskGenerateDeps` | `{ generateText? }` for testing. |
***
## `client.reload()`
[Section titled “client.reload()”](#clientreload)
```ts
askdb.reload();
```
Drops the cached schema and model. The next `ask()` call re-resolves them from config. Useful in tests or in processes that hot-reload their config without restarting.
***
## Read next
[Section titled “Read next”](#read-next)
[**@askdb/core API**`ask()` options and result types in full.](/reference/core-api/)[**Configuration reference**All `askdb.config.*` fields and environment variables.](/reference/config/)[**Embed in a Node app**End-to-end walkthrough using both the direct and client paths.](/guides/embed-in-node/)
# Configuration reference
> askdb.config.ts, defineConfig, environment variables, and how AskDB resolves runtime settings.
Reference · Configuration
AskDB resolves config from two sources: an `askdb.config.*` file (TypeScript or JavaScript) and environment variables. Both are loaded by `@askdb/config` at startup into an in-memory runtime snapshot.
## `askdb.config.ts`
[Section titled “askdb.config.ts”](#askdbconfigts)
`askdb init` scaffolds this file. It uses `defineConfig` for type safety:
```ts
import { defineConfig, env } from "@askdb/config";
export default defineConfig({
ai: {
provider: "openai",
providerConfig: {
openai: { apiKey: env("OPENAI_API_KEY") },
},
language: { model: env("OPENAI_MODEL") },
embedding: { model: "text-embedding-3-small" },
},
introspection: {
provider: "postgres",
providerConfig: {
postgres: { databaseUrl: env("DATABASE_URL") },
},
outputDir: "./my-app.schema",
},
rag: {
embedder: "ai",
store: "pgvector",
storeConfig: {
pgvector: { databaseUrl: env("PGVECTOR_URL") },
},
},
logging: {
level: "info",
},
});
```
Use the `env()` helper (rather than `process.env`) so AskDB can capture which environment variables your config depends on and apply its defaults pass.
`defineConfig` returns the object unchanged at runtime — it exists only for type inference. The full type is `AskDbConfig`.
## All top-level fields
[Section titled “All top-level fields”](#all-top-level-fields)
| Field | Required | What it configures |
| --------------- | -------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `ai` | yes | Provider connections (`provider`, `providerConfig`), the language model (`language`) and the embedding model (`embedding`). See [The `ai` block](#the-ai-block) and [Bring your own model](/guides/bring-your-own-model/). |
| `introspection` | yes | Introspection engine (`provider`: `postgres`, `mysql`, `sqlite`, `sqlserver`, `prisma`), its connection (`providerConfig`), `outputDir` (default `./askdb/`), and optionally `schemas`: the schemas to introspect, like `askdb introspect --schemas` (which overrides it). On MySQL/MariaDB these are databases. |
| `rag` | yes | Embedder (`mock`, or `ai` for the `ai.embedding` model) and vector store (`file`, `memory`, `pgvector`) plus the store’s config branch. See [The `rag` block](#the-rag-block). |
| `dialect` | no | Override the NL-to-SQL dialect (`postgres`, `mysql`, `sqlite`, `sqlserver`). When unset, it’s inferred from the schema artifact’s recorded provider. |
| `modes` | no | `askdbMode` (`schema_only` default, `bounded_results`) and `omitSensitiveFromPrompt` (default `false`). |
| `host` | no | `schemaPath` — the default schema artifact for embedding hosts and the HTTP API. `schemaJson` — inline artifact JSON, for environments without a file system path. |
| `logging` | no | `level`, plus `logFile`, `logStdout`, and `correlationId` defaults for the CLI’s structured logs. |
| `studio` | no | `listen.{host,port}` (defaults `127.0.0.1:5556`) and the `execute` block below. |
| `httpApi` | no | `listen.{host,port}` for the HTTP API server (defaults `127.0.0.1:3000`). Use `env("PORT")` on platforms that inject a port. |
| `dev` | no | `mockSql` — deterministic NL-to-SQL output for tests; bypasses the model call. |
### `dialect` — when inference is wrong
[Section titled “dialect — when inference is wrong”](#dialect--when-inference-is-wrong)
The dialect normally resolves from the schema artifact (the engine recorded at introspection time). Set `dialect` only when that inference is wrong — for example, a Prisma schema that declares `provider = "postgresql"` while your runtime target is a different engine:
```ts
export default defineConfig({
// ...
dialect: "mysql",
});
```
### `modes` and `host`
[Section titled “modes and host”](#modes-and-host)
```ts
export default defineConfig({
// ...
modes: {
askdbMode: "schema_only", // default
omitSensitiveFromPrompt: true, // strict sensitive-column handling
},
host: {
schemaPath: "./my-app.schema", // default artifact for embedding + HTTP API
},
});
```
## The `ai` block
[Section titled “The ai block”](#the-ai-block)
`ai` separates *how to reach a provider* from *which model to use for what*:
* **`ai.providerConfig`** holds provider connections: keys, endpoints, Azure resources, API versions. No model names.
* **`ai.language`** picks the language model AskDB writes SQL and enrichment suggestions with.
* **`ai.embedding`** picks the embedding model behind `rag.embedder: "ai"`.
* **`ai.provider`** is the default provider for both sections.
A section’s provider is its own `provider`, else `ai.provider`. Its connection is its own `connection`, else the connection named `"default"` within that provider. Loading fails when a section has no provider, names a connection that doesn’t exist, or uses a built-in provider with no connection at all. Each section only ever receives its own connection’s settings, so a key configured for one provider is never sent to another.
Anthropic for SQL, OpenAI for embeddings:
```ts
export default defineConfig({
ai: {
provider: "anthropic",
providerConfig: {
anthropic: { apiKey: env("ANTHROPIC_API_KEY") },
openai: { apiKey: env("OPENAI_API_KEY") },
},
language: { model: "claude-sonnet-4-6" },
embedding: { provider: "openai", model: "text-embedding-3-small" },
},
rag: { embedder: "ai", store: "file", storeConfig: { file: {} } },
// ...
});
```
Two Azure resources, one for each model:
```ts
export default defineConfig({
ai: {
provider: "azure",
providerConfig: {
azure: [
{ resourceName: "eastus-chat", apiKey: env("AZURE_CHAT_KEY") }, // name: "default"
{ name: "westus", resourceName: "westus-embed", apiKey: env("AZURE_EMBED_KEY") },
],
},
language: { model: "my-gpt-4o-deployment", modelFamily: "gpt-4o" },
embedding: { connection: "westus", model: "my-embedding-deployment", dimensions: 1536 },
},
rag: { embedder: "ai", store: "pgvector", storeConfig: { pgvector: { databaseUrl: env("PGVECTOR_URL") } } },
// ...
});
```
### `ai.providerConfig`
[Section titled “ai.providerConfig”](#aiproviderconfig)
Keyed by provider id. Each value is one connection, or a list of connections when a provider needs more than one.
| Provider key | Connection fields |
| ------------------ | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `openai` | `apiKey`, `baseUrl` (any OpenAI-compatible endpoint) |
| `azure`, `foundry` | `apiKey`, `secondaryApiKey`, `resourceName` (the subdomain of `https://.openai.azure.com`), `baseUrl` (a full endpoint URL; overrides `resourceName`), `apiVersion`. One of `resourceName` or `baseUrl` is required. |
| `anthropic` | `apiKey`, `baseUrl` |
| `google` | `apiKey`, `baseUrl` |
| `gateway` | `apiKey`, `baseUrl` (Vercel AI Gateway) |
| any other id | `apiKey`, `baseUrl`, for a [custom provider](#custom-providers) |
Every connection also takes `name`, which defaults to `"default"` and must be unique within its provider. A list needs a `"default"` entry unless every section that uses the provider sets `connection`.
### `ai.language`
[Section titled “ai.language”](#ailanguage)
| Field | Default | Notes |
| ------------- | ------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `provider` | `ai.provider` | |
| `connection` | `"default"` | A connection name in `ai.providerConfig.`. |
| `model` | The provider’s default language model | `openai`: `gpt-4o-mini`. `anthropic`: `claude-sonnet-4-6`. `google`: `gemini-2.0-flash`. `gateway`: `openai/gpt-4o-mini`. `azure` and `foundry`: the deployment name, default `gpt-4o-mini`. A custom provider has no default. |
| `modelFamily` | none | Azure and Foundry: the underlying model id when `model` is a deployment name. See [Azure deployment names](#azure-deployment-names). |
| `reasoning` | none | See [Reasoning effort](#reasoning-effort). |
### `ai.embedding`
[Section titled “ai.embedding”](#aiembedding)
Read only when `rag.embedder` is `"ai"`; ignored for `"mock"`.
| Field | Default | Notes |
| ------------ | --------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `provider` | `ai.provider` | Anthropic has no embeddings API, so a config whose `ai.embedding` provider resolves to `anthropic` fails to load. Set `provider` (for example `"openai"`) and give it a connection. |
| `connection` | `"default"` | A connection name in `ai.providerConfig.`. |
| `model` | none, required | AskDB has no default embedding model. On Azure, the embedding deployment name. On the AI Gateway, an `/` id such as `openai/text-embedding-3-small`. |
| `dimensions` | The model’s own width | A positive integer: the vector size to request from the provider, for models that let you choose one (OpenAI’s `text-embedding-3` models, Gemini’s; on the AI Gateway, `openai/…` and `google/…` models). Unset, AskDB assumes nothing: it uses the width the model returns, which it learns when it first builds the index, so the `pgvector` store doesn’t need it either. |
Changing the `ai.embedding` provider, model or dimensions changes the index’s embedder id: Studio then reports the RAG index as stale and asks you to reindex before using it.
### Reasoning effort
[Section titled “Reasoning effort”](#reasoning-effort)
`ai.language.reasoning` is an optional, provider-portable knob for how much reasoning/thinking effort AskDB’s model calls use. Leave it unset to keep the provider/model’s own default (AskDB sends no reasoning options at all — this is the default, unchanged behavior).
```ts
export default defineConfig({
ai: {
provider: "openai",
providerConfig: { openai: { apiKey: env("OPENAI_API_KEY") } },
language: {
reasoning: {
effort: "medium", // global default for every AskDB model call
nlToSql: "high", // override: accuracy-sensitive NL→SQL generation
enrichment: "low", // override: non-critical enrichment suggestions
},
},
},
// ...
});
```
* `effort` — global default. One of `"minimal" | "low" | "medium" | "high"`.
* `nlToSql` — overrides `effort` for NL→SQL generation calls (`ask()`). Typically left unset (provider default) or `"medium"`/`"high"` — this path is accuracy-sensitive.
* `enrichment` — overrides `effort` for enrichment/suggestion calls (`suggestEnrichment()`). Safe to bias toward `"low"`/`"minimal"` for latency and cost — these are non-critical.
AskDB maps the portable value to each provider’s native knob via `@askdb/ai`’s `resolveProviderOptions` — OpenAI/Azure `providerOptions.openai.reasoningEffort`, Google Gemini 3.x `providerOptions.google.thinkingConfig.thinkingLevel`, Gemini 2.5 `thinkingConfig.thinkingBudget`, Anthropic `thinking` (adaptive thinking plus `effort` on Claude Sonnet 4.6, Opus 4.6 and newer, and the 5.x models; a `budgetTokens` budget on Claude 3.7 Sonnet and the 4.0–4.5 models). Models that don’t support reasoning tuning (e.g. `gpt-4o-mini`, `gpt-5-chat-latest`, `gemini-2.0-flash`, `claude-3-5-haiku`) never receive these options, even when `reasoning` is set. Where a model has no `minimal` level, AskDB sends `low` instead: OpenAI and Azure gpt-6 and later (which accept `low` through `max`), and Anthropic models that take `effort`. For the Vercel AI Gateway (`gateway`), AskDB uses the mapping of the model’s upstream (`openai/…`, `google/…`, `anthropic/…`) on the id after the prefix, and the gateway passes the options on; models from other upstreams get no reasoning options.
`@askdb/client`’s `createAskDb` resolves `ai.language.reasoning` automatically for `ask()` calls — no extra wiring needed. See [Bring your own model](/guides/bring-your-own-model/) for the client and programmatic APIs.
### Azure deployment names
[Section titled “Azure deployment names”](#azure-deployment-names)
Azure identifies models by deployment name (e.g. `askdb-reporting`), which may not match the underlying model id AskDB uses to detect reasoning support. Set `ai.language.modelFamily` (or `ASKDB_AI_AZURE_MODEL_FAMILY`) to the real model id — e.g. `"gpt-5"` or `"o3-mini"` — when your deployment name doesn’t already look like one.
## The `rag` block
[Section titled “The rag block”](#the-rag-block)
| Field | What it configures |
| ------------- | --------------------------------------------------------------------------------------------------------------------------------------- |
| `embedder` | `"mock"`, a deterministic lexical embedder that needs no key, or `"ai"`, the [`ai.embedding`](#aiembedding) model. |
| `store` | `"file"`, `"memory"` or `"pgvector"`. |
| `storeConfig` | The selected store’s branch: `file.{basePath, autoFlush}`, `memory: {}`, or `pgvector.{databaseUrl, table, indexStrategy, dimensions}`. |
With `embedder: "ai"`, the pgvector table is created at the width the embedding model returns, learned when the index is first built (with `ai.embedding.dimensions` set, that’s the size requested). An existing table of another width is refused, not overwritten. `storeConfig.pgvector.dimensions` is [deprecated](#deprecated-keys): with `embedder: "ai"` it moves to `ai.embedding.dimensions`, and with `embedder: "mock"`, whose vectors are always 64 wide, it’s ignored.
## Deprecated keys
[Section titled “Deprecated keys”](#deprecated-keys)
Configs written before the `ai.language` and `ai.embedding` sections still load, apart from the few cases below that fail with an error saying what to change. AskDB translates each old key at load and warns once per key with a Node `DeprecationWarning` (code `ASKDB_CONFIG_DEPRECATED`). The warning names the old and new location, never the value. `getAskDbRuntimeConfig().deprecations` lists the same messages. The old keys are removed at 1.0.
| Old key | Use instead |
| ------------------------------------------------------------------------------ | --------------------------------------------------------------------------------------------------- |
| `ai.providerConfig..model` | `ai.language.model` |
| `ai.providerConfig.azure.modelFamily`, `ai.providerConfig.foundry.modelFamily` | `ai.language.modelFamily` |
| `ai.reasoning` | `ai.language.reasoning` |
| `ai.providerConfig.custom` | `ai.providerConfig.` |
| `rag.embedder: "openai"` | `rag.embedder: "ai"` with `ai.embedding: { provider: "openai", model }` |
| `rag.embedder: "ai-sdk"` | `rag.embedder: "ai"` with `ai.embedding: { model }` |
| `rag.embedderConfig.openai.model`, `.dimension` | `ai.embedding.model`, `ai.embedding.dimensions` |
| `rag.embedderConfig.openai.apiKey`, `.baseUrl` | A connection in `ai.providerConfig`, named in `ai.embedding.connection` if it isn’t the default one |
| `rag.storeConfig.pgvector.dimensions` with an AI embedder | `ai.embedding.dimensions` |
| `rag.storeConfig.pgvector.dimensions` with `rag.embedder: "mock"` | Nothing: remove it. The mock embedder’s vectors are always 64 wide. |
How the old embedder keys translate:
* A model left unset means `text-embedding-3-small` on `openai`, `azure` and `foundry`, as before. Any other provider fails to load and asks for `ai.embedding.model`.
* `"ai-sdk"` embeds with the language model’s provider, so with Anthropic, which has no embeddings API, it fails to load: move to `ai.embedding` with another provider.
* The old embedders assumed a width when none was set: 3072 for `text-embedding-3-large`, 1536 for anything else, whatever the provider. AskDB no longer assumes one; it uses the width the model returns. A config in the old shape with no width set gets a warning naming the width an index built with an earlier version has: move to `ai.embedding` and set `dimensions` to it to keep that index, or rebuild the index.
* A `rag.embedderConfig.openai.apiKey` or `.baseUrl` that differs from the default connection of the embedding model’s provider moves to a connection named `"rag-embeddings"`. It can only move to an `openai`, `azure`, `foundry` or `gateway` connection; with any other embedding provider the config fails to load instead of sending the key there.
* An empty `rag.embedderConfig: {}`, which earlier scaffolds wrote, is ignored without a warning.
A model set in both places is fine: `ai.language.model` wins, and the warning says the old value is ignored. Other old keys set next to their replacement fail to load, and the error asks you to remove the old one: `ai.reasoning` with `ai.language.reasoning`, `ai.providerConfig.custom` with `ai.providerConfig.`, `rag.embedderConfig` with `ai.embedding` or `rag.embedder: "ai"`, and two different widths in `rag.storeConfig.pgvector.dimensions` and the embedding section.
## File discovery
[Section titled “File discovery”](#file-discovery)
`bootstrapAskDbEnv()` looks for config in the **current working directory only** (no upward walk), trying two locations in order:
1. `askdb.config.` — extension precedence `ts → mts → cts → js → mjs → cjs`
2. `.config/askdb.` — same extension precedence
The first match wins. JSON config files are not supported. If nothing is found, `bootstrapAskDbEnv()` throws — run your process from the directory that holds the config (or pass `cwd` in its options).
## Environment variables
[Section titled “Environment variables”](#environment-variables)
AskDB reads `.env` next to your process via `dotenv`, then evaluates your `askdb.config.*`. **You choose the variable names** — they’re whatever you pass to `env("…")` in your config. The scaffolded config uses these common names; rename any of them in your config and `.env` together:
| Variable | Reads into (config field) | Notes |
| ------------------------------ | --------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `OPENAI_API_KEY` | `ai.providerConfig.openai.apiKey` | Standard OpenAI key. |
| `OPENAI_MODEL` | `ai.language.model` | Optional model override. Default: `gpt-4o-mini`. |
| `ANTHROPIC_API_KEY` | `ai.providerConfig.anthropic.apiKey` | When `ai.provider = "anthropic"`. Default model: `claude-sonnet-4-6` (the scaffolded config reads an `ai.language.model` override from `ANTHROPIC_MODEL`). |
| `GOOGLE_GENERATIVE_AI_API_KEY` | `ai.providerConfig.google.apiKey` | When `ai.provider = "google"`. Default model: `gemini-2.0-flash` (the scaffolded config reads an `ai.language.model` override from `GOOGLE_AI_MODEL`). |
| `AI_GATEWAY_API_KEY` | `ai.providerConfig.gateway.apiKey` | When `ai.provider = "gateway"` (Vercel AI Gateway). Set `ai.language.model` to an `/` id. Default: `openai/gpt-4o-mini`. An id without the prefix is rejected when the model is built, and that includes `ai.embedding.model`: use e.g. `openai/text-embedding-3-small`. Embedding `dimensions` are sent for `openai/` and `google/` models; for other upstreams a dimension override is refused rather than dropped. |
| `AZURE_OPENAI_API_KEY` | `ai.providerConfig.azure.apiKey` | When `ai.provider = "azure"` (use `ai.providerConfig.foundry` for `"foundry"`). |
| `AZURE_OPENAI_DEPLOYMENT` | `ai.language.model` | Your Azure deployment name. |
| `AZURE_RESOURCE_NAME` | `ai.providerConfig.azure.resourceName` | The subdomain of `https://.openai.azure.com`. Required unless you set `ai.providerConfig.azure.baseUrl` to a full endpoint URL instead. Also available on the connection: `apiVersion`, `secondaryApiKey`. |
| `DATABASE_URL` | `introspection.providerConfig.postgres.databaseUrl` | Postgres introspection connection. |
Everything else AskDB needs — output directory, mode, log level, Studio query connection, the vector-store URL — is set the same way: a field in `askdb.config.ts`, bound to a name you choose with `env("…")`. You don’t set any AskDB-prefixed variables yourself; AskDB derives its internal runtime values from your config.
## Studio execute configuration
[Section titled “Studio execute configuration”](#studio-execute-configuration)
The `studio.execute` block configures the Query Playground’s live execution feature. It is **off by default**: set `enabled: true` and give Studio its own connection, ideally for a read-only database role.
```ts
export default defineConfig({
studio: {
execute: {
enabled: true,
provider: "mysql", // "postgres" | "mysql" | "sqlite" | "sqlserver"
databaseUrl: env("STUDIO_READONLY_URL"), // network databases (Postgres, MySQL, SQL Server)
// file: env("SQLITE_FILE"), // SQLite only
// timeoutMs: 30000,
// maxRows: 500,
},
},
});
```
| Field | Env key | Default |
| ------------------------------------------- | --------------------------------------------------- | -------------------------------------------------------------------------------------------- |
| `studio.execute.enabled` | `ASKDB_STUDIO_EXECUTE_ENABLED` | `false`. While off, `POST /api/execute` returns `403` and the Playground hides Execute. |
| `studio.execute.provider` | `ASKDB_STUDIO_EXECUTE_PROVIDER` | Active introspection provider, or `"postgres"` |
| `studio.execute.databaseUrl` | `ASKDB_STUDIO_DATABASE_URL` | None (see `useIntrospectionConnection`) |
| `studio.execute.file` | `ASKDB_STUDIO_SQLITE_FILE` | None (see `useIntrospectionConnection`) |
| `studio.execute.useIntrospectionConnection` | `ASKDB_STUDIO_EXECUTE_USE_INTROSPECTION_CONNECTION` | `false`. When `true`, reuse the introspection connection if `databaseUrl` / `file` is unset. |
| `studio.execute.timeoutMs` | `ASKDB_STUDIO_EXECUTE_TIMEOUT_MS` | `30000`. Per-query timeout, positive integer. Not enforced for SQLite. |
| `studio.execute.maxRows` | `ASKDB_STUDIO_EXECUTE_MAX_ROWS` | `500`. Row cap, positive integer. Results with more rows are truncated. |
**Provider resolution order:**
1. `studio.execute.provider` (structured config or `ASKDB_STUDIO_EXECUTE_PROVIDER` env).
2. The active `introspection.provider` when it is a live engine (`postgres`, `mysql`, `sqlite`, `sqlserver`).
3. `"postgres"` for backward compatibility.
**Connection resolution** (per provider):
* **Postgres, MySQL, SQL Server**: `studio.execute.databaseUrl` → `ASKDB_STUDIO_DATABASE_URL` → the introspection URL for the same engine, only when `useIntrospectionConnection: true`.
* **SQLite**: `studio.execute.file` → `ASKDB_STUDIO_SQLITE_FILE` → the introspection SQLite file, only when `useIntrospectionConnection: true`.
Studio doesn’t fall back to your introspection credentials on its own, because those usually belong to a more privileged role than ad-hoc queries should use. [Studio — Security model](/studio/#security-model) describes the read-only transaction, timeout, and row cap applied to every query.
Each execute provider requires its optional peer driver package (`pg`, `mysql2`, `better-sqlite3`, or `mssql`). See [Studio — driver packages](/studio/#driver-packages) for install instructions.
## Custom providers
[Section titled “Custom providers”](#custom-providers)
`ai.provider` (and a section’s `provider`) accepts any string — not just the first-party ids. Key a custom provider’s connection by its id in `ai.providerConfig` (`apiKey`, `baseUrl`, each bound to a name you choose with `env("…")`), put its model in `ai.language.model`, and AskDB hands them to whatever adapter is registered under that provider name.
```ts
import { defineConfig, env } from "@askdb/config";
export default defineConfig({
ai: {
provider: "mistral", // any string
providerConfig: {
mistral: { apiKey: env("MISTRAL_API_KEY") },
},
language: { model: "mistral-large-latest" },
},
// ...
});
```
This works end to end only when the consuming registry has an adapter registered under that provider name. The built-in providers, registered by the first-party apps (`@askdb/http-api`, the CLI, Studio) and by default in `createAskDb`, are `openai`, `azure` (plus `azure-openai` and `foundry`), `google`, `anthropic`, and `gateway`. For any other provider you have two options:
1. **Embed AskDB** and pass your own adapter in `createAskDb({ providers: [myAdapter] })`. It takes about 40 lines of code. Add built-in names alongside it (`providers: ["openai", myAdapter]`) if you also want those.
2. **Use the `openai` provider** with a custom `baseUrl` for any OpenAI-compatible endpoint (vLLM, OpenRouter, Together, Ollama, …).
See [Bring your own model](/guides/bring-your-own-model/) for the embedding walkthrough.
## Reading config at runtime
[Section titled “Reading config at runtime”](#reading-config-at-runtime)
In code that uses the AskDB libraries directly, call `bootstrapAskDbEnv()` at startup and then read settings via `getAskDbRuntimeConfig()`:
```ts
import { bootstrapAskDbEnv, getAskDbRuntimeConfig } from "@askdb/config";
bootstrapAskDbEnv({ cwd: process.cwd() });
const rt = getAskDbRuntimeConfig();
const aiEnv = rt.ai.aiEnv; // language model env map, for @askdb/ai
const embedding = rt.ai.embedding; // { provider, connection, model, dimensions, env } when rag.embedder is "ai"
const outputDir = rt.introspection.outputDir; // resolved artifact directory
```
`rt.ai.language` and `rt.ai.embedding` each carry the section’s resolved provider, connection name and model, plus an `env` map built from that section’s connection only. To build the embedding model, pass `rt.ai.embedding.env` to `@askdb/ai`’s `createEmbeddingModelFromEnv`, with the configured width as an option, since the env map doesn’t carry it:
```ts
import { createAiRegistry } from "@askdb/ai";
const embeddingModel = rt.ai.embedding
? await createAiRegistry().createEmbeddingModelFromEnv(rt.ai.embedding.env, {
dimensions: rt.ai.embedding.dimensions, // undefined leaves the model's own width
})
: undefined; // rag.embedder is "mock"
```
AskDB does **not** copy the full config into `process.env`. The runtime snapshot is the source of truth — use `getAskDbRuntimeConfig` rather than `process.env` for anything AskDB-specific.
## Config precedence
[Section titled “Config precedence”](#config-precedence)
For any given setting, the precedence (highest wins) is:
1. Per-call arguments — CLI flags (`--mode`, `--schema`, …) and `ask()` options.
2. The `askdb.config.*` file — the single source of truth for the runtime snapshot.
3. Built-in defaults applied for optional fields (e.g. `outputDir` → `./askdb/`).
Environment variables don’t override the config file from the outside — they flow *through* it: every `env("VAR")` call in the config reads the environment when the file loads. `.env` is loaded first (without overwriting variables already set in the real environment), so the per-environment override story is: system env beats `.env`, and whatever `env()` reads lands in the snapshot. This still lets you ship one config file and vary it per environment — just route each tunable through `env()`.
## Read next
[Section titled “Read next”](#read-next)
[**CLI reference**How each CLI command resolves config and flags.](/reference/cli/)[**Package reference**The full @askdb/config API surface.](/reference/packages/)
# @askdb/core API reference
> Full API reference for @askdb/core: ask(), schema loading, dialects, modes, and logging.
Reference · @askdb/core
`@askdb/core` is the dialect-agnostic NL-to-SQL pipeline. It owns schema loading, prompt construction, heuristic SQL checks, and tenant-scope validation and binding. Everything else in the AskDB ecosystem composes it.
## `ask(options)`
[Section titled “ask(options)”](#askoptions)
The main pipeline function. Accepts a natural-language question and a loaded schema; returns checked SQL.
```ts
import { ask } from "@askdb/core";
const { sql } = await ask({
question: "How many users signed up last week?",
schema, // from loadSchema()
model, // AI SDK LanguageModel
dialect: "postgres",
});
```
### Options
[Section titled “Options”](#options)
| Field | Type | Required | Default | Description |
| ------------------------------------------- | ----------------------------- | -------------------- | --------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `question` | `string` | yes | — | The natural-language question. |
| `schema` | `AnyNormalizedSchema` | yes | — | Loaded schema from `loadSchema()` or `loadSchemaFromJson()`. |
| `model` | `AskDbLanguageModel` | yes | — | An AI SDK `LanguageModel` instance (e.g. `openai("gpt-4o-mini")`). |
| `dialect` | `AskDialectInput` | yes | — | A built-in dialect id, `DialectSpec`, or custom `AskDialect`. See [Dialects](#dialects). |
| `mode` | `AskDbModeV1` | no | `"schema_only"` | Trust boundary. See [Modes](#modes). |
| `explain` | `boolean` | no | `false` | When `true`, populates `result.explain` with heuristic guardrail metadata. |
| `omitSensitiveIdentifiersFromNlToSqlPrompt` | `boolean` | no | `false` | When `true`, strips sensitive table/column names from the NL→SQL DDL entirely. Default (`false`) includes them with a `(sensitive)` tag so the model can still ground queries. |
| `tenantScope` | `TenantScope` | no | — | Required when the schema has a `tenant-policy.md`. The pipeline fails closed if a policy exists and this is absent. |
| `tenantSqlMode` | `TenantSqlOutputMode` | no | `"sql-only"` | `"sql-only"` inlines escaped literal tenant values; `"sql-params"` replaces them with the dialect’s driver markers (`$N` Postgres/CockroachDB and custom `AskDialect`s, `?` MySQL/MariaDB/SQLite, `@pN` SQL Server) and returns the IDs as `tenantParams`. See [Executing the result](#executing-the-result). |
| `resolveTenantDescendants` | `ResolveTenantDescendants` | for `subtree` scopes | — | `(tenantRoot, seedIds) => TenantIdsByRoot \| Promise`, where `TenantIdsByRoot` is `Record`. Returns the subtree’s IDs grouped by tenant root: the seeds and same-table descendants under `tenantRoot`, each descendant root’s IDs under that root, e.g. `{ "table:public.agencies": ["1"], "table:public.clients": ["5"] }`. `ask()` unions the seeds in and binds each root’s IDs to its own placeholder (a `multi_root` scope). Without it, or when it returns a flat array or an invalid result, a `subtree` scope throws `TenantScopeError` (`SUBTREE_NOT_RESOLVABLE`). See [Hierarchical scope](/guides/multi-tenancy/#hierarchical-scope-subtree). |
| `parameterize` | `boolean` | no | `true` | Ask the model for unbound SQL + a parameter manifest. Still exactly one model call. Set `false` to save output tokens. Inert for custom `AskDialect` implementations. |
| `sensitiveGuardrailMode` | `"warn" \| "strict" \| "off"` | no | `"warn"` | How to treat SQL that references identifiers marked `sensitive`. `"warn"` populates `result.sensitiveGuardrail` and logs; `"strict"` throws `SensitiveReferenceError`; `"off"` skips the check. See [`validateSensitiveReferences`](#validatesensitivereferencessql-schema-options). |
| `retriever` | `Retriever` | no | — | RAG retriever from `@askdb/rag`. When supplied and schema chunk count exceeds `retrievalThresholdChunks`, retrieval replaces the full DDL in the prompt. |
| `retrievalK` | `number` | no | `8` | Top-k passed to the retriever. |
| `retrievalThresholdChunks` | `number` | no | `30` | Chunk count below which the full DDL is used even if a retriever is supplied. |
| `totalSchemaChunkCount` | `number` | no | `Infinity` | Total chunk count from `buildSchemaIndex`. Pass `result.stats.chunksTotal` here for the threshold check to be meaningful; omit to always use the retriever when one is supplied. |
| `logger` | `AskDbLogger` | no | — | Structured logger. Attach one for observability — it emits `AskDbLogEvent` entries at each pipeline stage. |
| `deps` | `AskGenerateDeps` | no | — | `{ generateText? }` — inject a mock `generateText` for unit tests. |
### Result — `AskPipelineResult`
[Section titled “Result — AskPipelineResult”](#result--askpipelineresult)
| Field | Type | When present |
| -------------------- | --------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `sql` | `string` | Always. The model’s bound, checked SQL — business values inlined as literals. In `tenantSqlMode: "sql-params"` its tenant markers start at the first slot; run it with `tenantParams`. Never overwritten by rebind failures. |
| `unboundSql` | `string \| undefined` | When `parameterize` is on and the model returned a consistent unbound block + manifest. Driver markers (`$N` / `?` / `@pN`) for every value; run it with `params`. |
| `params` | `QueryParamSlot[] \| undefined` | Values for `unboundSql`, in marker order. In `"sql-params"` mode this already includes the tenant IDs. |
| `parameters` | `QueryParameterBinding[] \| undefined` | Named bindings for form UIs (includes runtime `value`, `markers`, `indices`). |
| `preparedQuery` | `PreparedQuery \| undefined` | Definitions + named template only (no runtime values). Input to `bindPreparedQuery()`. |
| `usage` | `AskUsage \| undefined` | When the model provider reports token counts. |
| `explain` | `unknown \| undefined` | When `explain: true`. Heuristic guardrail metadata — which read-only rules fired and why. |
| `sensitiveGuardrail` | `SensitiveGuardrailResult \| undefined` | When the schema declares at least one `sensitive` table/column and `sensitiveGuardrailMode` is not `"off"`. The sensitive identifiers the returned SQL references. |
| `tenantGuardrail` | `TenantGuardrailResult \| undefined` | When a tenant policy is active. `{ passed, warnings }` from the heuristic tenant check, run on the model’s SQL (and its `sql-unbound` block) before tenant binding. It requires each tenant-scoped table, and each root table the scope covers, to have a tenant predicate that filters: its tenant column compared with the placeholder, ANDed into a `WHERE`, inner-join `ON` or `HAVING` clause (see [What the tenant check requires](/guides/multi-tenancy/#what-the-tenant-check-requires)). Passing it doesn’t prove the SQL is scoped. With `enforcement: strict`, a failure throws `TenantGuardrailError` instead. |
| `tenantParams` | `unknown[] \| undefined` | When `tenantSqlMode: "sql-params"` and the SQL has tenant placeholders. The tenant IDs for the markers in `sql`, in marker order. |
| `tenantBindings` | `TenantBinding[] \| undefined` | When a tenant policy is active. Structured binding metadata for audit. |
### Executing the result
[Section titled “Executing the result”](#executing-the-result)
Each SQL form runs with exactly one params array — never concatenate `params` and `tenantParams`:
| SQL | Run with | Contents |
| ------------ | ------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `sql` | `tenantParams` (or nothing in `"sql-only"` mode) | Business values inlined; tenant IDs as literals (`"sql-only"`) or markers numbered from the first slot (`"sql-params"`). |
| `unboundSql` | `params` | All values bound. In `"sql-params"` mode tenant IDs are included — after the business values for `$N` / `@pN`, interleaved in source order for `?`. `parameters[].indices` point into `params`. In `"sql-only"` mode tenant IDs stay inlined and `params` holds business values only. |
```ts
const result = await ask({ ...options, dialect: "mysql", tenantScope, tenantSqlMode: "sql-params" });
if (result.unboundSql && result.params) {
await conn.execute(result.unboundSql, result.params);
} else {
await conn.execute(result.sql, result.tenantParams ?? []);
}
```
Tenant substitution fails closed. It only replaces placeholders in SQL code (never inside string literals or quoted identifiers) and throws `TenantScopeError` when the SQL references a tenant root the scope has no IDs for (`UNRESOLVED_TENANT_PLACEHOLDER`), or when several IDs meet a predicate with no list form such as `<=` (`UNSUPPORTED_TENANT_PREDICATE`). With several IDs, `=` becomes `IN (…)` and `!=` / `<>` become `NOT IN (…)`. Inlined tenant IDs are escaped for the dialect: when a `DialectSpec` leaves `backslashEscapes` unset, a built-in `id` supplies it (on for MySQL and MariaDB). If the `id` isn’t built-in, a tenant ID containing a backslash throws `UNESCAPABLE_TENANT_ID` in `"sql-only"` mode instead of being escaped by guesswork.
### `bindPreparedQuery(prepared, values)`
[Section titled “bindPreparedQuery(prepared, values)”](#bindpreparedqueryprepared-values)
Pure, synchronous local rebind — no model call. Returns both a ready-to-run `sql` and `unboundSql` + `params` for driver binding. Checks names, types, and cardinality only; **does not authorize tenant IDs**.
```ts
import { bindPreparedQuery } from "@askdb/core";
const rebound = bindPreparedQuery(result.preparedQuery!, {
state_name: "Utah",
":tenant_agency_ids": authorizedAgencyIds,
});
await pool.query(rebound.sql);
// or: await pool.query(rebound.unboundSql, rebound.params);
```
List parameters are arity-stable in `unboundSql` only on PostgreSQL/CockroachDB (`= ANY($n)`). Elsewhere a changed list length changes the marker count — rebind rather than swapping the array. Map SQL Server values via `parameters[].markers` (`@p0`-based).
### `AskUsage`
[Section titled “AskUsage”](#askusage)
```ts
type AskUsage = {
promptTokens: number | null;
completionTokens: number | null;
totalTokens: number | null;
};
```
Populated from the model provider’s usage report. Use for cost tracking or quota enforcement. All fields are `null` when the provider does not report that counter.
***
## Guardrails
[Section titled “Guardrails”](#guardrails)
### `validateSensitiveReferences(sql, schema, options?)`
[Section titled “validateSensitiveReferences(sql, schema, options?)”](#validatesensitivereferencessql-schema-options)
Reports the `sensitive` tables and columns a SQL statement references. Pure, synchronous, no model call.
`sensitive: true` otherwise only affects the **prompt** — `formatSchemaForNlToSql` either tags identifiers `(sensitive)` or, with `omitSensitiveIdentifiersFromNlToSqlPrompt`, withholds them. Both act on what the model *sees*. This function is the **enforcement** path: it inspects SQL that is about to execute. Hosts that cache, store, or replay generated SQL should call it on **every execution path**, not just at generation time.
```ts
import { validateSensitiveReferences } from "@askdb/core";
// Cache-replay path — no model in the loop.
const { passed, references } = validateSensitiveReferences(cachedSql, schema);
if (!passed) {
throw new Error(`refusing to replay: ${references.map((r) => r.column).join(", ")}`);
}
```
`ask()` runs this automatically over the SQL it returns and attaches the result as `result.sensitiveGuardrail`; use the standalone function for statements that did not come from this `ask()` call.
#### Result — `SensitiveGuardrailResult`
[Section titled “Result — SensitiveGuardrailResult”](#result--sensitiveguardrailresult)
| Field | Type | Meaning |
| ----------------- | ----------------------------------- | ----------------------------------------------------------------------------------------- |
| `passed` | `boolean` | `true` only when nothing sensitive was referenced **and** table scope was fully resolved. |
| `references` | `SensitiveReference[]` | Every sensitive identifier the statement touches. |
| `unresolvedScope` | `SensitiveScopeReport \| undefined` | Present when the statement’s `FROM`/`JOIN` scope could not be resolved with confidence. |
```ts
type SensitiveReference = {
table: string; // table name as spelled in the schema artifact
schema?: string; // namespace, when the artifact records one
column: string; // column name, or "*" when matchKind is "table"
matchKind: "qualified" | "unqualified" | "table";
};
```
* **`"qualified"`** — `table.column`, or `alias.column` where the alias binds to the owning table. Also `alias.*` and whole-row references such as `row_to_json(alias)` or `to_jsonb(alias)`, which reach every sensitive column of that table.
* **`"unqualified"`** — a bare `column`, counted **only because the owning table is in the statement’s scope**. Also a bare `SELECT *`, which reaches every sensitive column of the tables in that `SELECT`’s own `FROM`/`JOIN` (not a subquery’s).
* **`"table"`** — the sensitive table itself is a `FROM`/`JOIN` target. Catches `SELECT * FROM secrets`, where no column is named.
#### Options
[Section titled “Options”](#options-1)
| Option | Type | Default | Meaning |
| --------- | --------------------------- | -------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `mode` | `"warn" \| "strict"` | `"warn"` | See [Modes](#modes). |
| `dialect` | `DialectSpec` (or `{ id }`) | — | Lex the SQL the way that engine does (MySQL backslash escapes and `#` comments, Postgres `E'…'` and `$tag$…$tag$`, SQL Server `[…]`). Without it, references are collected under every built-in engine’s reading, which is conservative and can over-report in rare cases. |
#### Scope resolution
[Section titled “Scope resolution”](#scope-resolution)
An unqualified name is not a substring search. `FROM`/`JOIN` targets and their aliases are resolved first — including inside CTEs and derived tables — and bare names are matched only against the columns of tables actually in scope.
This matters most with table-level `sensitive`, which promotes *every* column of that table into the match set. A schema with a `sensitive` audit or changelog table that has an `id` column would otherwise flag `SELECT s.id FROM students s`. It does not:
```ts
validateSensitiveReferences(
"SELECT s.id, s.first_name FROM people.students s",
schema,
); // → { passed: true, references: [] }
validateSensitiveReferences("SELECT email, password FROM identity.users", schema);
// → references: [{ table: "users", schema: "identity", column: "password", matchKind: "unqualified" }]
```
#### Modes
[Section titled “Modes”](#modes)
`{ mode: "warn" }` (default) returns the references without throwing. `{ mode: "strict" }` throws `SensitiveReferenceError extends AskDbError` whenever `passed` is `false`, carrying `.rule` (`"SENSITIVE_TABLE_REFERENCED"` | `"SENSITIVE_COLUMN_REFERENCED"` | `"UNRESOLVED_TABLE_SCOPE"`), `.references`, and `.unresolvedScope`.
#### Conservative failure
[Section titled “Conservative failure”](#conservative-failure)
When the check can tell it couldn’t bind names to tables, it reports that in `unresolvedScope` rather than passing. It can’t always tell: a table in a `FROM` form it doesn’t recognize is skipped without a report (see [Safety boundaries](/concepts/safety-boundaries/), #306–#309). `unresolvedScope.issues` contains one or more of:
| Issue | Cause | Effect |
| --------------------- | ------------------------------------------------------------------------------------- | --------------------------------------------------------------------- |
| `NO_TABLE_SOURCE` | No `FROM`/`JOIN` target resolved, so unqualified names cannot be bound. | Unqualified matching widens to every sensitive column. |
| `UNKNOWN_QUALIFIER` | A `qualifier.column` whose qualifier is not a known table, alias, or CTE. | That column is matched against every sensitive column. |
| `OPAQUE_TABLE_SOURCE` | A table source that is not a relation name (table function, table-valued expression). | Reported only; no widening — such a source exposes no schema columns. |
| `UNTERMINATED_TOKEN` | A string, quoted identifier, or comment never closes. | Reported only; the rest of the statement could not be scanned. |
`unresolvedScope.widened` says whether matching was widened, and `.message` explains why. `strict` mode treats unresolved scope as a failure: `passed` is `false`, so it throws `SensitiveReferenceError` (`rule: "UNRESOLVED_TABLE_SCOPE"` when no sensitive reference was found).
The check is heuristic, not a SQL parser — a review and enforcement aid, not a substitute for database-side column privileges.
### `schemaHasSensitiveIdentifiers(schema)`
[Section titled “schemaHasSensitiveIdentifiers(schema)”](#schemahassensitiveidentifiersschema)
`true` when the schema marks at least one table or column `sensitive`. Cheap pre-check for hosts that want to skip the guardrail entirely on schemas with no markers — `ask()` uses it for exactly that, which is why `result.sensitiveGuardrail` is absent on unmarked schemas.
### `formatSensitiveReference(ref)`
[Section titled “formatSensitiveReference(ref)”](#formatsensitivereferenceref)
Renders a `SensitiveReference` as `schema.table.column` (or `table.column` when the artifact has no namespace). Used for the CLI warning and the `askdb.pipeline.sensitive_sql_warning` log field.
***
## Schema loading
[Section titled “Schema loading”](#schema-loading)
### `loadSchema(path)`
[Section titled “loadSchema(path)”](#loadschemapath)
```ts
import { loadSchema } from "@askdb/core";
const schema = loadSchema("./my-app.schema"); // synchronous
```
Autodetects and loads a v2 schema artifact. Accepts:
* A **schema directory** (`.schema/`) — the output of `askdb introspect`
* A **bundled JSON file** (`*.bundle.json` or any JSON with `bundled: true`) — the output of `askdb bundle`
* A direct path to a `schema.json` file. This loads the enclosing directory, so sibling `tables/*.md`, `concepts.md`, and `tenant-policy.md` apply just as they do for the directory path.
Returns `NormalizedSchemaV2`. Throws `SchemaParseError` on failure. The optional files (`tables/*.md`, `concepts.md`, `tenant-policy.md`) may be absent. If one exists but is empty or cannot be read or parsed, for example because of malformed YAML front-matter, loading throws. Bundles follow the same rule: only an absent `tenantPolicy` key means “no policy”. A broken `tenant-policy.md` never silently turns tenant enforcement off.
Each table and column in the result has one effective `sensitive` flag. It is `true` when `schema.json` marks it sensitive, when its `tables/*.md` front-matter sets `sensitive: true` (which is what Studio’s Sensitivity tab writes), or, for a column, when its table is sensitive. Front-matter is escalate-only: a front-matter `sensitive: false` never un-marks something that is sensitive anyway. It is ignored and reported in `schema.warnings` as `{ kind: "sensitivity_downgrade_ignored", tableFile, id }`. A `columns` entry whose ID belongs to a different table than the file it is in is reported as `{ kind: "misplaced_column_id", tableFile, id, tableId }`. Its `sensitive: true` still applies to the column the ID names, but nothing else in the entry does. A column ID listed more than once in the same file is reported as `{ kind: "duplicate_column_id", tableFile, id }`. Only the first entry’s description, aliases, and enum are used, but the column is sensitive if any entry naming it, in any `tables/*.md` file, sets `sensitive: true`. Two `tables/*.md` files with the same front-matter `id` make `loadSchema()` and `loadSchemaFromJson()` throw `SchemaParseError` naming both files. `tableFile` is always the markdown file that was actually read. Prompt formatting, `validateSensitiveReferences`, and `@askdb/rag` chunking all read this effective flag.
`loadSchema` is synchronous — load once at startup and keep the result in memory, not per request.
### `loadSchemaFromJson(raw)`
[Section titled “loadSchemaFromJson(raw)”](#loadschemafromjsonraw)
```ts
import { loadSchemaFromJson } from "@askdb/core";
const schema = loadSchemaFromJson(bundleJsonString);
```
Parses a raw JSON string. Accepts the same formats as `loadSchema` (bundled JSON or bare `schema.json` blob). Useful when the schema is passed as a string over a network boundary (e.g., the HTTP API’s `schemaJson` request field).
### `findMentionedNames(text, names)`
[Section titled “findMentionedNames(text, names)”](#findmentionednamestext-names)
```ts
import { findMentionedNames } from "@askdb/core";
findMentionedNames("Dedupe by EMAIL; see users_email", ["email", "ssn"]); // → ["email"]
```
Returns the names `text` mentions, in the order given: a whole-word, case-insensitive match whose ends may not touch a letter, digit, or `_` of any script (`email` isn’t mentioned by `emailed` or `user_email`; a name wrapped in backticks or quotes is). This is the schema contract’s “mentions a sensitive column by name” rule: `@askdb/rag`’s chunker and `@askdb/enrich`’s authoring warning both use it.
***
## Dialects
[Section titled “Dialects”](#dialects)
The `dialect` option accepts three forms:
### Built-in dialect id
[Section titled “Built-in dialect id”](#built-in-dialect-id)
```ts
dialect: "postgres" // or "mysql" | "sqlite" | "sqlserver" | "cockroachdb" | "mariadb"
```
| Id | Engine |
| --------------- | ------------------------------------------------------------------------------------------------- |
| `"postgres"` | PostgreSQL — `"` quotes, `ILIKE`, `::type` cast, `NOW()`, `\|\|` concat |
| `"cockroachdb"` | CockroachDB — PostgreSQL-wire-compatible; reuses the Postgres prompt |
| `"mysql"` | MySQL — `` ` `` quotes, `CONCAT()`, `LIKE`, `CAST()`, `NOW()` |
| `"mariadb"` | MariaDB — MySQL-protocol-compatible; reuses the MySQL prompt |
| `"sqlite"` | SQLite — dynamic typing, `LIKE`, `date('now')`, `\|\|` concat, `LIMIT` |
| `"sqlserver"` | SQL Server (T-SQL) — `[bracket]` or `"` quotes, `GETDATE()`, `+`/`CONCAT()`, `CAST()`/`CONVERT()` |
The engine adapter packages (`@askdb/postgres`, `@askdb/mysql`, etc.) export convenience dialect constants (`POSTGRES_DIALECT`, `MYSQL_DIALECT`, …), but passing the string id to `ask()` is sufficient — you don’t need to install the engine adapter just for SQL generation.
### `DialectSpec`
[Section titled “DialectSpec”](#dialectspec)
Customize how one of the built-in dialects prompts and validates — for example, a PostgreSQL-compatible warehouse that needs extra guidance in the prompt or extra forbidden keywords. `id` must be one of the six built-in ids (the spec describes a variant of that engine family, not a brand-new engine — for that, use [`AskDialect`](#askdialect)).
```ts
import { type DialectSpec } from "@askdb/core";
const redshiftFlavor: DialectSpec = {
id: "postgres", // the built-in family this variant belongs to
displayName: "Amazon Redshift",
promptBrief: "Amazon Redshift SQL. PostgreSQL syntax with some differences: ...",
identifierQuote: '"',
extraForbiddenKeywords: ["COPY", "UNLOAD"],
extraValidate(sql) {
// throw SqlValidationError for dialect-specific rules
},
};
```
| Field | Type | Required | Description |
| ------------------------ | ----------------------- | -------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `id` | `DialectId` | yes | One of the six built-in ids — the engine family this spec belongs to. |
| `displayName` | `string` | yes | Human-readable name. |
| `promptBrief` | `string` | yes | One-paragraph guidance for the model about this dialect’s syntax. |
| `identifierQuote` | `'"' \| '`’\` | yes | Identifier quoting style. |
| `unqualifiedNamespace` | `string` | no | A namespace that isn’t a schema in this engine. When it is the schema’s only namespace, the prompt lists its tables without it and tells the model never to write `.`; next to other namespaces (a MySQL database list that includes a database named `public`) it stays qualified. The SQLite, MySQL and MariaDB specs set `SINGLE_NAMESPACE_LABEL` (`"public"`), the namespace their connectors give the database’s tables; spread one to keep it. |
| `extraForbiddenKeywords` | `readonly string[]` | no | Keywords to forbid in addition to the shared read-only denylist. |
| `blockedFunctions` | `readonly string[]` | no | Functions `validateSelectSql` rejects when called (`name(`), such as `pg_sleep` or `load_file`. |
| `extraValidate` | `(sql: string) => void` | no | Dialect-specific SQL validator. Throw `SqlValidationError` for failures. |
| `backslashEscapes` | `boolean` | no | Whether a backslash escapes a quote inside `'…'` strings on your server. The built-in specs set the engine default (`true` for MySQL and MariaDB, `false` otherwise). Set `false` for MySQL or MariaDB with `NO_BACKSLASH_ESCAPES`, and `true` for Postgres with `standard_conforming_strings = off`. The checks lex strings this way, and bound tenant and parameter values are escaped to match. See [Match your server’s string settings](/concepts/safety-boundaries/#match-your-servers-string-settings). |
`id` also selects how the validator lexes strings, quoted identifiers, and comments. The built-in specs ship their own `extraForbiddenKeywords` and `blockedFunctions`; spread one (`{ ...POSTGRES_DIALECT, … }`) to keep them, since setting either field replaces the built-in list. These checks are defense in depth — run generated SQL under a read-only database role.
### `AskDialect`
[Section titled “AskDialect”](#askdialect)
Full escape hatch for custom NL→SQL generators — agentic flows, tool-calling, fine-tuned models, non-SELECT targets. 95 % of consumers should use a built-in id or `DialectSpec` instead.
```ts
import { type AskDialect } from "@askdb/core";
const myDialect: AskDialect = {
async generate(question, schema, model, options) {
// call your own generation logic
return { sql: "SELECT ...", usage: { promptTokens: 100, completionTokens: 20, totalTokens: 120 } };
},
};
```
The `generate` method receives:
* `question: string`
* `schema: AnyNormalizedSchema`
* `model: AskDbLanguageModel`
* `options?: AskDialectGenerateOptions` — `{ logger, explain, omitSensitiveIdentifiersFromNlToSqlPrompt, generateText, prebuiltDdl, tenantPolicy, tenantScope }`. `tenantScope` is the scope after `ask()` expands a `subtree`: a `multi_root` scope with one entry per covered root, where a root the resolver returned no IDs for has `ids: []`. `validateTenantScope()` accepts it.
It must return `AskDialectGenerateResult`:
| Field | Type | Description |
| ----------------- | ------------------------------------ | -------------------------------------------------------------------------------------------------------------------- |
| `sql` | `string` | The generated SQL. |
| `explain` | `unknown \| undefined` | Guardrail metadata when `options.explain` is true. |
| `tenantGuardrail` | `TenantGuardrailResult \| undefined` | Optional extra tenant findings from your generator. These are merged into `ask()`’s own check and cannot replace it. |
| `usage` | `AskUsage \| undefined` | Token usage, if your generator has access to it. |
A custom `AskDialect` is responsible for its own read-only validation. `ask()` does not run the SELECT-only validator on its output. If your generator should only emit read-only SQL, call `validateSelectSql(spec, sql)` before returning. Tenant enforcement is different: when the schema has a tenant policy, `ask()` runs the tenant guardrail on the returned `sql` (and its `sql-unbound` block), with the `:tenant__ids` placeholders still in place, and then substitutes them, whatever the dialect. Under `strict`, SQL that fails the tenant check throws `TenantGuardrailError`; passing it doesn’t prove the SQL is scoped. A custom `AskDialect` doesn’t tell the guardrail how its engine quotes strings, so the statement must pass under the standard-SQL, Postgres (`E'…'` escape strings), and MySQL (where `"…"` is a string) readings: a tenant column written only as `"agency_id"` doesn’t count as a predicate.
Passing an unknown string dialect id throws `UnknownDialectError`, which extends `AskDbError`.
***
## Modes
[Section titled “Modes”](#modes-1)
`AskDbModeV1` controls which post-generation guardrails are active.
| Value | Description |
| ------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `"schema_only"` (default) | Schema-grounding only. The model sees the DDL; no post-execute paths are activated. Use this for all production read-only queries. |
| `"bounded_results"` | Reserved for a future post-execute extension (summarizing bounded tabular results through the model). Today it produces exactly the same SQL as `schema_only` — see [Modes and dialects](/concepts/modes-and-dialects/). |
```ts
import { DEFAULT_ASKDB_MODE, parseAskDbModeV1 } from "@askdb/core";
const mode = parseAskDbModeV1(process.env.ASKDB_MODE); // throws on invalid values
```
***
## Logging
[Section titled “Logging”](#logging)
### `createAskDbLogger(options)`
[Section titled “createAskDbLogger(options)”](#createaskdbloggeroptions)
```ts
import { createAskDbLogger } from "@askdb/core";
const logger = createAskDbLogger({
correlationId: requestId,
level: "info",
logFile: "./logs/askdb.json",
});
```
Returns an `AskDbLogger` that emits structured JSON for each pipeline stage. Pass it to `ask()` via `options.logger`.
| Option | Type | Required | Default | Description |
| --------------- | --------------- | -------- | ---------- | ---------------------------------------------------------------------------- |
| `correlationId` | `string` | yes | — | Attached to every log line. Pass the request id. |
| `level` | `AskDbLogLevel` | no | `"silent"` | Pino log level. `"silent"` suppresses all output. |
| `logFile` | `string` | no | — | Append JSON logs to this path. Parent directories are created automatically. |
| `logStdout` | `boolean` | no | `false` | Duplicate logs to stdout in addition to stderr/file. |
**`AskDbLogLevel`:** `"fatal"` | `"error"` | `"warn"` | `"info"` | `"debug"` | `"trace"` | `"silent"`
The emitted log events are typed as `AskDbLogEvent` constants (e.g. `PipelineMode`, `PipelineGenerateStart`, `TenantScopeValidated`). Import `AskDbLogEvent` from `@askdb/core` to filter logs by event kind.
***
## Tenant types
[Section titled “Tenant types”](#tenant-types)
These types are needed when your schema has a tenant policy. See the [multi-tenancy guide](/guides/multi-tenancy/) for the full workflow.
### `TenantSqlOutputMode`
[Section titled “TenantSqlOutputMode”](#tenantsqloutputmode)
* `"sql-only"` — inlines literal tenant values directly in the SQL string
* `"sql-params"` — converts tenant values to positional `$N` parameters; use with parameterized queries
### `TenantBinding`
[Section titled “TenantBinding”](#tenantbinding)
```ts
type TenantBinding = {
placeholder: string; // e.g. ":tenant_org_ids"
rootLabel: string; // domain label (e.g. "organization")
rootId: string; // tenant root id
ids: string[]; // resolved id values
};
```
### `placeholderForTenantRoot(root)`
[Section titled “placeholderForTenantRoot(root)”](#placeholderfortenantrootroot)
```ts
import { placeholderForTenantRoot } from "@askdb/core";
placeholderForTenantRoot({ id: "table:public.sub_agencies", label: "Sub-Agency" }); // ":tenant_sub_agency_ids"
placeholderForTenantRoot({ id: "table:public.clients", label: "Клиент" }); // ":tenant_clients_ids"
```
Returns the `:tenant__ids` placeholder for a tenant root: the one the prompt names, `ask()` and `resolveTenantSql()` bind, and the tenant guardrail checks. `` is the label lowercased, with every run of characters other than ASCII letters and digits replaced by `_`. A label with no ASCII letter or digit uses the root’s table name instead. Pass a root from `schema.tenantPolicy.roots` (anything with `id` and `label`).
`placeholderForRoot(label)` is deprecated. It takes the label alone, so for a label with no ASCII letter or digit it returns `:tenant___ids`, which core doesn’t bind. For every other label the two agree.
### `TenantScope`
[Section titled “TenantScope”](#tenantscope)
Passed as `options.tenantScope` to `ask()`. Carries enforceable access plus optional advisory context.
```ts
// IDs access — user can see records for their specific org ids
const scope: TenantScope = {
access: {
kind: "ids",
tenantRoot: "table:public.organizations", // stable table ID from the policy
ids: ["org-1", "org-2"],
},
context: { role: "regional_manager", label: "Jane Smith" },
};
// Global / super access
const adminScope: TenantScope = {
access: { kind: "global", reason: "support investigation" },
};
```
Access kinds:
| Kind | Description |
| -------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `"ids"` | User can access specific root-entity ids. |
| `"subtree"` | User can access a subtree rooted at specific ids, including descendant roots. Requires the `resolveTenantDescendants` option on `ask()`, which returns IDs per root; `ask()` expands the scope to `"multi_root"` before generation. |
| `"multi_root"` | User has access across multiple tenant roots, each with their own id set. An entry’s `ids` may be empty (a covered root with no IDs, which fails closed if read); at least one entry needs an ID. |
| `"global"` | Super / admin access. Requires a `reason` string for audit. |
***
## Read next
[Section titled “Read next”](#read-next)
[**@askdb/client API**Config-driven facade — `createAskDb()` and per-call overrides.](/reference/client-api/)[**@askdb/rag API**`buildSchemaIndex()`, embedders, and vector stores.](/reference/rag-api/)[**Embed in a Node app**End-to-end code walkthrough using these APIs.](/guides/embed-in-node/)[**Multi-tenancy guide**Tenant scope, policy authoring, and SQL output modes.](/guides/multi-tenancy/)
# HTTP API reference
> Endpoints, request and response shapes, error codes, and configuration for @askdb/http-api.
Reference · HTTP API
`@askdb/http-api` is a thin HTTP wrapper around the same `ask()` pipeline as the library. Two endpoints, JSON over HTTP, designed to sit behind your own gateway.
## Server
[Section titled “Server”](#server)
```ts
import { createAskDbHttpServer } from "@askdb/http-api";
const server = createAskDbHttpServer({
port: 3000,
host: "127.0.0.1",
maxBodyBytes: 1024 * 1024,
});
server.listen();
```
| Option | Default | Description |
| -------------- | ----------------- | ---------------------------------------------------------------------------------------------- |
| `port` | `3000` | Port to listen on. Config fallback: `httpApi.listen.port`. |
| `host` | `127.0.0.1` | Bind address. Bind to `0.0.0.0` only behind a gateway. Config fallback: `httpApi.listen.host`. |
| `schemaPath` | — | Server-default schema artifact path. Falls back to `host.schemaPath` in `askdb.config.ts`. |
| `maxBodyBytes` | `1048576` (1 MiB) | Request body size limit. Larger requests return `payload_too_large`. |
The server reads its schema and AI provider settings from `askdb.config.ts` via `@askdb/config` — see [Configuration](/reference/config/) for the resolution rules.
## Standalone binary
[Section titled “Standalone binary”](#standalone-binary)
The package also ships an `askdb-http` binary, so you can run the service without writing any server code:
```bash
npx askdb-http --schema-path ./my-app.schema --port 3000 --host 127.0.0.1
```
| Flag | Description |
| ---------------------- | ------------------------------------ |
| `--schema-path ` | Server-default schema artifact path. |
| `--port ` | Port to listen on. |
| `--host ` | Bind address. |
Every flag is optional. Precedence per setting: CLI flag → `askdb.config.ts` (`host.schemaPath`, `httpApi.listen.port`, `httpApi.listen.host`) → built-in default.
## Endpoints
[Section titled “Endpoints”](#endpoints)
### `GET /health`
[Section titled “GET /health”](#get-health)
Liveness probe.
```bash
curl http://localhost:3000/health
```
```json
{ "ok": true }
```
### `POST /ask`
[Section titled “POST /ask”](#post-ask)
Generate SQL from a question.
**Request**
```json
{
"question": "How many customers signed up last week?",
"mode": "schema_only",
"explain": false,
"omitSensitiveFromPrompt": false,
"schemaJson": "{\"version\":2, \"schemaId\":\"...\", \"tables\":[...]}"
}
```
| Field | Required | Default | Description |
| ------------------------- | -------- | ------------- | ------------------------------------------------------------------------------------------ |
| `question` | yes | — | The natural-language question. |
| `mode` | no | `schema_only` | One of `schema_only`, `bounded_results`. |
| `explain` | no | `false` | Return heuristic guardrail metadata. |
| `omitSensitiveFromPrompt` | no | env-driven | Omit sensitive columns from the prompt. |
| `schemaJson` | no | config-driven | Inline schema artifact. Preferred: set `host.schemaPath` in `askdb.config.ts` server-side. |
**Success response (`200`)**
```json
{
"ok": true,
"correlationId": "01H…",
"sql": "SELECT count(*) FROM customers WHERE created_at >= …",
"explain": null,
"usage": {
"promptTokens": 1250,
"completionTokens": 45,
"totalTokens": 1295
}
}
```
| Field | Type | Notes |
| --------- | ---------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `sql` | `string` | The generated, checked SQL. |
| `explain` | `object \| null` | Heuristic guardrail metadata. Present (non-null) when `explain: true` was sent in the request. |
| `usage` | `object \| null` | Token counts for the generation call: `promptTokens`, `completionTokens`, `totalTokens` (each `number \| null`). `null` when the provider does not report usage. |
**Error response (`4xx` / `5xx`)**
```json
{
"ok": false,
"correlationId": "01H…",
"error": {
"code": "sql_validation_error",
"message": "Generated SQL contains a write statement.",
"rule": "read_only"
}
}
```
## Error codes
[Section titled “Error codes”](#error-codes)
| Code | HTTP | When |
| --------------------------- | ----- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `not_found` | `404` | Unknown route. |
| `bad_request` | `400` | Malformed JSON or missing required fields. |
| `payload_too_large` | `413` | Body exceeds `maxBodyBytes`. |
| `schema_parse_error` | `400` | Inline `schemaJson` couldn’t be parsed. |
| `generation_not_configured` | `500` | No model provider configured server-side. |
| `sql_validation_error` | `400` | Model output failed the SQL checks (must start with `SELECT`/`WITH`, no `;`-separated second statement, no comments, no unterminated strings or quoted identifiers, no write or DDL keywords, no blocked side-effecting functions). |
| `sql_generation_error` | `502` | Model call failed (provider error, timeout). |
| `internal_error` | `500` | Anything else. |
## Correlation IDs
[Section titled “Correlation IDs”](#correlation-ids)
Every response includes a `correlationId`. The same ID is emitted in the server’s structured log events, so you can join HTTP requests to generated SQL and any errors.
To carry a correlation ID supplied by your gateway, send the `x-correlation-id` header on the request — the server uses it as-is if present, otherwise generates one.
```bash
curl -X POST http://localhost:3000/ask \
-H "content-type: application/json" \
-H "x-correlation-id: req_abc123" \
-d '{"question":"How many users?"}'
```
## What this server doesn’t do
[Section titled “What this server doesn’t do”](#what-this-server-doesnt-do)
* **No auth.** Put your gateway in front.
* **No TLS termination.** Use your ingress.
* **No rate limiting.** Same.
* **No database connection.** It returns SQL; execution is your caller’s responsibility.
See [Deploy as HTTP service](/guides/deploy-as-http-service/) for the production deployment pattern.
## Read next
[Section titled “Read next”](#read-next)
[**Deploy as HTTP service**The end-to-end deploy guide with curl and Python examples.](/guides/deploy-as-http-service/)[**Run safely in production**What your gateway service needs to enforce.](/guides/run-safely-in-prod/)[**Configuration**Environment variables the server reads at startup.](/reference/config/)
# Package reference
> Every @askdb/* package: purpose, when to install, and what it exports.
Reference · Packages
AskDB is a workspace of focused packages. Install the ones your use case needs. This page is the index — purpose, install, and key exports for each.
AI providers are built into `@askdb/ai`, which loads the matching AI SDK package (`@ai-sdk/openai`, `@ai-sdk/azure`, `@ai-sdk/google`, `@ai-sdk/anthropic`) on first use. `@askdb/client` sits above `@askdb/core` + `@askdb/ai` as the config-driven entry point.
## Core
[Section titled “Core”](#core)
### `@askdb/core`
[Section titled “@askdb/core”](#askdbcore)
The dialect-agnostic NL-to-SQL pipeline. Schema loading, prompt construction, validation, and tenant-scope handling all live here.
* npm
```bash
npm install @askdb/core ai
```
* pnpm
```bash
pnpm add @askdb/core ai
```
* yarn
```bash
yarn add @askdb/core ai
```
`ai` (the Vercel AI SDK) is a required **peer dependency** of `@askdb/core`, with the range `^6.0.0 || ^7.0.51` (AI SDK 6, or 7.0.51 and later). Your app owns its version: `ask()` receives a model your app constructs, so core uses your app’s `ai` instead of bundling its own — upgrading AskDB never forces an AI SDK upgrade on the rest of your app. Build the model with an AI SDK provider package (for example `@ai-sdk/openai`), or through the config-driven path (`@askdb/ai` and `@askdb/client`), which currently requires AI SDK 7.
Every package on this page that depends on `@askdb/core` also needs `ai` installed, even if you only introspect and never generate SQL. That covers `@askdb/client`, `@askdb/connectors`, the engine adapters, `@askdb/introspect`, `@askdb/prisma`, `@askdb/enrich` and `@askdb/rag`. Core loads `ai` when it is imported. npm 7+ and pnpm install the missing peer for you. Yarn doesn’t, so the install commands on this page list `ai` explicitly.
**Key exports**
| Symbol | Purpose |
| ------------------------------------------- | --------------------------------------------------------------------------------------- |
| `ask(options)` | The main pipeline. Returns checked SQL. See [full API reference](/reference/core-api/). |
| `loadSchema(path)` | Load a schema artifact from a directory, bundle, or `schema.json`. |
| `validateTenantScope` / `resolveTenantSql` | Tenant-scope validation and placeholder binding. |
| `createAskDbLogger` | Structured logger that emits AskDB log events. |
| `POSTGRES_DIALECT` and built-in dialect IDs | Dialect inputs accepted by `ask()`. |
| `AskDbLanguageModel` | AskDB’s public name for the AI SDK language model contract. |
| `AskUsage` | Token usage type returned in `AskPipelineResult`. |
See the **[@askdb/core API reference](/reference/core-api/)** for the full option and return-type documentation.
### `@askdb/client`
[Section titled “@askdb/client”](#askdbclient)
Config-aware facade over `@askdb/core`. `createAskDb()` resolves the schema, model, and dialect from your `askdb.config.*` (with every `@askdb/ai` built-in provider registered by default), so call sites pass only a question. Install it when you want the shortest config-driven path; skip it when you construct the model and load the schema yourself and call `ask()` directly.
* npm
```bash
npm install @askdb/client @askdb/core @askdb/config ai @ai-sdk/openai
```
* pnpm
```bash
pnpm add @askdb/client @askdb/core @askdb/config ai @ai-sdk/openai
```
* yarn
```bash
yarn add @askdb/client @askdb/core @askdb/config ai @ai-sdk/openai
```
**Key exports**
| Symbol | Purpose |
| ------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `createAskDb(options)` | Build a client bound to a config. Registers every built-in AI provider by default; `providers: ["openai"]` restricts the set, adapter objects add custom providers, or pass a prebuilt `registry`. Returns `{ ask, reload }`. Options include `unknownDialect: "throw" \| "fallback-postgres"` for artifacts recorded by an unrecognized provider. |
| `client.ask(question, overrides?)` | Resolve schema/model/dialect and run the pipeline. Overrides: `schema`, `model`, `dialect`, plus all `ask()` options. |
| `AskDbClient` / `CreateAskDbOptions` / `AskOverrides` | Types for the client, constructor options, and per-call overrides. |
| `SchemaLoadError` / `SchemaNotConfiguredError` / `ModelNotConfiguredError` / `DialectNotSupportedError` | Typed errors for the resolution steps — catch these to map failures to your own error handling. |
See the **[@askdb/client API reference](/reference/client-api/)** for the full option documentation.
### `@askdb/ai`
[Section titled “@askdb/ai”](#askdbai)
AI provider registry with built-in providers for OpenAI, Azure OpenAI / Microsoft Foundry, Google Gemini, Anthropic, and the Vercel AI Gateway. `@askdb/client` depends on it and builds the registry for you. Import it yourself to build a model object outside the client (`createAiRegistry().createLanguageModelFromEnv(...)`), to restrict or extend the provider set, or to share one registry across several clients.
* npm
```bash
npm install @askdb/ai ai
```
* pnpm
```bash
pnpm add @askdb/ai ai
```
* yarn
```bash
yarn add @askdb/ai ai
```
**Key exports**
| Symbol | Purpose |
| ------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `createAiRegistry(providers?)` | Build a registry and create language or embedding models from it. No argument: every built-in provider. Or pass built-in names (`["openai"]`) and/or `AiProviderAdapter` objects. |
| `BUILTIN_AI_PROVIDERS` | Table of built-in providers: names, aliases, env vars, default models, and the SDK package each needs. |
| `openaiProvider`, `azureProvider`, `googleProvider`, `anthropicProvider`, `gatewayProvider` | The built-in adapters, if you want to pass them as objects. |
| `registry.resolveAiConfig(env)` / `registry.resolveEmbeddingConfig(env)` | Resolve provider config from env without constructing a model. These are methods on the registry returned by `createAiRegistry`, not standalone exports. |
| `resolveBaseConfig` | Low-level helper — resolves a provider’s base config object from an env map. Used internally by adapters. |
| `withEmbeddingProviderOptions` | Wraps an embedding model so `dimensions`/`user` reach the provider; an optional mapper renames them to the provider’s own settings (e.g. Gemini’s `outputDimensionality`). Shared across adapters. |
| `aiKeyMissingMessage` | Shared human-readable missing-key guidance. |
### Provider SDKs
[Section titled “Provider SDKs”](#provider-sdks)
Each built-in provider loads its AI SDK package lazily. These packages are optional peer dependencies of `@askdb/ai`, so install the one for the provider your config selects. If it’s missing, model creation fails with `Provider '' requires the optional peer dependency @ai-sdk/. Install it: npm i @ai-sdk/`. `ai` itself is a required peer of `@askdb/ai`: npm and pnpm install it automatically, but depend on `ai` directly when you want to pin the version. AskDB raises its `ai` floor only when it needs a newer version or a security fix, and that release’s changelog says which.
Any 4.x release of each `@ai-sdk/*` package works (the peer range is `^4.0.0`), so AskDB doesn’t force a provider SDK upgrade. `@askdb/client` declares the same optional peers and passes them through to `@askdb/ai`, so with strict installs (Yarn Plug’n’Play) install the SDK in the package that depends on `@askdb/client` or `@askdb/ai`, as the install lines above do. Under Plug’n’Play the AI SDK also needs `zod` installed next to it (its own peer dependency). If you bundle your app, esbuild builds without the SDKs you didn’t install, and a missing one fails only when its provider first builds a model. webpack 5 stops with `Module not found` for each missing `@ai-sdk/*` package, even when you only use a deprecated `@askdb/ai-*` package: install them, or list the ones you don’t use in `externals` (with ESM output, use `externalsType: "module"` and the bare package names):
```js
// webpack.config.js: list the @ai-sdk/* packages you don't install.
module.exports = {
// ...
externals: {
"@ai-sdk/anthropic": "commonjs @ai-sdk/anthropic",
"@ai-sdk/azure": "commonjs @ai-sdk/azure",
"@ai-sdk/google": "commonjs @ai-sdk/google",
},
};
```
* OpenAI
* npm
```bash
npm install @ai-sdk/openai
```
* pnpm
```bash
pnpm add @ai-sdk/openai
```
* yarn
```bash
yarn add @ai-sdk/openai
```
* Anthropic
```bash
npm install @ai-sdk/openai
```
* Google
```bash
pnpm add @ai-sdk/openai
```
* Azure OpenAI
```bash
yarn add @ai-sdk/openai
```
* Vercel AI Gateway
* npm
```bash
npm install @ai-sdk/anthropic
```
* pnpm
```bash
pnpm add @ai-sdk/anthropic
```
* yarn
```bash
yarn add @ai-sdk/anthropic
```
* npm
```bash
npm install @ai-sdk/anthropic
```
* pnpm
```bash
pnpm add @ai-sdk/anthropic
```
* yarn
```bash
yarn add @ai-sdk/anthropic
```
* npm
* npm
```bash
npm install @ai-sdk/google
```
* pnpm
```bash
pnpm add @ai-sdk/google
```
* yarn
```bash
yarn add @ai-sdk/google
```
* pnpm
```bash
npm install @ai-sdk/google
```
* yarn
```bash
pnpm add @ai-sdk/google
```
* npm
```bash
yarn add @ai-sdk/google
```
* pnpm
* npm
```bash
npm install @ai-sdk/azure
```
* pnpm
```bash
pnpm add @ai-sdk/azure
```
* yarn
```bash
yarn add @ai-sdk/azure
```
* yarn
```bash
npm install @ai-sdk/azure
```
* npm
```bash
pnpm add @ai-sdk/azure
```
* pnpm
```bash
yarn add @ai-sdk/azure
```
* yarn
Nothing extra: the gateway provider ships with `ai`.
The CLI, Studio, and the HTTP API already include all four SDKs. Unknown `ai.provider` values require a registered adapter. The built-ins are `openai`, `azure` (aliases `azure-openai`, `foundry`), `google`, `anthropic`, and `gateway`. For anything else, embed AskDB and pass your own `AiProviderAdapter` to `createAiRegistry()` or `createAskDb({ providers })`, or use an OpenAI-compatible endpoint via the `openai` provider and a custom base URL.
The `@askdb/ai-openai`, `@askdb/ai-azure`, `@askdb/ai-google`, and `@askdb/ai-anthropic` packages are **deprecated**. They re-export the built-in adapters from `@askdb/ai` and will be removed before 1.0 ([#347](https://github.com/Ygilany/AskDB/issues/347)).
### `@askdb/connectors`
[Section titled “@askdb/connectors”](#askdbconnectors)
Connector provider registry — mirrors the `@askdb/ai` pattern for introspection. Each engine adapter exports a `ConnectorProviderAdapter` constant; `@askdb/connectors` wires them into a unified registry used by the CLI and apps. Install directly only when you are building a custom introspection flow.
* npm
```bash
npm install @askdb/connectors ai
```
* pnpm
```bash
pnpm add @askdb/connectors ai
```
* yarn
```bash
yarn add @askdb/connectors ai
```
**Key exports**
| Symbol | Purpose |
| ----------------------------------- | ------------------------------------------------------------------------------ |
| `createConnectorRegistry(adapters)` | Build a registry from a set of provider adapters. |
| `ConnectorRegistry` | Registry type — `createConnector(provider, config)`, `getTemplates(provider)`. |
| `ConnectorProviderAdapter` | The adapter shape each engine package exports. |
### `@askdb/config`
[Section titled “@askdb/config”](#askdbconfig)
Optional config bootstrap: `.env` and `askdb.config.*` discovery, type-safe `defineConfig`, and a runtime snapshot accessor.
* npm
```bash
npm install @askdb/config
```
* pnpm
```bash
pnpm add @askdb/config
```
* yarn
```bash
yarn add @askdb/config
```
**Key exports**
| Symbol | Purpose |
| ---------------------------- | --------------------------------------------------------------------------------------------- |
| `defineConfig(config)` | Type-safe config builder. |
| `bootstrapAskDbEnv(options)` | Load `.env` + `askdb.config.*` and install the runtime snapshot. |
| `getAskDbRuntimeConfig()` | Read the runtime snapshot (preferred over `process.env`). |
| `discoverAskDbConfigPath()` | Programmatic config-file discovery. |
| `env`, `requiredEnv` | Typed env-var accessors. |
| `isAskDbDebugEnabled()` | `true` when the `ASKDB_DEBUG` shell variable is `1` or `true`; works without a loaded config. |
For tools that write a new `askdb.config.ts`, the `@askdb/config/scaffold` entry point exports `renderAskDbAiConfigScaffold(input)`. It renders the config’s `ai` block (the provider connection in `ai.providerConfig`, plus `ai.language.model` read from an env var when one is given) and lists the env vars that block reads. `askdb init` and Studio’s setup wizard use it. Your own `askdb.config.ts` never needs it.
## Engine adapters
[Section titled “Engine adapters”](#engine-adapters)
Each engine package ships the introspection connector for its engine, any catalog SQL templates, and a re-export of that engine’s dialect constant. The dialect specs themselves (SQL generation + validation rules) live in `@askdb/core` — `ask()` needs only the dialect id, no engine package.
### `@askdb/postgres`
[Section titled “@askdb/postgres”](#askdbpostgres)
* npm
```bash
npm install @askdb/postgres ai
```
* pnpm
```bash
pnpm add @askdb/postgres ai
```
* yarn
```bash
yarn add @askdb/postgres ai
```
PostgreSQL dialect, connector, catalog SQL templates, and an optional `pg`-based catalog query runner for live introspection. Pass `dialect: "postgres"` to `ask()`.
### `@askdb/mysql`
[Section titled “@askdb/mysql”](#askdbmysql)
* npm
```bash
npm install @askdb/mysql ai
```
* pnpm
```bash
pnpm add @askdb/mysql ai
```
* yarn
```bash
yarn add @askdb/mysql ai
```
MySQL dialect, connector, catalog SQL templates, and an optional `mysql2`-based catalog query runner for live introspection. Pass `dialect: "mysql"` to `ask()`.
### `@askdb/sqlite`
[Section titled “@askdb/sqlite”](#askdbsqlite)
* npm
```bash
npm install @askdb/sqlite ai
```
* pnpm
```bash
pnpm add @askdb/sqlite ai
```
* yarn
```bash
yarn add @askdb/sqlite ai
```
SQLite dialect, connector, catalog SQL templates, and an optional `better-sqlite3`-based catalog query runner for live introspection. Works with embedded file-backed databases. Pass `dialect: "sqlite"` to `ask()`.
### `@askdb/sqlserver`
[Section titled “@askdb/sqlserver”](#askdbsqlserver)
* npm
```bash
npm install @askdb/sqlserver ai
```
* pnpm
```bash
pnpm add @askdb/sqlserver ai
```
* yarn
```bash
yarn add @askdb/sqlserver ai
```
SQL Server (T-SQL) dialect, connector, catalog SQL templates, and an optional `mssql`-based catalog query runner for live introspection. Pass `dialect: "sqlserver"` to `ask()`.
## Introspection
[Section titled “Introspection”](#introspection)
### `@askdb/introspect`
[Section titled “@askdb/introspect”](#askdbintrospect)
The engine-agnostic introspection contract and the schema-directory writer. Use directly only when you’re calling introspection from your own code — the CLI wraps this for you.
* npm
```bash
npm install @askdb/introspect ai
```
* pnpm
```bash
pnpm add @askdb/introspect ai
```
* yarn
```bash
yarn add @askdb/introspect ai
```
### `@askdb/prisma`
[Section titled “@askdb/prisma”](#askdbprisma)
File-only connector that reads `.prisma` schema files and produces AskDB physical metadata — no live database needed. Pair with an engine adapter for SQL generation at runtime.
* npm
```bash
npm install @askdb/prisma @askdb/introspect ai
```
* pnpm
```bash
pnpm add @askdb/prisma @askdb/introspect ai
```
* yarn
```bash
yarn add @askdb/prisma @askdb/introspect ai
```
See [the Prisma integration guide](/guides/integrations/prisma/).
## Authoring
[Section titled “Authoring”](#authoring)
### `@askdb/studio`
[Section titled “@askdb/studio”](#askdbstudio)
Browser-based schema-authoring UI. The CLI’s `askdb studio` command lazy-imports this package. Schema browsing, enrichment, and SQL generation do not require a database driver. The Query Playground’s live execute feature supports Postgres, MySQL, SQLite, and SQL Server — each requires its own optional peer driver package.
* npm
```bash
npm install @askdb/studio
```
* pnpm
```bash
pnpm add @askdb/studio
```
* yarn
```bash
yarn add @askdb/studio
```
| Execute provider | Package |
| ---------------- | -------------------------------- |
| Postgres | `pg` (optional peer) |
| MySQL | `mysql2` (optional peer) |
| SQLite | `better-sqlite3` (optional peer) |
| SQL Server | `mssql` (optional peer) |
Install only the package for your dialect. The execute provider is inferred from your active introspection provider unless overridden with `studio.execute.provider`.
`@askdb/studio` lists all four packages as dev dependencies for local package development and CI type-checking. This is not a requirement for your application — only install the driver you need at runtime.
See [Studio — driver packages](/studio/#driver-packages) and [Configuration reference — Studio execute](/reference/config/#studio-execute-configuration) for setup details.
### `@askdb/enrich`
[Section titled “@askdb/enrich”](#askdbenrich)
Headless schema-authoring helpers used by Studio. Use directly when building a custom authoring surface.
* npm
```bash
npm install @askdb/enrich ai
```
* pnpm
```bash
pnpm add @askdb/enrich ai
```
* yarn
```bash
yarn add @askdb/enrich ai
```
## Retrieval
[Section titled “Retrieval”](#retrieval)
### `@askdb/rag`
[Section titled “@askdb/rag”](#askdbrag)
Chunks the schema artifact, indexes it in a vector store, and retrieves relevant chunks per question. Use with `ask()`’s `retriever` option for large schemas. Always install `ai`: `@askdb/rag` depends on `@askdb/core`, which loads `ai` when it is imported, even with a custom embedder or the in-memory or file store. Install `@ai-sdk/openai` and `pg` only if your embedder and vector store use them; they are optional peers. Their AI SDK 7 floors (`ai` `^7.0.51`, `@ai-sdk/openai` `^4.0.29`) move the same way as the adapters’ `ai` floor; the AI SDK 6 floors (`^6.0.0`, `^3.0.0`) move only on purpose, with the AI SDK 6 install smoke’s pins.
* npm
```bash
npm install @askdb/rag ai
```
* pnpm
```bash
pnpm add @askdb/rag ai
```
* yarn
```bash
yarn add @askdb/rag ai
```
**Key exports**
| Symbol | Purpose |
| -------------------------------------------------------------- | ----------------------------------------------------------------------------------------- |
| `buildSchemaIndex({ schema, store, embedder, ... })` | Chunk + embed + upsert a schema artifact; returns `{ retriever, stats, chunks }`. |
| `createAiSdkEmbedder({ model })` / `createOpenAiEmbedder(...)` | Wrap an AI SDK embedding model (or raw OpenAI) as the `embedder`. |
| `createRetriever({ store, embedder })` | Build the retriever passed to `ask()`. |
| `createPgvectorStore` | The pgvector store factory. |
| `detectEmbeddingDimensions(embedder)` | Learn an embedder’s vector width with one short embedding call, for a new pgvector table. |
| `loadChunkerSourcesFromDir(path)` | Load a schema directory into chunker format (includes markdown). |
Ships a small CLI binary `askdb-rag` with three commands — `index`, `query`, and `setup-store` (pgvector provisioning). See [CLI reference — the askdb-rag binary](/reference/cli/#the-askdb-rag-binary) and [RAG for large schemas](/guides/rag-for-large-schemas/).
See the **[@askdb/rag API reference](/reference/rag-api/)** for the full option and type documentation.
## Service surfaces
[Section titled “Service surfaces”](#service-surfaces)
### `@askdb/http-api`
[Section titled “@askdb/http-api”](#askdbhttp-api)
Minimal HTTP server wrapping `ask()`. Two endpoints (`/health`, `POST /ask`), designed to sit behind your gateway.
* npm
```bash
npm install @askdb/http-api
```
* pnpm
```bash
pnpm add @askdb/http-api
```
* yarn
```bash
yarn add @askdb/http-api
```
**Key exports**
| Symbol | Purpose |
| -------------------------------------------------------------------- | --------------------------- |
| `createAskDbHttpServer(options)` | Build the server. |
| `AskHttpRequest` / `AskHttpSuccessResponse` / `AskHttpErrorResponse` | Request and response types. |
See [the HTTP API reference](/reference/http-api/) for endpoints and error codes.
### `askdb` (CLI)
[Section titled “askdb (CLI)”](#askdb-cli)
The `askdb` binary. Ships as a normal npm package — install for local development, demos, and CI.
* npm
```bash
npm install askdb
```
* pnpm
```bash
pnpm add askdb
```
* yarn
```bash
yarn add askdb
```
See [the CLI reference](/reference/cli/).
## Dependency direction
[Section titled “Dependency direction”](#dependency-direction)
| Package | Depends on |
| --------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------- |
| `@askdb/core` | AI SDK core package (`ai`, AI SDK 6 or 7) as a required peer |
| `@askdb/postgres`, `@askdb/mysql`, `@askdb/sqlite`, `@askdb/sqlserver` | `@askdb/core`, `@askdb/connectors` |
| `@askdb/prisma` | `@askdb/introspect`, `@askdb/connectors` |
| `@askdb/connectors` | `@askdb/introspect` |
| `@askdb/ai` | AI SDK core package (`ai`); `@ai-sdk/*` provider packages as optional peers |
| `@askdb/ai-openai`, `@askdb/ai-azure`, `@askdb/ai-google`, `@askdb/ai-anthropic` (deprecated) | `@askdb/ai` + the matching AI SDK provider package |
| `@askdb/enrich`, `@askdb/rag` | `@askdb/core` |
| `@askdb/studio` | `@askdb/enrich` (+ `@askdb/rag` when used) |
| `@askdb/http-api` | `@askdb/core` (+ engine adapter) |
| `askdb` (CLI) | All of the above (lazy-imported per command) |
Reusable packages stay small and layered. First-party surfaces (CLI, Studio, HTTP API) compose them.
## What to install — by use case
[Section titled “What to install — by use case”](#what-to-install--by-use-case)
[**Just trying it out**`askdb` alone is enough to introspect, enrich, and ask from the CLI.](/quickstart/)[**Embedding in a Node service**`@askdb/client` + `@askdb/core` + `@askdb/config` + `ai` + an AI SDK provider package such as `@ai-sdk/openai`.](/guides/embed-in-node/)[**Standing up an HTTP service**Add `@askdb/http-api` on top of the embedding install.](/guides/deploy-as-http-service/)[**Working with a large schema**Add `@askdb/rag` and a vector store (pgvector recommended).](/guides/rag-for-large-schemas/)
## Read next
[Section titled “Read next”](#read-next)
[**@askdb/core API**Full `ask()` options, result fields, dialects, modes, and logging.](/reference/core-api/)[**@askdb/client API**`createAskDb()` and per-call overrides.](/reference/client-api/)[**@askdb/rag API**`buildSchemaIndex()`, embedders, and vector stores.](/reference/rag-api/)[**CLI reference**The askdb binary in detail.](/reference/cli/)[**HTTP API reference**Endpoints, request and response shapes.](/reference/http-api/)[**Configuration reference**defineConfig and the env-var matrix.](/reference/config/)
# @askdb/rag API reference
> Full API reference for @askdb/rag: buildSchemaIndex(), createRetriever(), embedders, vector stores, and chunking.
Reference · @askdb/rag
`@askdb/rag` chunks the schema artifact, embeds the chunks, stores them in a vector store, and retrieves relevant chunks per question. Pass the returned `retriever` to `ask()` to replace full-DDL prompts with focused context — essential for schemas above 30–50 tables.
See the [RAG for large schemas guide](/guides/rag-for-large-schemas/) for the end-to-end workflow.
## `buildSchemaIndex(options)`
[Section titled “buildSchemaIndex(options)”](#buildschemaindexoptions)
Chunks a schema artifact, embeds the chunks, upserts them into the vector store, and returns a bound retriever. Re-indexing is incremental: a chunk is skipped only when the store already holds, for its id, the hash of the same text embedded by the same embedder. Built-in stores report their hashes, so a lock file can’t make the indexer skip chunks a fresh or different store doesn’t have, and an interrupted embedder switch can’t leave another model’s vectors passing as current. For the memory store, which keeps nothing past the process, the lock file is neither read nor written.
```ts
import {
buildSchemaIndex,
createAiSdkEmbedder,
createPgvectorStore,
detectEmbeddingDimensions,
loadChunkerSourcesFromDir,
} from "@askdb/rag";
import { openai } from "@ai-sdk/openai";
const embedder = createAiSdkEmbedder({ model: openai.embedding("text-embedding-3-small") });
const store = createPgvectorStore({
connectionString: process.env.DATABASE_URL,
dimensions: await detectEmbeddingDimensions(embedder), // the width the model returns
});
await store.ensureSchema();
const { retriever, stats } = await buildSchemaIndex({
schema: loadChunkerSourcesFromDir("./my-app.schema"),
embedder,
store,
embedderId: "openai:text-embedding-3-small",
lockFilePath: "./my-app.schema/schema.lock.json",
});
console.log(`Indexed ${stats.chunksIndexed}, reused ${stats.chunksReused}`);
```
Pass `retriever` to `ask()`:
```ts
const { sql } = await ask({
question,
schema,
model,
dialect: "postgres",
retriever,
totalSchemaChunkCount: stats.chunksTotal,
});
```
### Options — `BuildSchemaIndexOptions`
[Section titled “Options — BuildSchemaIndexOptions”](#options--buildschemaindexoptions)
| Field | Type | Required | Description |
| --------------- | -------------------------------------- | -------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `schema` | `ChunkerSources \| NormalizedSchemaV2` | no† | Schema to index. Prefer `loadChunkerSourcesFromDir(path)` — it includes full table markdown, enabling richer chunks. Passing a bare `NormalizedSchemaV2` works but produces text-only chunks without markdown body. |
| `embedder` | `Embedder` | yes | Text embedding function: `(texts: string[]) => Promise`. Use `createAiSdkEmbedder()` or supply your own. |
| `store` | `VectorStore` | yes | Vector store adapter. Use `createPgvectorStore()` or supply a custom adapter. |
| `embedderId` | `string` | no | Stable identifier for the embedder (e.g. `"openai:text-embedding-3-small"`). Stored in the lock file. Changing it, including going from unset to set, triggers a full re-embed. Strongly recommended when using a lock file. |
| `lockFilePath` | `string` | no | Path to `schema.lock.json`. Records the embedder id, store identity, the width of the vectors written (`dimensions`), and chunk hashes. A missing lock, or one written by an older `@askdb/rag`, triggers a full re-embed. Write it inside the schema directory. |
| `force` | `boolean` | no | Re-embed every chunk regardless of the lock file or stored hashes. |
| `chunkOptions` | `ChunkOptions` | no | `includeSensitiveDescribable` (default `false`), `emitRelationships` (default `false`), `chunkSizeMaxChars` (default `1000`). |
| `batchSize` | `number` | no | Number of texts per embedder call. Default `64`. |
| `onProgress` | `(e: IndexProgressEvent) => void` | no | Called at `"started"`, `"embedded"`, and `"completed"` stages. |
| `logger` | `AskDbLogger` | no | Structured logger. |
| `correlationId` | `string` | no | Correlation id attached to log lines. |
†Either `schema` or the deprecated `sources` alias must be provided.
### Result — `BuildSchemaIndexResult`
[Section titled “Result — BuildSchemaIndexResult”](#result--buildschemaindexresult)
| Field | Type | Description |
| ------------------------- | ----------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `retriever` | `Retriever` | Bound to the store and embedder. Pass directly to `ask()`. |
| `stats.chunksTotal` | `number` | Total chunk count after indexing. Pass as `totalSchemaChunkCount` to `ask()`. |
| `stats.chunksIndexed` | `number` | Chunks newly embedded in this run. |
| `stats.chunksReused` | `number` | Chunks skipped because the store already held them with the same text and embedder. |
| `stats.sensitiveExcluded` | `number` | Chunks left out, plus chunks emitted with part of their describable text (a description, alias, primary entity, enum values, or note) dropped, because the content belongs to or mentions a sensitive table/column. A long source that would split into several chunks counts once per chunk. Exclusion is the default. |
| `stats.sensitiveIncluded` | `number` | Chunks whose sensitive describable content was embedded only because `chunkOptions.includeSensitiveDescribable: true` was set. Always `0` by default. |
| `chunks` | `Chunk[]` | Full chunk list sorted by id. Useful for diagnostics. |
### `IndexProgressEvent`
[Section titled “IndexProgressEvent”](#indexprogressevent)
```ts
type IndexProgressEvent =
| { kind: "started"; totalChunks: number; toEmbed: number; reused: number }
| { kind: "embedded"; embedded: number; total: number }
| { kind: "completed"; embedded: number; reused: number };
```
***
## `createRetriever(options)`
[Section titled “createRetriever(options)”](#createretrieveroptions)
Builds a retriever from an existing store and embedder **without re-indexing**. Use this in serving processes when the index was built by a separate job.
```ts
import { createRetriever } from "@askdb/rag";
const retriever = createRetriever({ embedder, store });
```
| Option | Type | Required | Description |
| --------------- | ------------- | -------- | ------------------------------------------------ |
| `embedder` | `Embedder` | yes | The same embedder used when the index was built. |
| `store` | `VectorStore` | yes | The store that holds the indexed chunks. |
| `logger` | `AskDbLogger` | no | Structured logger. |
| `correlationId` | `string` | no | Correlation id for log lines. |
### `checkIndexMatches(options)`
[Section titled “checkIndexMatches(options)”](#checkindexmatchesoptions)
Checks, before querying, that a persisted index was built with the embedder you’re about to query with. `askdb-rag query` applies the same rule.
```ts
import { checkIndexMatches, createRetriever } from "@askdb/rag";
const match = checkIndexMatches({
lockFilePath: "./my-app.schema/schema.lock.json",
schemaId: "my-app",
embedderId: "openai:text-embedding-3-small",
dimensions: 1536, // optional
});
if (!match.ok) throw new Error(match.message); // match.reason: "lock-outdated" | "index-incomplete" | "embedder-changed" | "dimensions-changed"
const retriever = createRetriever({ embedder, store });
```
The embedder id must equal the one the lock records, since equal widths don’t make two models’ vectors comparable: a lock with no embedder id matches only a query without one, as in `buildSchemaIndex`. When both widths are known they must match. A lock written by an older `@askdb/rag` doesn’t match until the index is rebuilt, and neither does a lock marked `incomplete` by a build that switched embedders and didn’t finish (the store then holds two models’ vectors). A missing or unreadable lock, or one for another schema id, has nothing to compare and returns `{ ok: true, lock: undefined }`.
***
## Embedders
[Section titled “Embedders”](#embedders)
### `createAiSdkEmbedder(options)`
[Section titled “createAiSdkEmbedder(options)”](#createaisdkembedderoptions)
Wraps any AI SDK `EmbeddingModel` as an `Embedder`.
```ts
import { createAiSdkEmbedder } from "@askdb/rag";
import { openai } from "@ai-sdk/openai";
const embedder = createAiSdkEmbedder({
model: openai.embedding("text-embedding-3-small"),
});
```
| Option | Type | Required | Description |
| ----------------- | ------------------------------------- | -------- | ------------------------------------------------------------------------------------------------------------------------------------------ |
| `model` | `EmbeddingModel` | yes | AI SDK text embedding model instance. |
| `maxRetries` | `number` | no | Max retries per batch call. Defaults to the AI SDK behavior. |
| `providerOptions` | `object` | no | Provider-specific options forwarded to the AI SDK call. |
| `onUsage` | `(usage: AiSdkEmbedderUsage) => void` | no | Called after each embedding batch with token counts. `AiSdkEmbedderUsage` has `tokens`, `promptTokens`, and `totalTokens` (each optional). |
### `createOpenAiEmbedder(options?)` *(deprecated)*
[Section titled “createOpenAiEmbedder(options?) (deprecated)”](#createopenaiembedderoptions-deprecated)
A convenience wrapper around the OpenAI embeddings API. **Deprecated** — construct the model with `openai.embedding(...)` and use `createAiSdkEmbedder` instead.
### `detectEmbeddingDimensions(embedder)`
[Section titled “detectEmbeddingDimensions(embedder)”](#detectembeddingdimensionsembedder)
Learns an embedder’s vector width by embedding one short text, so you don’t have to look it up or hard-code it. Use it when a store needs the width before the first vector is written, such as a new pgvector table. It costs one embedding call. The memory and file stores learn the width from the first vector themselves, so they don’t need it.
```ts
import { detectEmbeddingDimensions } from "@askdb/rag";
const dimensions = await detectEmbeddingDimensions(embedder); // e.g. 1536 for text-embedding-3-small
```
***
## Vector stores
[Section titled “Vector stores”](#vector-stores)
### `createPgvectorStore(options)`
[Section titled “createPgvectorStore(options)”](#createpgvectorstoreoptions)
PostgreSQL vector store backed by the `pgvector` extension. The recommended production store for AskDB.
```ts
import { createPgvectorStore } from "@askdb/rag";
const store = createPgvectorStore({
connectionString: process.env.DATABASE_URL,
dimensions: await detectEmbeddingDimensions(embedder), // the width your embedding model returns
table: "askdb_rag_chunks",
indexStrategy: "hnsw",
});
await store.ensureSchema(); // idempotent — safe to call on every startup
```
| Option | Type | Required | Description |
| ------------------ | ----------------------- | -------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `dimensions` | `number` | no | Width of the `embedding` column. Needed to create the table (`setupSql()`, or `ensureSchema()` when the table doesn’t exist yet). `upsert` rejects vectors of another width, checked against `dimensions` or, without it, the existing table’s width once `ensureSchema()` has read it. Take it from `detectEmbeddingDimensions(embedder)` rather than hard-coding it. |
| `connectionString` | `string` | no† | PostgreSQL connection string. The store lazily imports and pools `pg` when this is supplied. |
| `client` | `PgClient` | no† | Pre-built `pg.Pool` or `pg.Client`. Preferred when your app already manages a pool. The store never closes an externally supplied client. |
| `table` | `string` | no | Table name. Default `"askdb_rag_chunks"`. Several schemas can share one table (chunk ids are schema-scoped); use separate tables for different embedding dimensions. |
| `indexStrategy` | `PgvectorIndexStrategy` | no | Index type: `"hnsw"` (default, better recall), `"ivfflat"` (faster at very large scale), or `"none"` (sequential scan — for small tables or testing). |
| `resolveFrom` | `string` | no | Directory to resolve the optional `pg` peer from when it isn’t resolvable from `@askdb/rag` (e.g. running from an npx cache). Default `process.cwd()`. |
†Either `connectionString` or `client` is required.
**`PgClient`** interface (accepted by `client`):
```ts
{ query: (text: string, params?: unknown[]) => Promise<{ rows: unknown[] }> }
```
Any `pg.Pool` or `pg.Client` satisfies this.
### `PgvectorStore` methods
[Section titled “PgvectorStore methods”](#pgvectorstore-methods)
Beyond the `VectorStore` interface, `createPgvectorStore` returns:
| Method | Description |
| ------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `setupSql()` | Returns the DDL string that creates the extension, table (including the `content_hash` column), and indexes, and adds `content_hash` to tables created by older versions. Needs `dimensions`. |
| `ensureSchema()` | Creates the extension, table, and indexes when they’re missing, and adds `content_hash` to tables created by older versions. Idempotent — safe on every startup. An existing table is kept as it is, so when its width differs from `dimensions` this throws a `PgvectorDimensionMismatchError` (with `table`, `tableDimensions` and `dimensions`), instead of letting inserts fail later. Without `dimensions` it uses an existing table’s width, and throws when there’s no table. |
| `tableDimensions()` | The width of the existing table’s `embedding` column, or `undefined` when the table doesn’t exist. |
| `close()` | Closes the internal connection pool. No-op when an external client was supplied. |
| `count(filter?)` | Returns the number of stored chunks matching an optional filter. Useful for diagnostics. |
### `VectorStore` interface
[Section titled “VectorStore interface”](#vectorstore-interface)
Implement this to use a custom vector store (e.g. Qdrant, Weaviate, Pinecone, in-memory):
```ts
interface VectorStore {
upsert(records: UpsertRecord[]): Promise;
query(vector: number[], k: number, filter?: Filter): Promise;
delete(ids: string[]): Promise;
// Optional — stored content hashes for ids starting with `prefix`.
hashesByPrefix?(prefix: string): Promise>;
// Optional — every stored id for one schema (orphan pruning).
idsBySchema?(schemaId: string): Promise;
// Optional — identity recorded in schema.lock.json.
describe?(): { kind: string; location?: string; dimensions?: number; ephemeral?: boolean; widthHint?: string };
}
```
Persist `UpsertRecord.hash` and implement `hashesByPrefix` so the indexer can verify what your store holds. The hash covers the chunk text and the embedder id, and the indexer skips only chunks stored with the same hash. Without it, the indexer falls back to the hashes in `schema.lock.json`, and only trusts them when `describe()` reports the same store and dimensions as the lock. A store with neither `hashesByPrefix` nor `describe()` re-embeds every chunk on each run, because a fresh, empty instance can’t be told apart from the one the lock describes. Implement `idsBySchema` so chunks removed from the schema are pruned from your store without touching other schemas. Without it, the indexer prunes only the ids listed in the previous `schema.lock.json` and logs `askdb.rag.orphan_cleanup_limited`. Keep `describe().location` free of absolute paths: it is written to `schema.lock.json`, which you usually commit. Return `ephemeral: true` from a store that keeps nothing past the process, so the indexer leaves the lock alone. `widthHint` is appended to the indexer’s width-mismatch error, to say how to give your store a different vector width. If a lock was written for another schema id (a renamed schema, or a lock copied from another schema’s directory), the indexer logs `askdb.rag.lock_schema_mismatch`, reindexes without it, and deletes none of the ids it lists; remove an old schema id’s chunks yourself with `idsBySchema` and `delete`.
***
## Chunking
[Section titled “Chunking”](#chunking)
### `loadChunkerSourcesFromDir(dir)`
[Section titled “loadChunkerSourcesFromDir(dir)”](#loadchunkersourcesfromdirdir)
```ts
import { loadChunkerSourcesFromDir } from "@askdb/rag";
const sources = loadChunkerSourcesFromDir("./my-app.schema");
```
Loads a v2 schema directory into `ChunkerSources`, including table markdown files, concepts, and tenant policy. **Prefer this over passing a bare schema object to `buildSchemaIndex`** — the markdown files are the richest source of semantic content for chunking.
The directory layout expected:
```plaintext
.schema/
schema.json
tables/
.md
concepts.md (optional)
tenant-policy.md (optional)
```
### `loadChunkerSourcesFromBundleJson(raw)`
[Section titled “loadChunkerSourcesFromBundleJson(raw)”](#loadchunkersourcesfrombundlejsonraw)
```ts
import { loadChunkerSourcesFromBundleJson } from "@askdb/rag";
const sources = loadChunkerSourcesFromBundleJson(bundleJsonString);
```
Loads a bundled schema JSON (produced by `askdb bundle`) into `ChunkerSources`. Use when markdown files are not available on disk but a bundle is.
***
## Core types
[Section titled “Core types”](#core-types)
### `Embedder`
[Section titled “Embedder”](#embedder)
```ts
type Embedder = (texts: string[]) => Promise;
```
Takes an array of text strings, returns an array of embedding vectors (one per text).
### `Retriever`
[Section titled “Retriever”](#retriever)
```ts
type Retriever = (params: {
question: string;
k?: number;
filter?: Filter;
}) => Promise;
```
### `Filter`
[Section titled “Filter”](#filter)
```ts
type Filter = {
schemaId?: string;
types?: ChunkType[];
refs?: string[];
};
```
### `Chunk`
[Section titled “Chunk”](#chunk)
| Field | Type | Description |
| ----------- | ----------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `id` | `string` | Stable, schema-scoped chunk id: `chunk::`, e.g. `chunk:my-app:table:public.orders#cql`. `%` and `:` in the schema id are percent-encoded (`shop:eu` → `chunk:shop%3Aeu:…`). Unchanged across re-indexes. |
| `type` | `ChunkType` | Semantic kind of this chunk. |
| `text` | `string` | The text that gets embedded. |
| `schemaId` | `string` | The schema this chunk belongs to. |
| `refs` | `string[]` | Schema v2 ids referenced by this chunk (table ids, column ids, etc.). |
| `sensitive` | `boolean` | `true` when the chunk carries content that belongs to or mentions a sensitive table/column. That content is only emitted with `includeSensitiveDescribable: true`. |
### `ChunkType`
[Section titled “ChunkType”](#chunktype)
`"table"` | `"column"` | `"cql"` | `"question"` | `"concept"` | `"relationship"` | `"tenant-policy"`
### `QueryResult`
[Section titled “QueryResult”](#queryresult)
```ts
type QueryResult = {
id: string;
score: number; // similarity score (higher = more relevant)
payload: {
id: string;
type: ChunkType;
text: string;
schemaId: string;
refs: string[];
sensitive: boolean;
};
};
```
***
## Read next
[Section titled “Read next”](#read-next)
[**RAG for large schemas**End-to-end guide: when to use RAG, store setup, and retrieval tuning.](/guides/rag-for-large-schemas/)[**@askdb/core API**`ask()` options including `retriever` and retrieval thresholds.](/reference/core-api/)
# Studio
> A local browser UI for enriching your schema and testing questions — the fastest way to see AskDB work.
Visual tour
Studio is a local web app that reads and writes your schema artifact directly — nothing leaves your machine. Launch it from your project root and your browser opens a seven-view UI for enriching tables, defining concepts, configuring tenant isolation, and testing natural-language questions against the SQL they generate.
```bash
npx askdb studio
```
Studio reads `outputDir` from `askdb.config.ts`. Pass `--schema ` to override for a single run. By default it serves on `http://127.0.0.1:5556` — change that with the `--port` and `--host` flags, or set `studio.listen.port` and `studio.listen.host` in `askdb.config.ts` (a CLI flag overrides the config for that run).
## Guided setup
[Section titled “Guided setup”](#guided-setup)
Studio also works as the *first* command in a brand-new project. Run `npx askdb studio` in a directory with no `askdb.config.ts` (or no schema artifact yet) and Studio opens a setup wizard instead of erroring:
1. **Pick your database engine and AI provider.** The wizard asks for environment variable *names* only — it never accepts secret values. Studio writes `askdb.config.ts` and an `.env.example` for you.
2. **Add your secrets to `.env` yourself.** The wizard shows exactly which variables to fill in (for Azure OpenAI and Foundry, that includes `AZURE_RESOURCE_NAME`); the values stay on your disk.
3. **Run introspection from the browser.** Studio reads your schema structure server-side (tables and columns — never rows) and opens the Overview when it’s done.
If `askdb.config.ts` exists but fails to load (a syntax error, or its dependencies aren’t installed yet), Studio prints a warning with the load error in the terminal and starts without it. The wizard never overwrites an existing config: fix the file and restart Studio.
Setup actions (writing the config, running introspection) only work from loopback clients. If you bind Studio to a non-localhost host, it refuses setup requests from other machines. It still accepts their table, concept, and tenant-policy edits and query execution (see [Security model](#security-model)). Prefer the terminal? `npx askdb init` is the same wizard as a CLI prompt.
## The loop
[Section titled “The loop”](#the-loop)
The core Studio workflow is **enrich → ask → re-enrich**: add descriptions, aliases, and example questions to a table, then switch to the Playground and ask a question to see the generated SQL. If the answer isn’t what you expected, go back, tighten the enrichment, and re-ask — all without leaving the browser tab. Repeating this loop is what makes generation reliable for the vocabulary your team actually uses.
## Overview
[Section titled “Overview”](#overview)
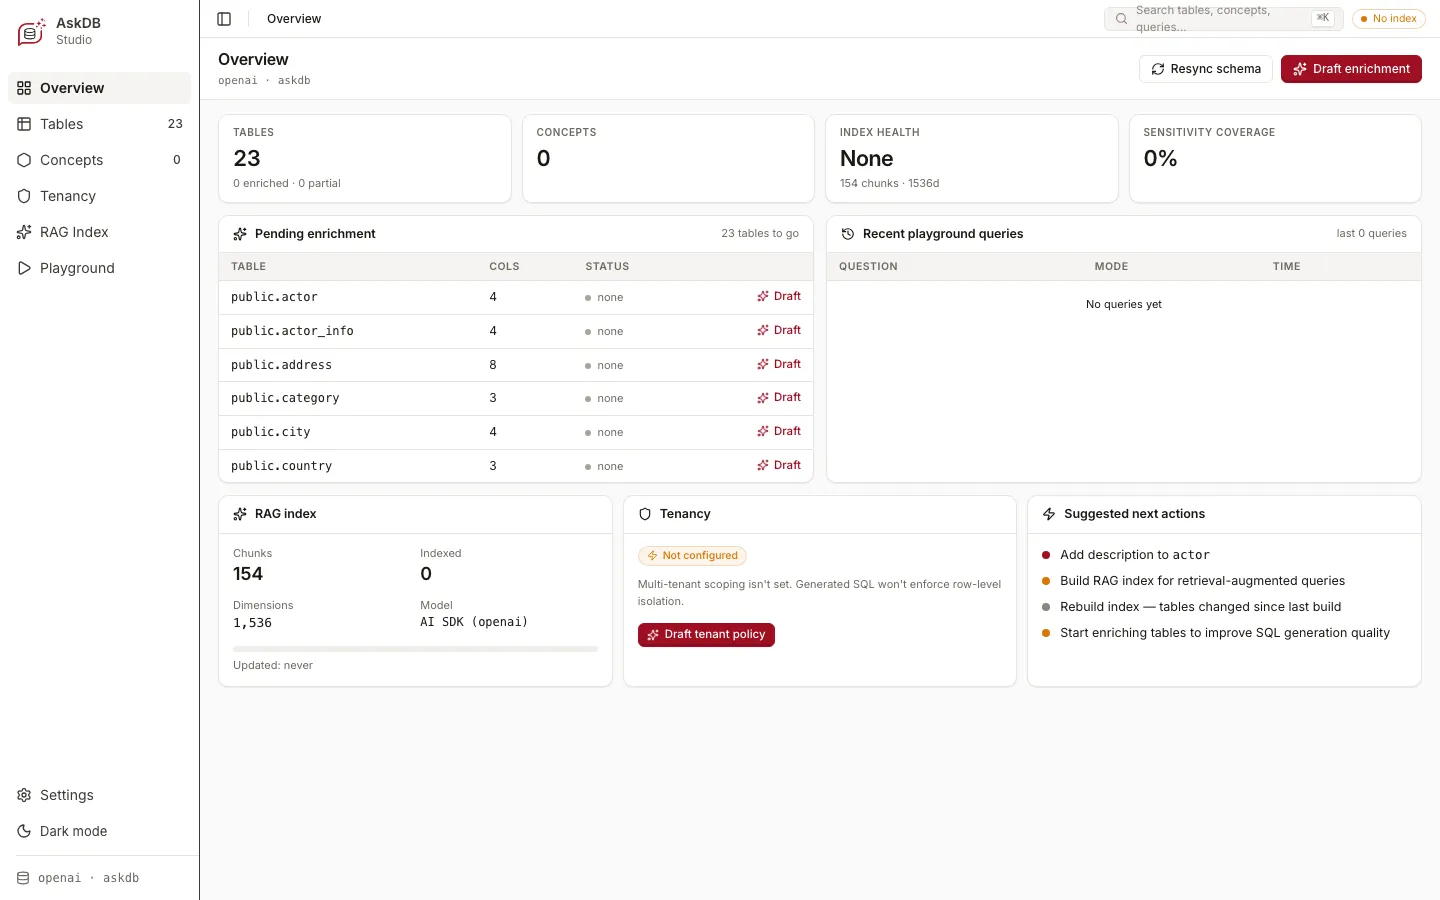
The Overview dashboard shows the health of your schema artifact at a glance: how many tables are enriched, how many are still at the default “none” state, RAG index status (chunk count and model), tenancy configuration, and a prioritised list of suggested next actions. Use it as your starting point to see where enrichment effort will have the most impact.
**Resync schema** re-runs introspection without leaving the browser, using the connection configured in `askdb.config.ts` — the same resolution as a flag-free `askdb introspect`. The physical layer (`schema.json`) is regenerated; your enrichment markdown is preserved, exactly as with the CLI. Like the setup wizard, resync only works from loopback clients.
## Tables and enrichment
[Section titled “Tables and enrichment”](#tables-and-enrichment)
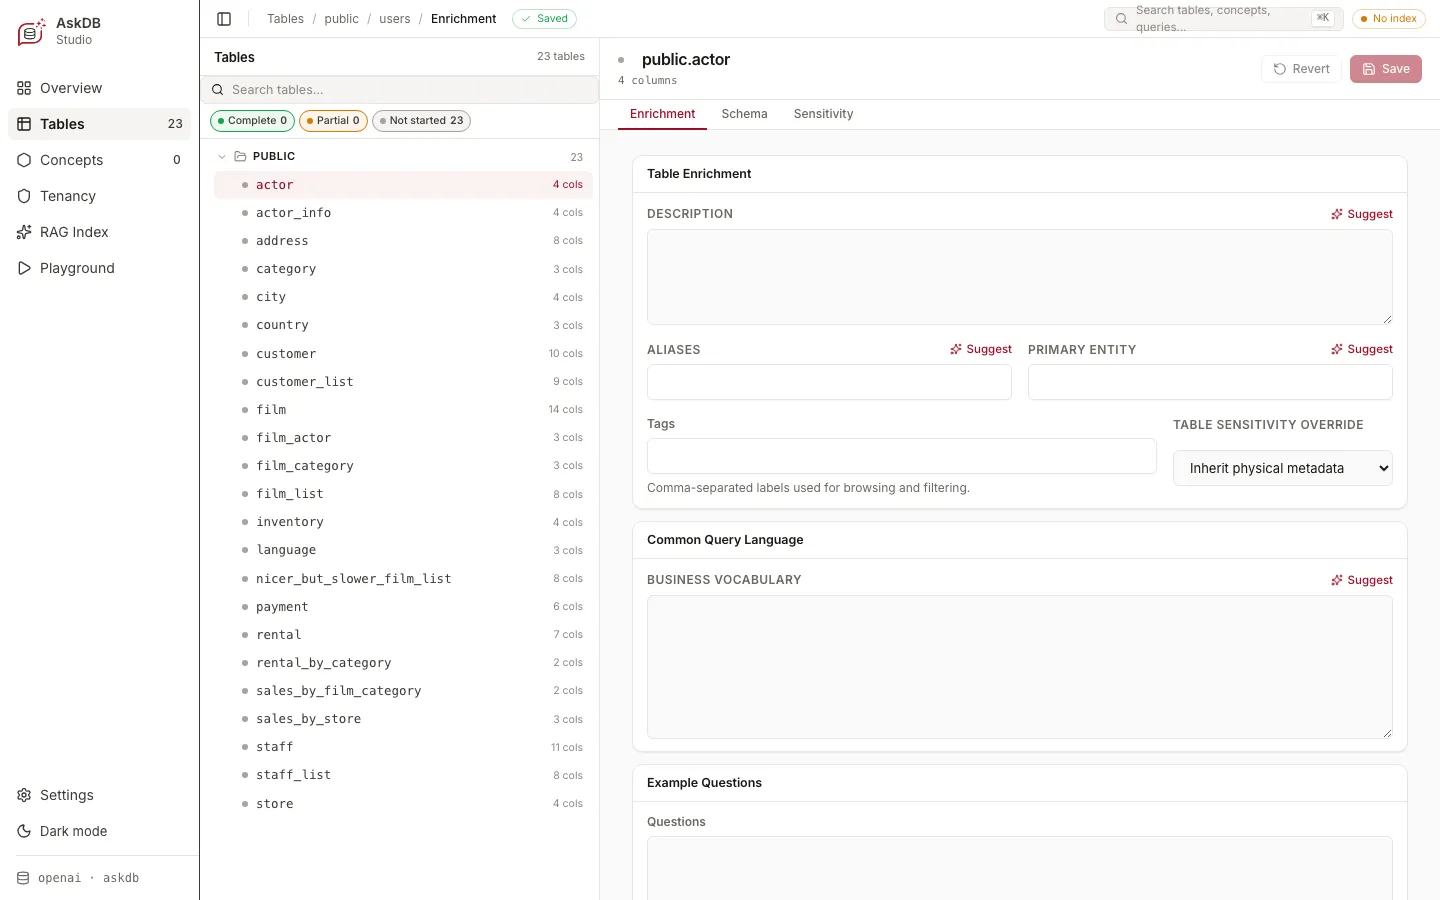
The Tables view lists every physical table in your schema. Select a table to open its detail panel with three tabs:
* **Enrichment** — write a description, set aliases (the names users actually use when asking questions), declare a primary entity, add comma-separated tags, capture business vocabulary in the Common Query Language field, and add example questions.
* **Schema** — view the raw column list with types and nullability.
* **Sensitivity** — mark tables, or columns like `email`, `ssn`, or `internal_notes`, as sensitive so the prompt layer can tag or omit them and `validateSensitiveReferences` flags SQL that touches them. Overrides are escalate-only: they can make something sensitive on top of the physical metadata, never less sensitive. The **Effective** column shows what AskDB will actually use, and “Not sensitive” is disabled (here and on the Enrichment tab) wherever it could not take effect.
Each field has a **Suggest** button: provide a model key and Studio drafts a proposal for your review. Suggestions are never applied automatically — a human confirms every change before it lands in the artifact.
## Concepts
[Section titled “Concepts”](#concepts)
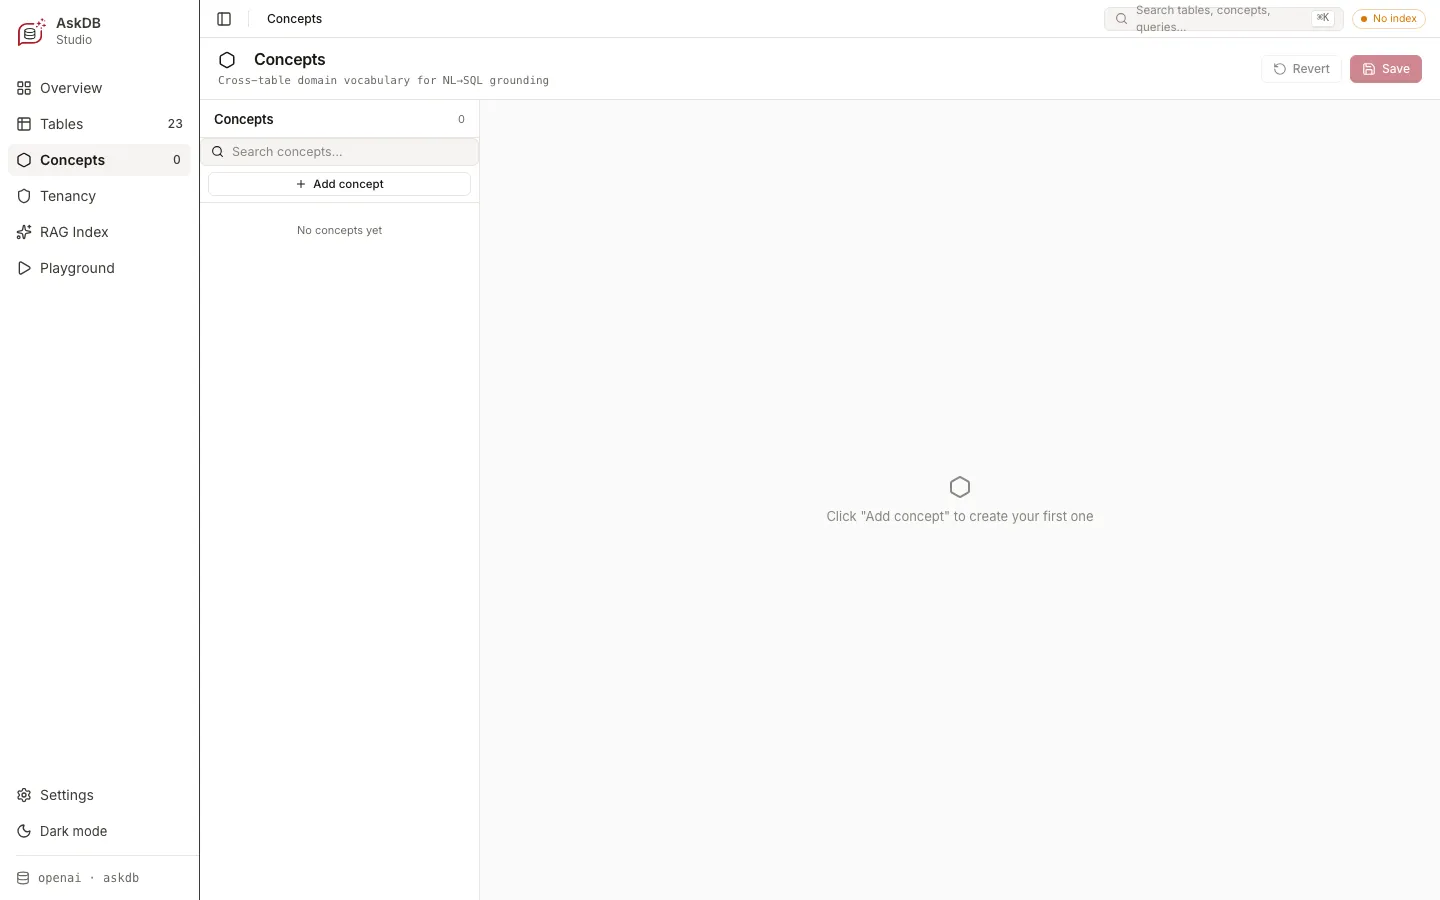
Concepts capture cross-table business vocabulary that doesn’t map to a single table — things like “active subscription”, “paid order”, or “customer” in a schema where that meaning spans several joined tables. Add a concept, write a description, and the model uses it when constructing prompts. Start with the terms your team reaches for most when they talk about the data.
## Playground
[Section titled “Playground”](#playground)
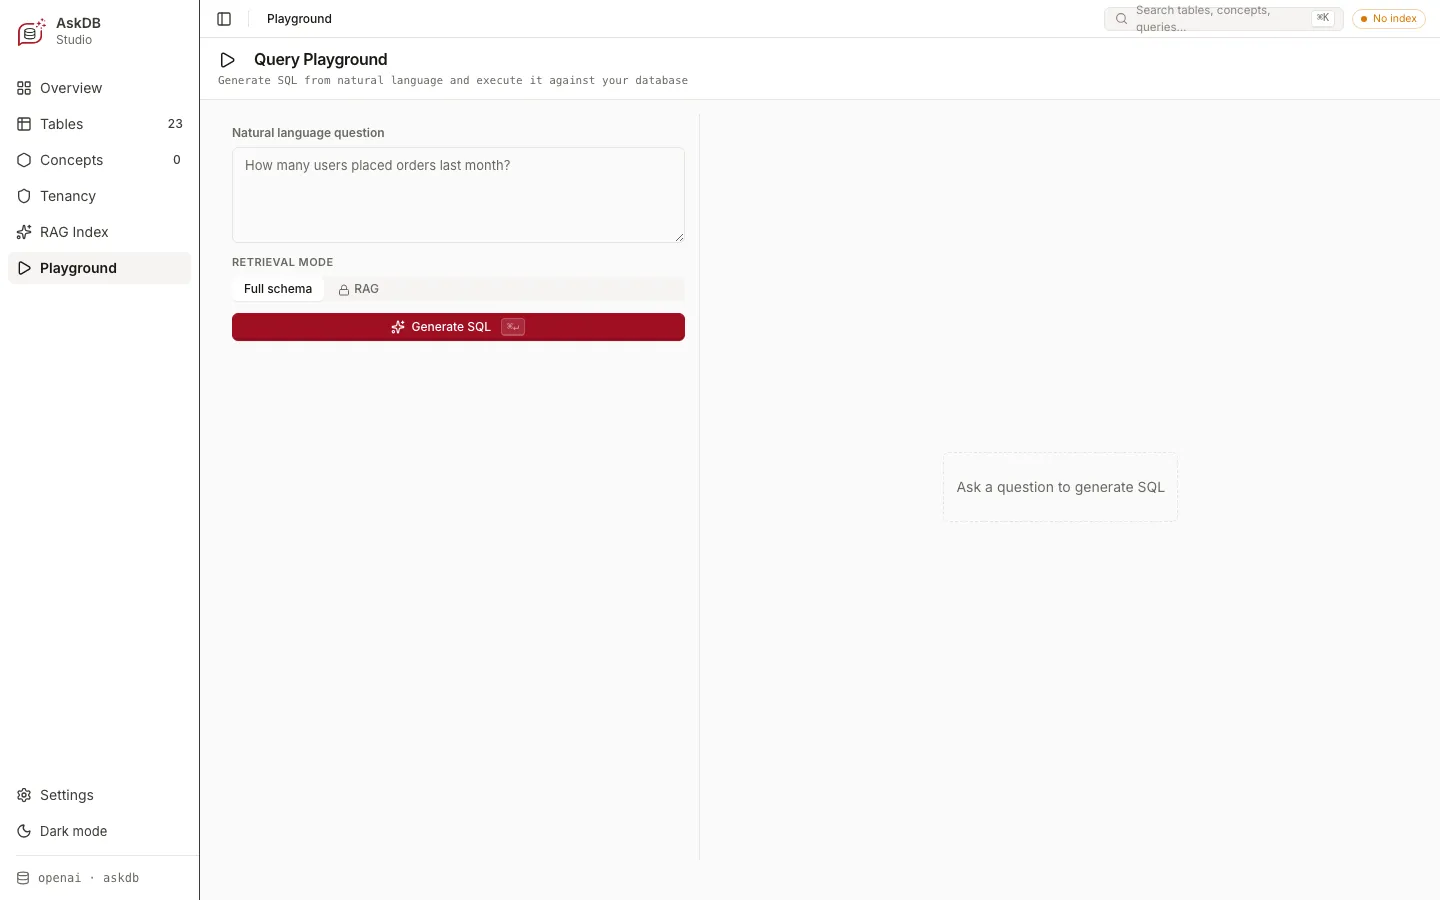
The Query Playground is where you test whether your enrichment is working. Type a question in plain language, choose between **Full schema** (send the entire enriched artifact) or **RAG** (retrieve only the relevant chunks), and click **Generate SQL**. The generated SQL appears alongside the retrieval context so you can see exactly what the model was given. If the SQL is wrong, the enrichment fields that need fixing are usually obvious from the context shown.
**RAG** mode searches the index you build on the **RAG Index** page, in the store `rag` configures. With `rag.embedder: "mock"` (what `askdb init` writes), Studio embeds with a local lexical embedder that needs no key. With `rag.embedder: "ai"`, it uses the [`ai.embedding`](/reference/config/#aiembedding) model, through that section’s connection only. With the pgvector store, the first build creates the table at the width the model returns (or `ai.embedding.dimensions`), and later builds refuse a table of another width, with a message naming the table and how to resolve it: drop the table and build again, point `rag.storeConfig.pgvector.table` at a new table, or set `ai.embedding.dimensions` to the table’s width if the model supports it. **Settings** shows which embedder is active. Changing the `ai.embedding` provider, model or dimensions marks the index stale: build it again before searching.
Generating SQL in Studio does not require a database driver. The optional **Execute Query** action runs the generated SQL against a live database and displays the results in the Playground. Studio supports Postgres, MySQL, SQLite, and SQL Server.
Execute is **off by default**. Until you turn it on, the Playground hides the Execute button and explains how to enable it, and `POST /api/execute` returns `403`. To turn it on, set `studio.execute.enabled: true` and give Studio its own connection, ideally a read-only database role, then restart Studio:
```ts
export default defineConfig({
studio: {
execute: {
enabled: true,
databaseUrl: env("STUDIO_READONLY_DATABASE_URL"), // or `file: "./data.db"` for SQLite
// timeoutMs: 30000, // per-query timeout (default 30 s)
// maxRows: 500, // row cap (default 500)
},
},
});
```
Studio doesn’t reuse your introspection connection unless you set `studio.execute.useIntrospectionConnection: true`. Choosing **Studio execute** in `askdb init` or the setup wizard writes `enabled: true` for you.
### Get the code
[Section titled “Get the code”](#get-the-code)
Once the SQL looks right, the **Get the code** panel below it turns the session into an integration snippet: your exact question, schema path, resolved dialect, configured AI provider, and (when enabled) the tenant scope — rendered as ready-to-paste TypeScript. Toggle between the config-driven style (`createAskDb()` from `@askdb/client`, reading the same `askdb.config.ts` Studio uses) and the direct style (`ask()` from `@askdb/core` with an explicit model). Copy it into your service and continue with [Embed in a Node app](/guides/embed-in-node/).
### Execute provider
[Section titled “Execute provider”](#execute-provider)
Studio automatically selects the execute provider from your config. When `studio.execute.provider` is not set, Studio uses the active introspection provider when it is a live engine (Postgres, MySQL, SQLite, or SQL Server). If the introspection provider is Prisma (schema-only), Studio defaults to Postgres for backward compatibility.
You can override the provider explicitly in `askdb.config.ts`:
```ts
export default defineConfig({
studio: {
execute: {
enabled: true,
provider: "mysql", // "postgres" | "mysql" | "sqlite" | "sqlserver"
databaseUrl: env("MYSQL_READONLY_URL"), // for network databases
// file: "./local.db", // for SQLite
},
},
});
```
See [Configuration — Studio execute](/reference/config/#studio-execute-configuration) for every field.
### Driver packages
[Section titled “Driver packages”](#driver-packages)
Each execute provider requires its database driver package. These are optional peer dependencies — you only install the one you need:
* PostgreSQL
* npm
```bash
npm install pg
```
* pnpm
```bash
pnpm add pg
```
* yarn
```bash
yarn add pg
```
* MySQL
```bash
npm install pg
```
* SQLite
```bash
pnpm add pg
```
* SQL Server
```bash
yarn add pg
```
* npm
* npm
```bash
npm install mysql2
```
* pnpm
```bash
pnpm add mysql2
```
* yarn
```bash
yarn add mysql2
```
* pnpm
```bash
npm install mysql2
```
* yarn
```bash
pnpm add mysql2
```
* npm
```bash
yarn add mysql2
```
* pnpm
* npm
```bash
npm install better-sqlite3
```
* pnpm
```bash
pnpm add better-sqlite3
```
* yarn
```bash
yarn add better-sqlite3
```
* yarn
```bash
npm install better-sqlite3
```
* npm
```bash
pnpm add better-sqlite3
```
* pnpm
```bash
yarn add better-sqlite3
```
* yarn
* npm
```bash
npm install mssql
```
* pnpm
```bash
pnpm add mssql
```
* yarn
```bash
yarn add mssql
```
* npm
```bash
npm install mssql
```
* pnpm
```bash
pnpm add mssql
```
* yarn
```bash
yarn add mssql
```
When execute is enabled, the Query Playground shows the configured provider and driver readiness near the Execute button. If the driver is missing, Studio displays an **Install** button (local Studio only) or the exact manual install command.
Driver packages are optional peers, not hard dependencies. This keeps install size minimal: Postgres users do not pay for MySQL or SQL Server clients and vice versa. The packages are listed as dev dependencies in `@askdb/studio` for local package development and CI type-checking — that does not mean your application must install all of them.
## Tenancy
[Section titled “Tenancy”](#tenancy)
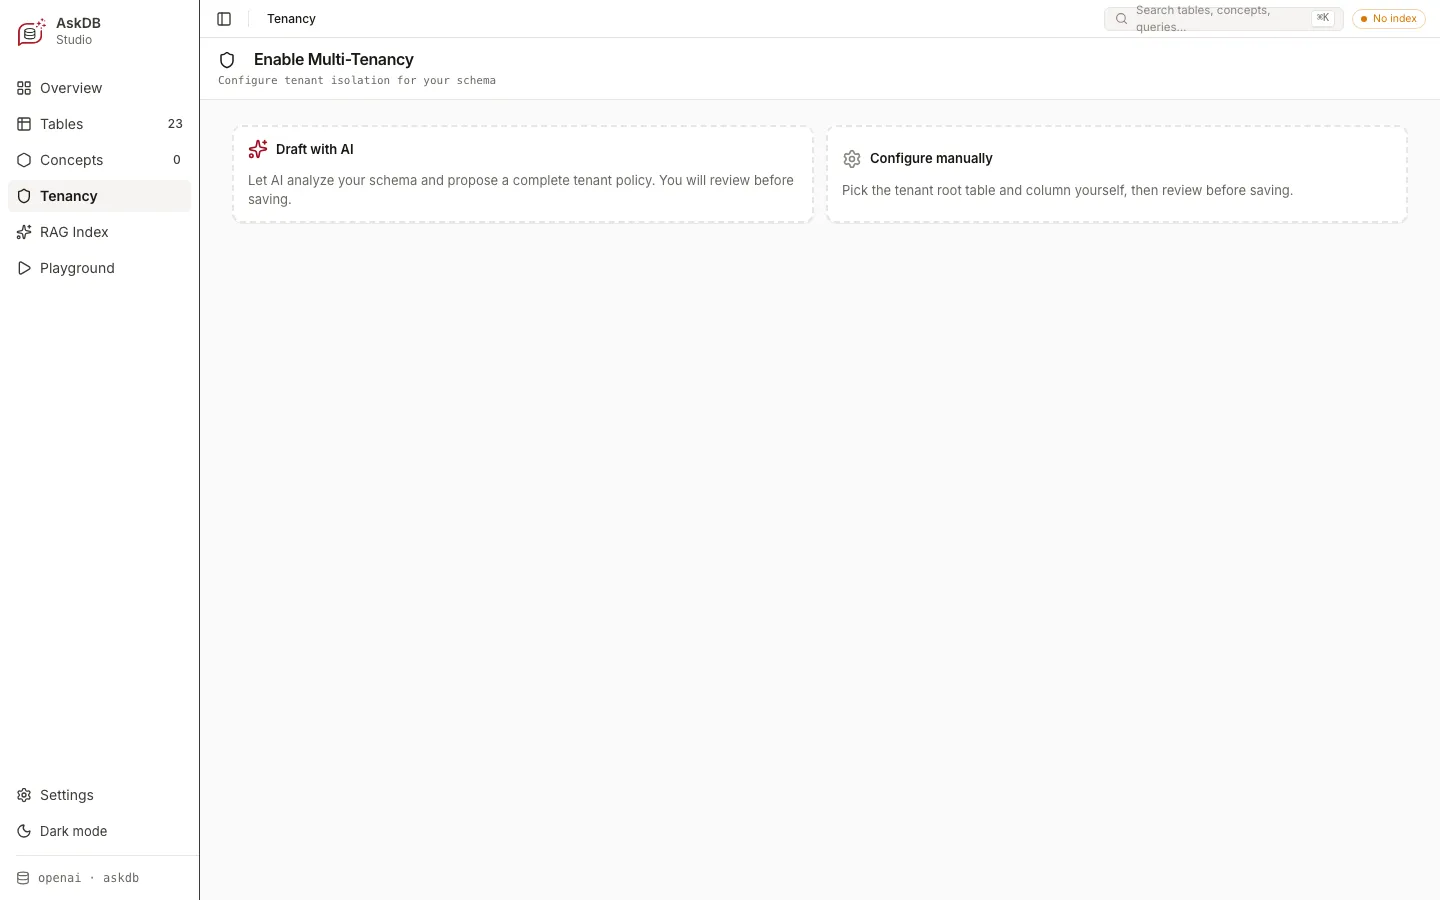
The Tenancy view is where you declare tenant isolation for multi-tenant schemas. Choose **Draft with AI** to let Studio analyse your schema and propose a tenant policy for your review, or **Configure manually** to pick the tenant root table and column yourself. Once configured, the Playground passes a tenant scope with each generated query, runs the same tenant check as `ask()`, and lets you test with different tenant IDs. Saving runs the same validation as loading the schema, so a policy AskDB couldn’t load (for example, two roots whose labels give the same placeholder) is refused with an error and nothing is written. See [Multi-tenancy](/guides/multi-tenancy/) for the full walkthrough.
## Studio and your data
[Section titled “Studio and your data”](#studio-and-your-data)
Studio binds to `127.0.0.1` by default — it is not reachable from outside your machine without an explicit host override. The model only ever sees schema text (table names, column names, descriptions, concepts): it never reads your actual rows. AI features — enrichment suggestions, tenant policy drafts, NL→SQL generation — are optional and only active when a model API key is configured in your environment.
## Security model
[Section titled “Security model”](#security-model)
Studio is a local developer tool, not a hosted service. Its API can run SQL against your configured database and write your schema files. Studio protects that API from other websites open in your browser:
* **Per-launch session token.** Each Studio launch generates a random token and injects it into the page it serves. The browser app sends it back as an `x-askdb-studio-token` header on every `/api/*` call; requests without the right token get `403`. Other websites can’t read Studio’s page, so they can’t get the token. Restarting Studio issues a new token, so reload any open Studio tabs after a restart.
* **Host check.** Studio accepts only a `Host` header of `localhost`, `127.0.0.1`, `[::1]`, or the host you bound with `--host`, and only on its own port. If you bound to `0.0.0.0`, it also accepts this machine’s own IP addresses. This check applies to every request, including the page itself, and blocks DNS-rebinding attacks.
* **Origin and content-type checks.** Studio rejects state-changing API requests whose `Origin` header points at another site, and API requests whose body isn’t `Content-Type: application/json`. So a web page can’t reach Studio with a simple cross-site form post or `no-cors` fetch.
* **Request size.** API request bodies over 1 MiB get `413`. Playground history keeps only known fields with length limits. Studio saves it to `playground-history.json` in the schema directory and adds that file to the directory’s `.gitignore` so it isn’t committed. If Studio creates the `.gitignore`, it also ignores `.env` files there.
Execute is off until you set `studio.execute.enabled: true` (see [Playground](#playground)). When it’s on, every query gets these guards:
* **Validated first.** Studio runs the same read-only SELECT check `ask()` uses (`validateSelectSql`, for the execute engine’s dialect) before anything reaches the driver. Multiple statements, comments, and write or DDL keywords are rejected with `400`. If the query reads a column marked `sensitive`, the result shows a warning but still runs.
* **One read-only statement.**
* Postgres runs the query as a single statement (extended query protocol) inside `BEGIN READ ONLY`, with `default_transaction_read_only` on.
* MySQL and MariaDB use a prepared statement inside `START TRANSACTION READ ONLY`.
* SQLite opens the file read-only, and the driver rejects multi-statement strings.
* SQL Server has no read-only transaction mode. Studio runs the query inside a transaction that it always rolls back, with `SET XACT_ABORT ON`. The query runs as part of a batch, and a second statement written without `;` (for example a second `SELECT`) isn’t caught by the SELECT check.
* **Timeout.** `studio.execute.timeoutMs` (default 30 s) is enforced with `statement_timeout` on Postgres, `MAX_EXECUTION_TIME` on MySQL (`max_statement_time` on MariaDB), and request cancellation on SQL Server. SQLite queries can’t be interrupted, so the timeout doesn’t apply to them.
* **Row cap.** Studio fetches at most `studio.execute.maxRows + 1` rows (default 500) and marks the result truncated when more exist. Postgres and MySQL wrap the query as `SELECT * FROM (…) AS askdb_q LIMIT n`, so a MySQL query that returns two columns with the same name needs aliases. SQL Server uses `SET ROWCOUNT`. SQLite stops reading at the cap.
These checks reduce risk, but they aren’t a sandbox. The SELECT check is heuristic, and a SELECT can still call functions with side effects. Point `studio.execute` at a **read-only database role**. On SQL Server, a read-only login is the only real guarantee.
Binding to a non-loopback host (`--host 0.0.0.0` or a LAN address) prints a warning at startup. Anyone who can load Studio from that address gets the session token from the page, so on that network they can edit your schema and execute queries. Setup, **Resync schema**, and the driver **Install** button still only work from loopback clients. Keep the default `127.0.0.1` unless you’re on a network you trust. Studio also expects to be reached directly: a reverse proxy that rewrites the `Host` header gets `403`.
## Read next
[Section titled “Read next”](#read-next)
[**Quickstart**Scaffold config, introspect a database, and run Studio end-to-end in under five minutes.](/quickstart/)[**Author your schema**The full enrichment workflow — descriptions, concepts, sensitive markers, and tenant policy.](/guides/author-your-schema/)[**Multi-tenancy**Declare tenant roots and row-level isolation in your schema artifact.](/guides/multi-tenancy/)[**RAG for large schemas**When your enriched artifact is too large for a single prompt context.](/guides/rag-for-large-schemas/)